Topic
Evaluation
9 stories on this topic, newest first.
IndustryAnalysis
What thousands of AI research agents contribute to a science project
Distributed biology agents widen analysis of existing experiments. Their economic value depends on data preparation, expert review and the next experiment.
ToolsExplainer
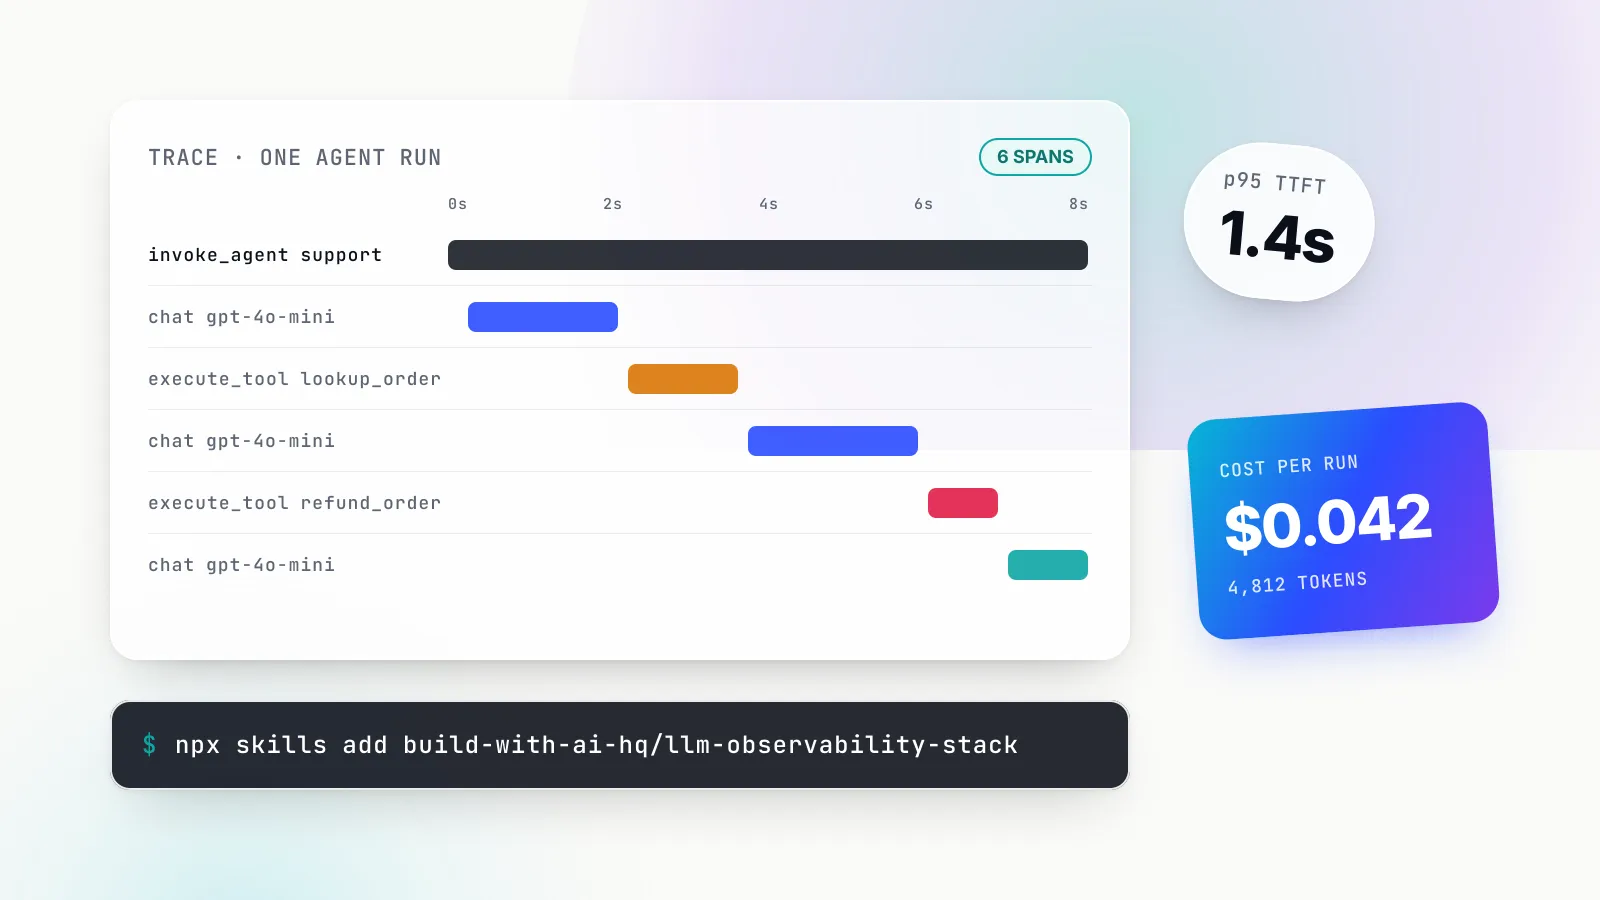
LLM observability: what to capture, how to trace agents, and which tools fit
A working guide to LLM observability: the per-call record, OpenTelemetry GenAI conventions, agent traces, PII redaction, Prometheus alerts, production evals and the tools for each job.
NewsAnalysis
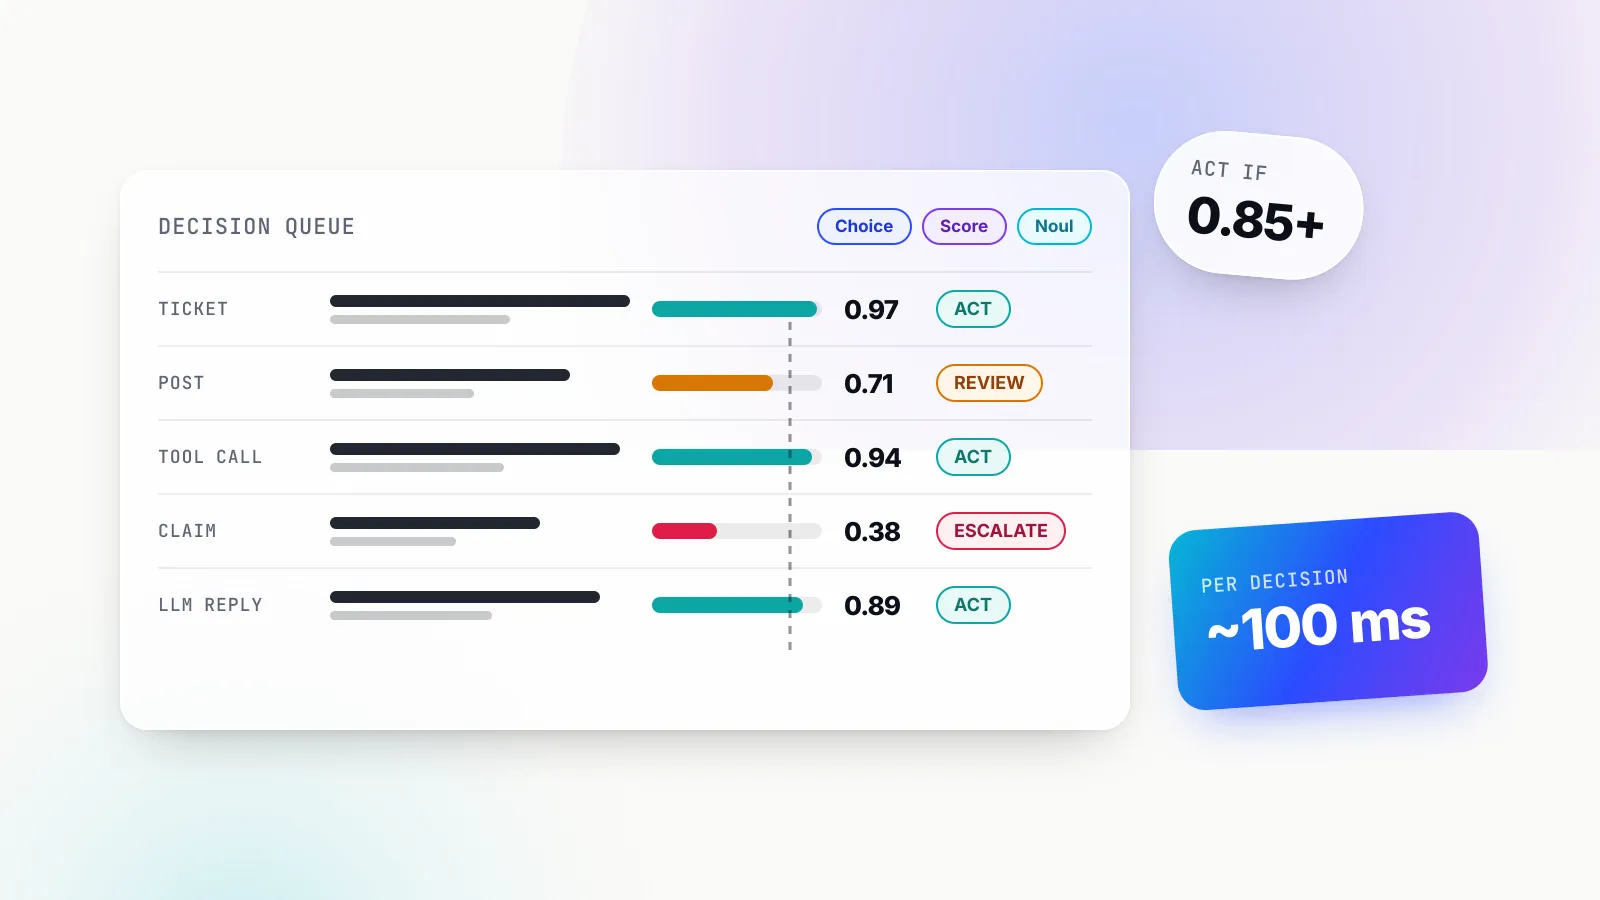
What Jev is actually for: seven jobs for a model that only decides
Two weeks after launch, TypeSafe's own docs and cookbooks show where a typed, calibrated decision model beats an LLM call, a classifier or plain rules, and where it plainly does not.
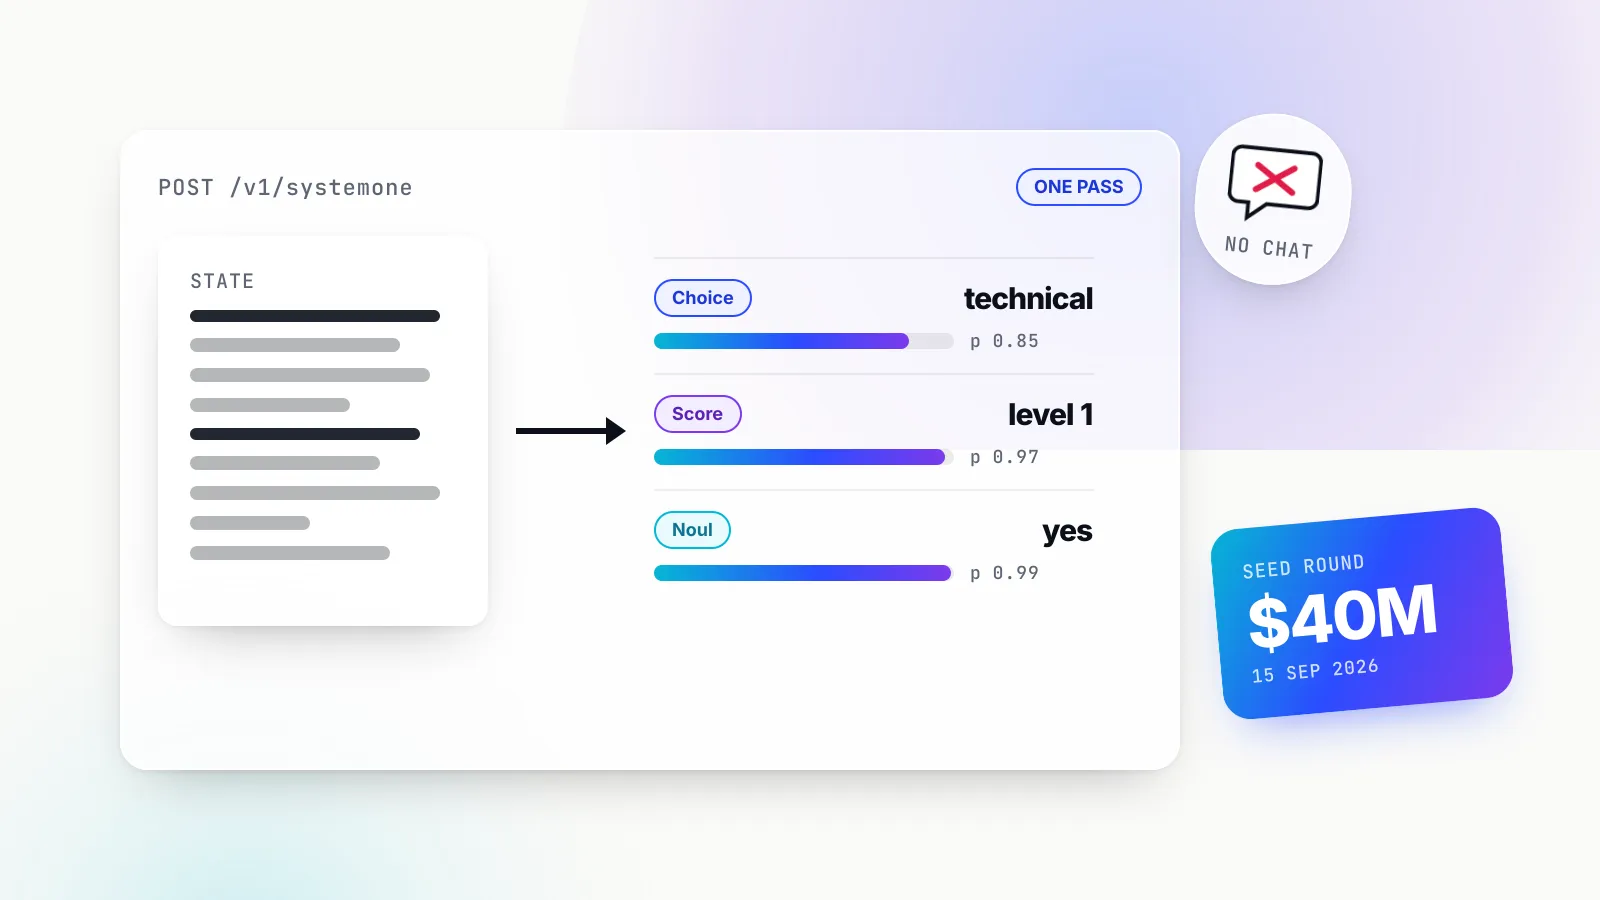
TypeSafe AI launches Jev, a $40M bet on AI that decides instead of chats
Jev takes text state and typed questions and returns calibrated probabilities in one pass, at $0.042 per million input tokens. What launched, who built it, and what the evidence shows so far.
IndustryExplainer
What are System One models, and will the category outlast Jev?
TypeSafe coined the term for models that return typed, probability-weighted decisions instead of text. Where the name comes from, how the mechanism differs, and what the economics mean.
ModelsExplainer
How to read a model card without being fooled: the 2026 field guide
System cards now run past 200 pages. We take five current cards apart section by section, show how one benchmark is reported five different ways, and set out a ten-step reading protocol.
ResearchExplainer
What reasoning models actually do: a training recipe and a token budget
Reasoning models are ordinary LLMs post-trained with RL on checkable problems, then given a thinking budget at inference. The lineage, the training loop, the costs, and where the gains actually land.
IndustryEditorial
Benchmarks became a marketing channel. Read the footnotes, then run your own
Launch tables report the same benchmark under different attempts, tools and thinking budgets. How measurement became collateral, what independent evaluators find, and how to run your own.
IndustryExplainer
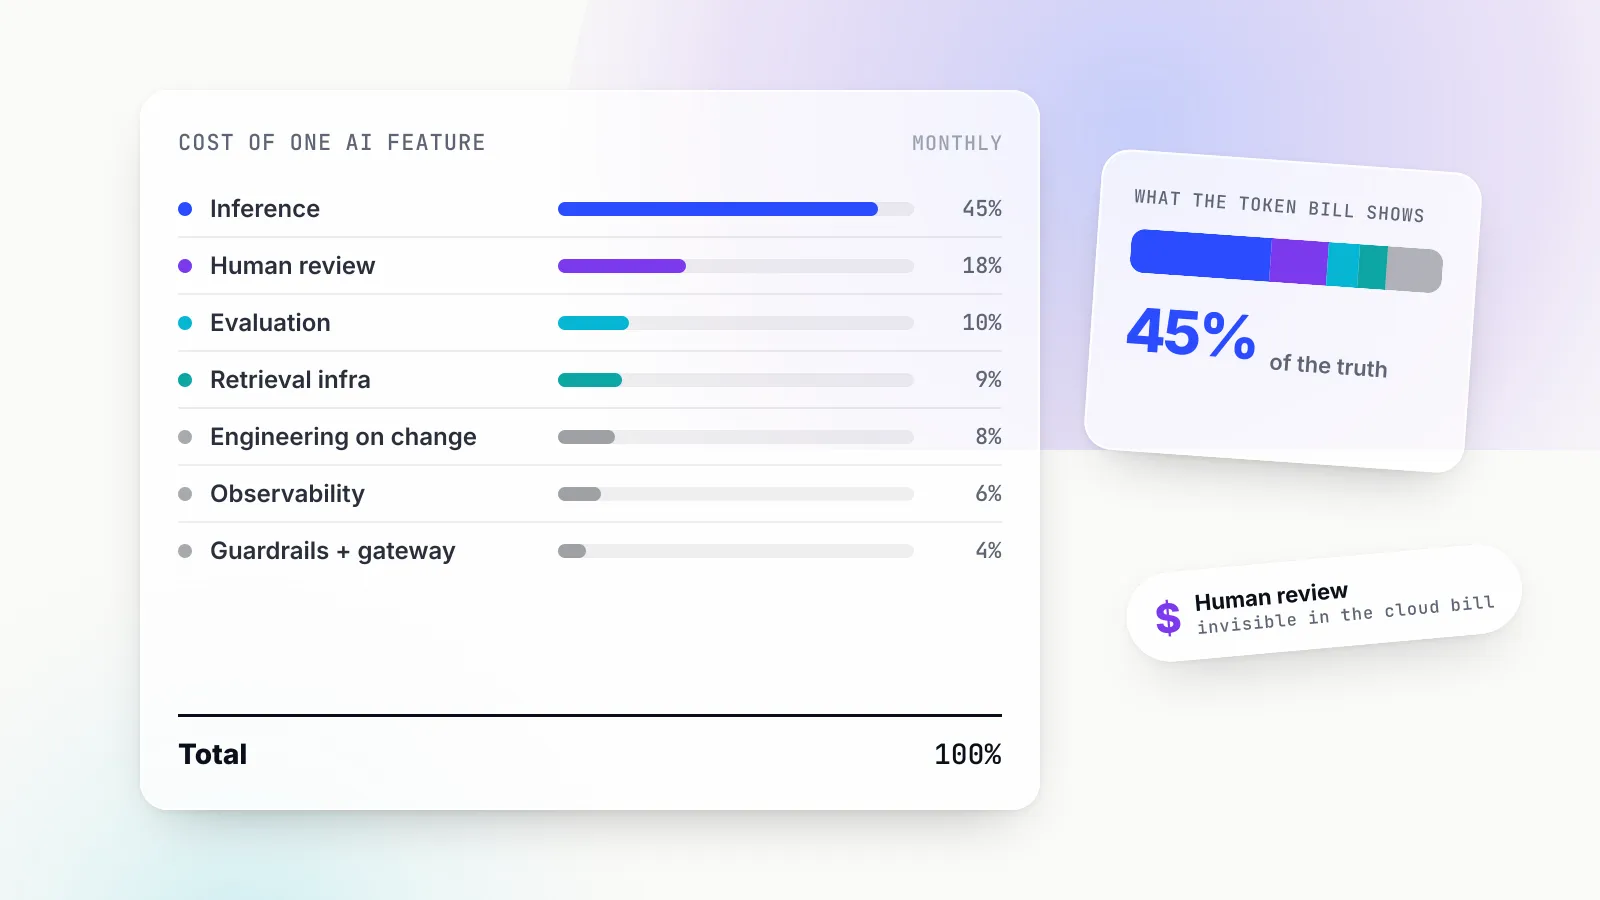
The real cost of an AI product, line by line: tokens are rarely the biggest line
A sourced ledger of what a production AI feature costs in September 2026: inference, retrieval, agents, evaluation, gateways, review and people, with a worked monthly model at three volumes.