Section
Tools
Developer tooling, agents, evaluation, gateways and the software stack around generative AI, tested and compared.
54 stories
Explainer
What Google's Deep Review can check in a technical document
Automated critique is useful when a flagged issue becomes a checkable claim. A practical guide to mathematical gaps, experimental mismatches and the evidence behind the tool.
Explainer
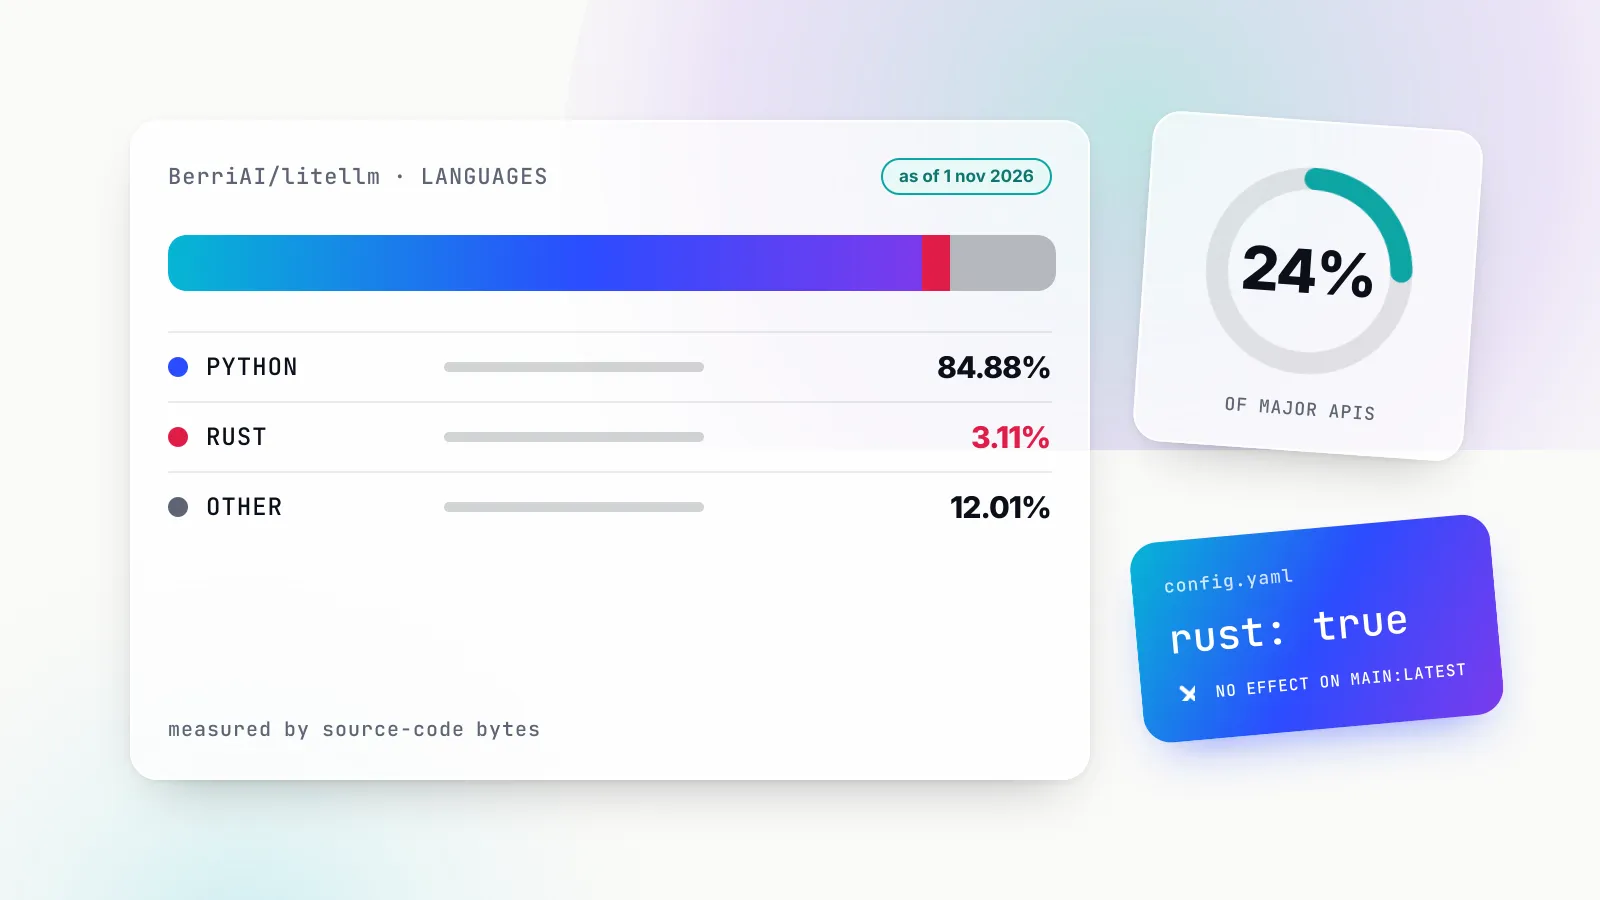
Is LiteLLM written in Rust? What the codebase and migration tracker show
LiteLLM Rust, checked: the repo is 3.11% Rust, the migration tracker shows 24% of Major APIs, and Chat Completions still runs on Python.
Analysis
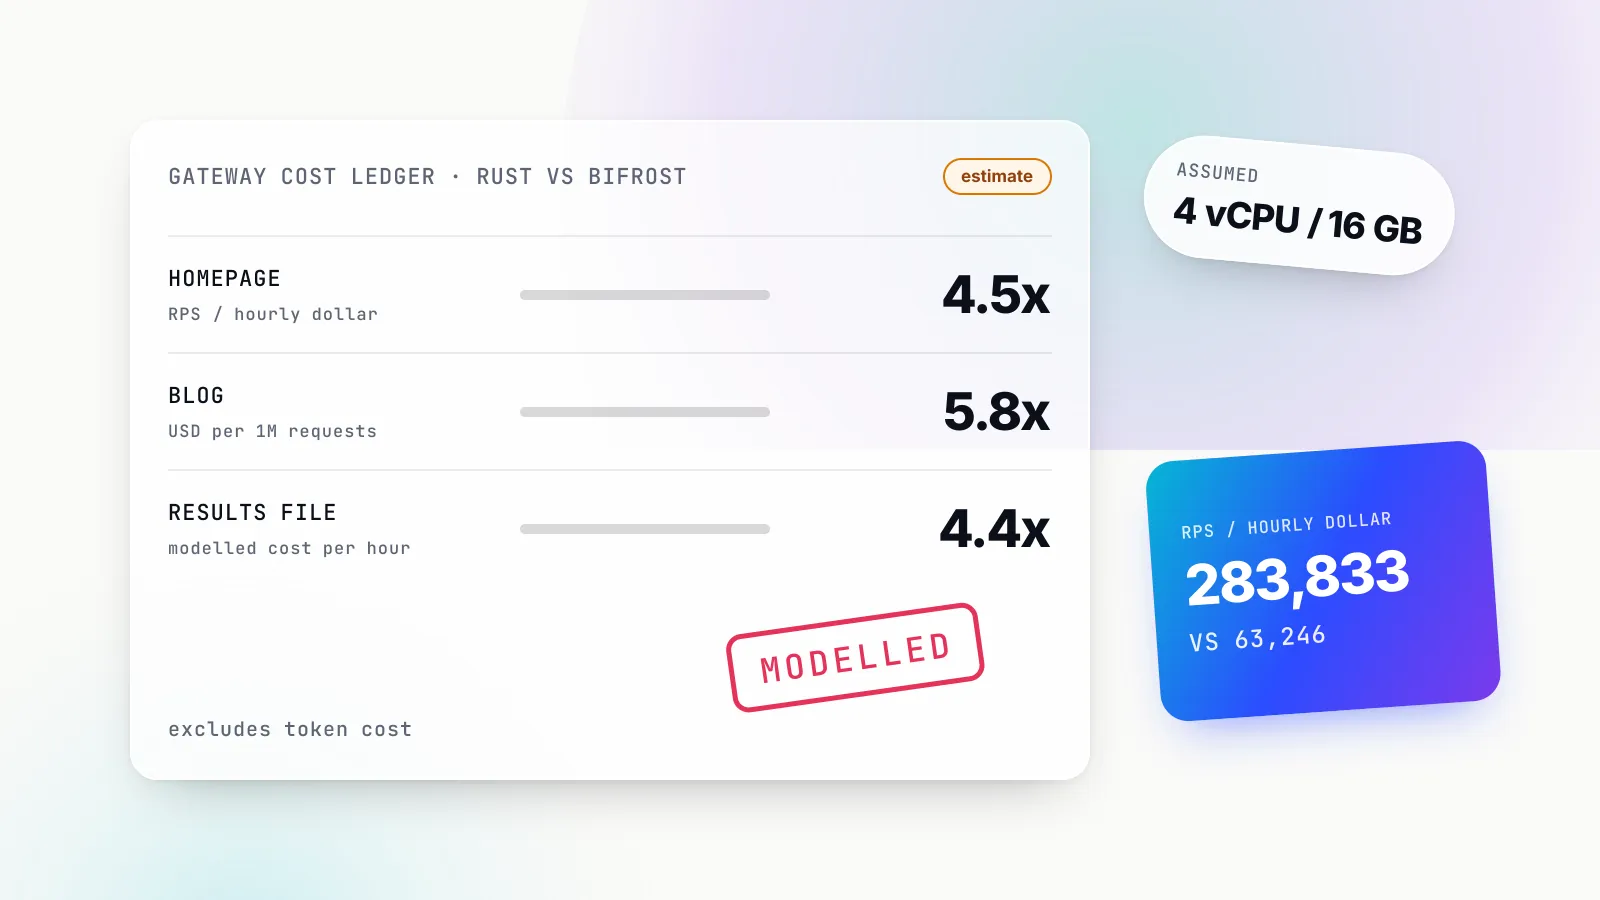
The '4.5x more requests per dollar' claim is a model, not a measurement
LiteLLM cost claims for its Rust gateway rest on an assumed 4 vCPU / 16 GB instance. What the 4.5x, 5.8x and 4.4x ratios measure, and what is missing.
Analysis
GPT-6.1 Terra and the shift from reading screens to acting on them
Terra targets visual reasoning and computer use. Four different task types explain why recognising a screen is only the start of useful application work.
Explainer
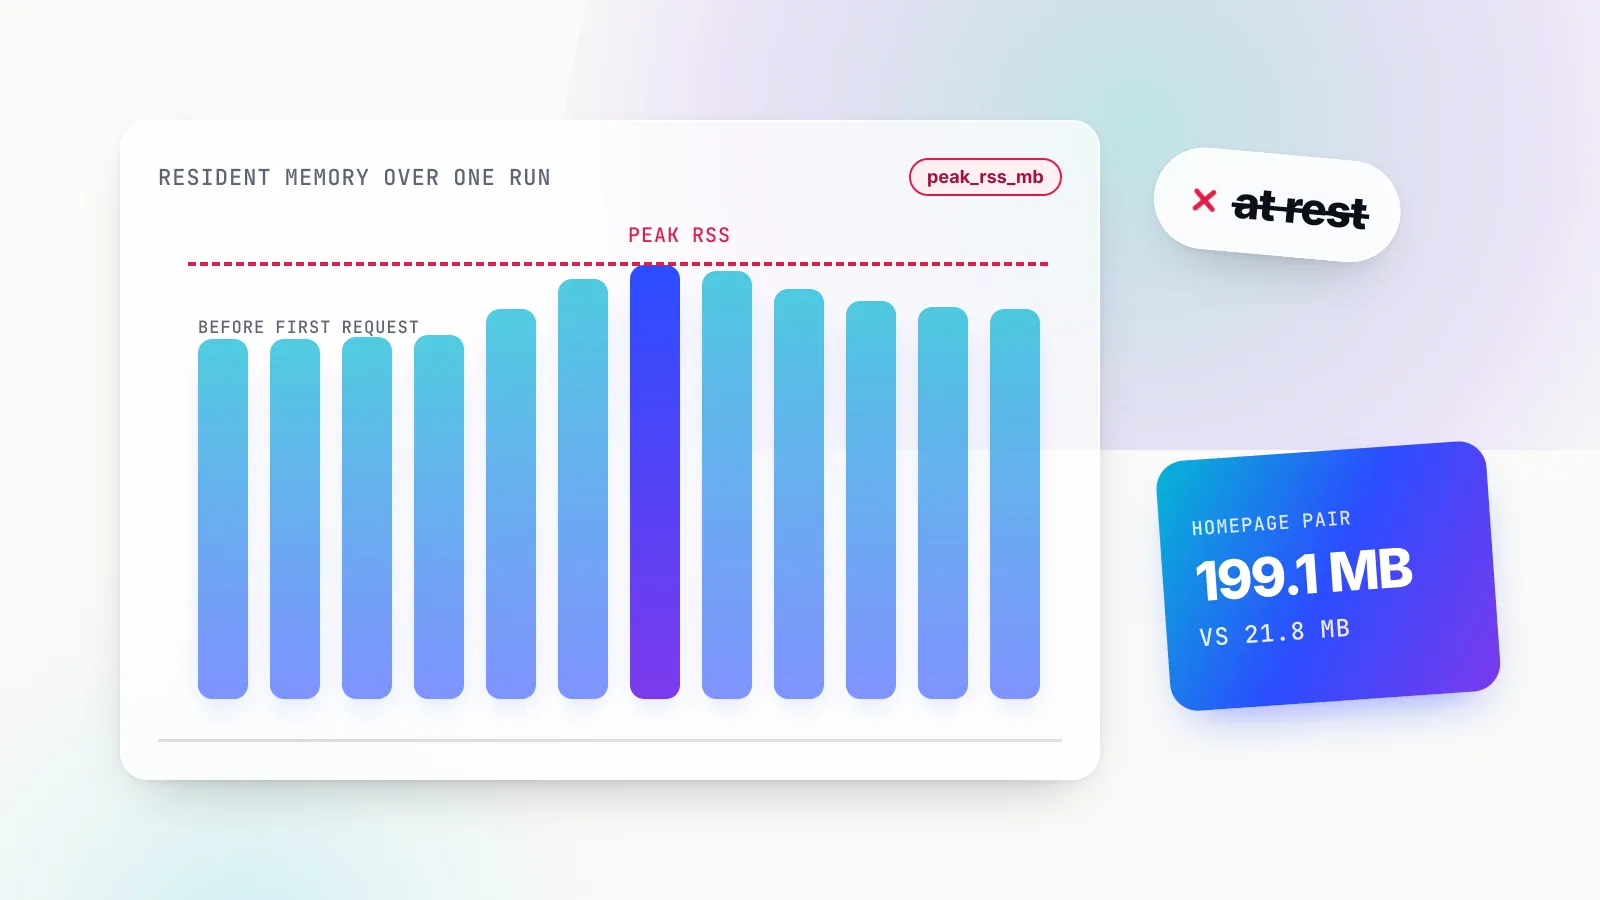
Peak RSS vs memory at rest: reading LiteLLM's '9x less memory' figure
LiteLLM's homepage labels its memory figure 'memory at rest', but the data is peak RSS. What the files show, why Bifrost sat near 282 MB, and how to read RSS.
Comparison
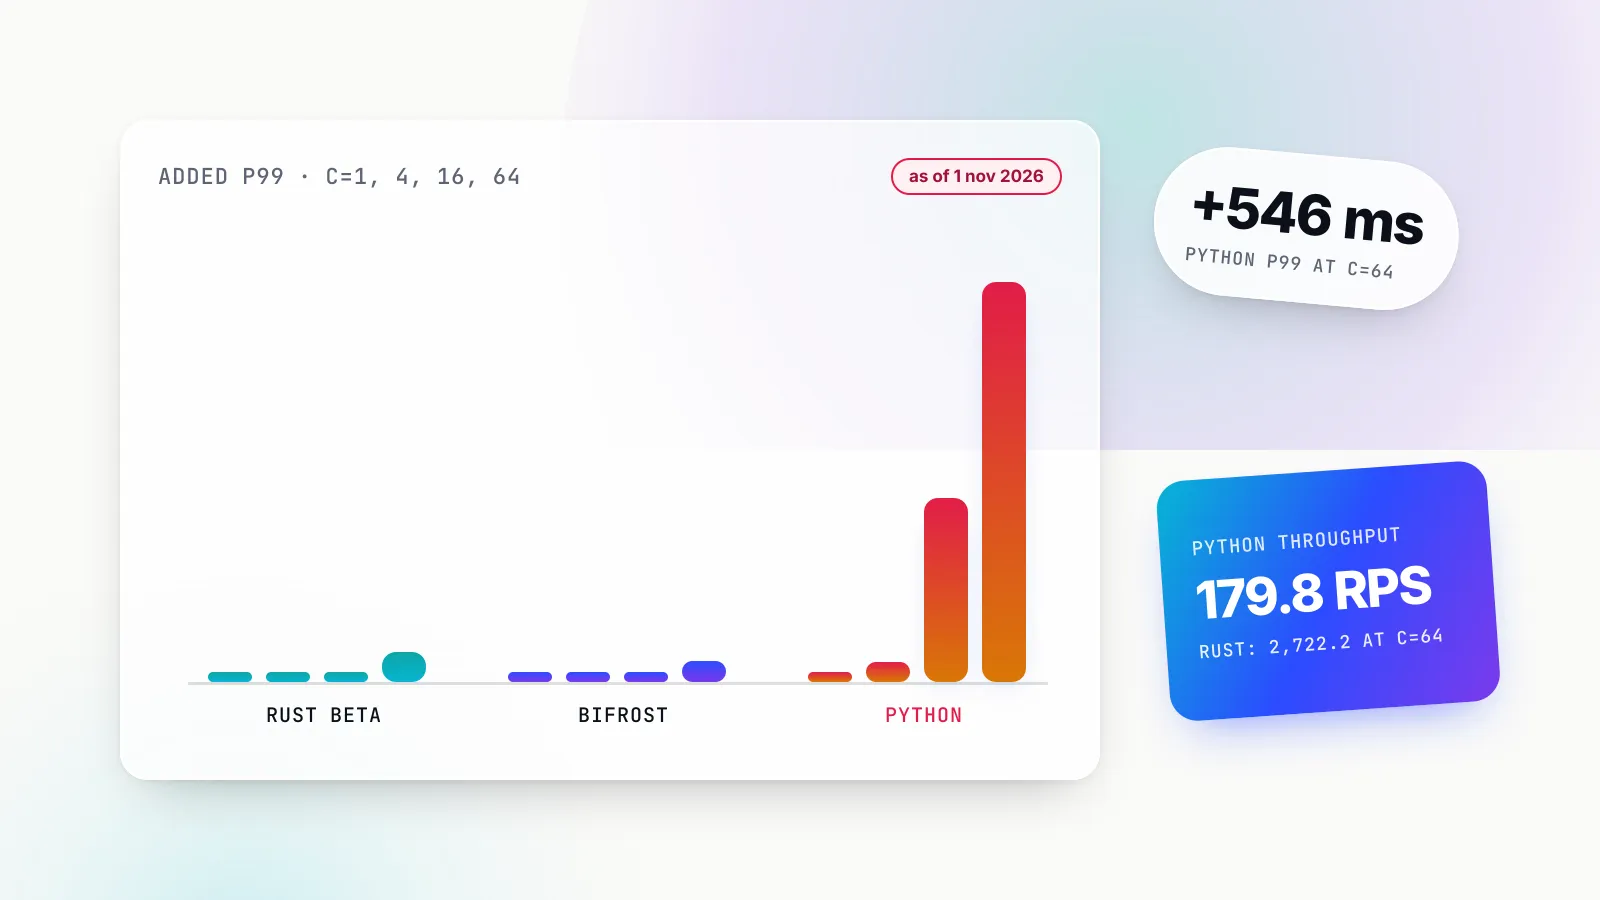
LiteLLM Rust vs LiteLLM Python vs Bifrost: what the data means for teams running LiteLLM today
In LiteLLM's own sweep the Python LiteLLM proxy adds 546 ms of p99 at c=64 and serves 179.8 RPS, and main:latest still runs chat routes on Python.
Analysis
Why OpenAI rebuilt the machinery behind Git
Coding agents multiply branches, pushes and checkouts. Pando's design shows why source-control capacity depends on coordination and reuse as much as storage.
Explainer
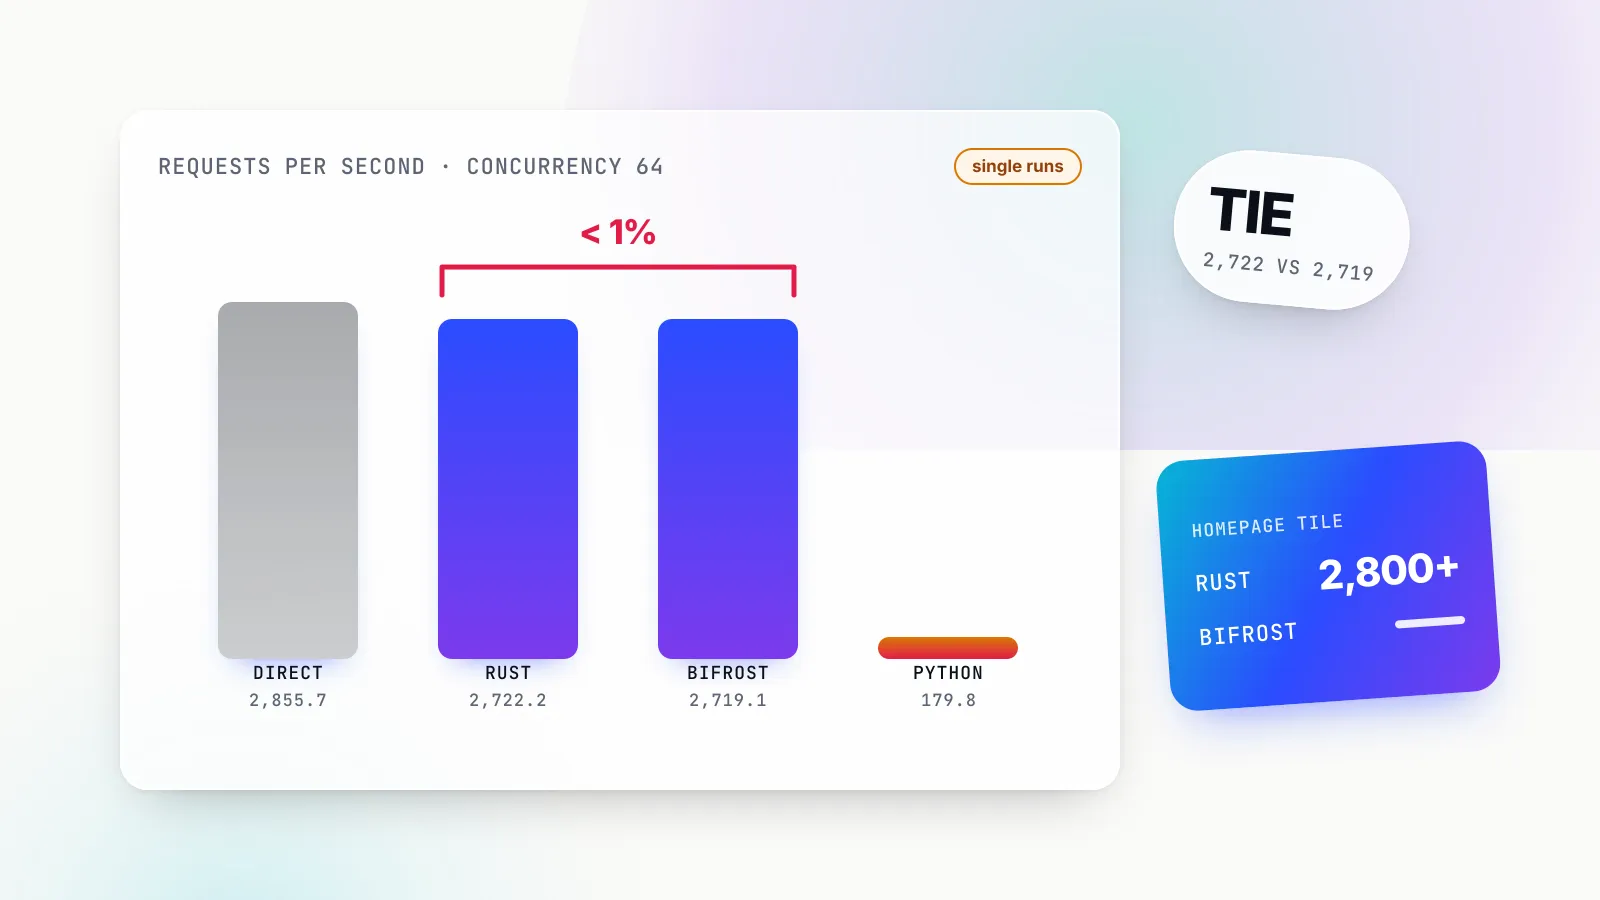
Throughput vs latency: why LiteLLM Rust and Bifrost tie at 2,722 vs 2,719 RPS
Throughput vs latency for LLM gateways: why 2,722 vs 2,719 requests per second is a tie, how RPS and p99 interact, and how to read a throughput tile.
Survey
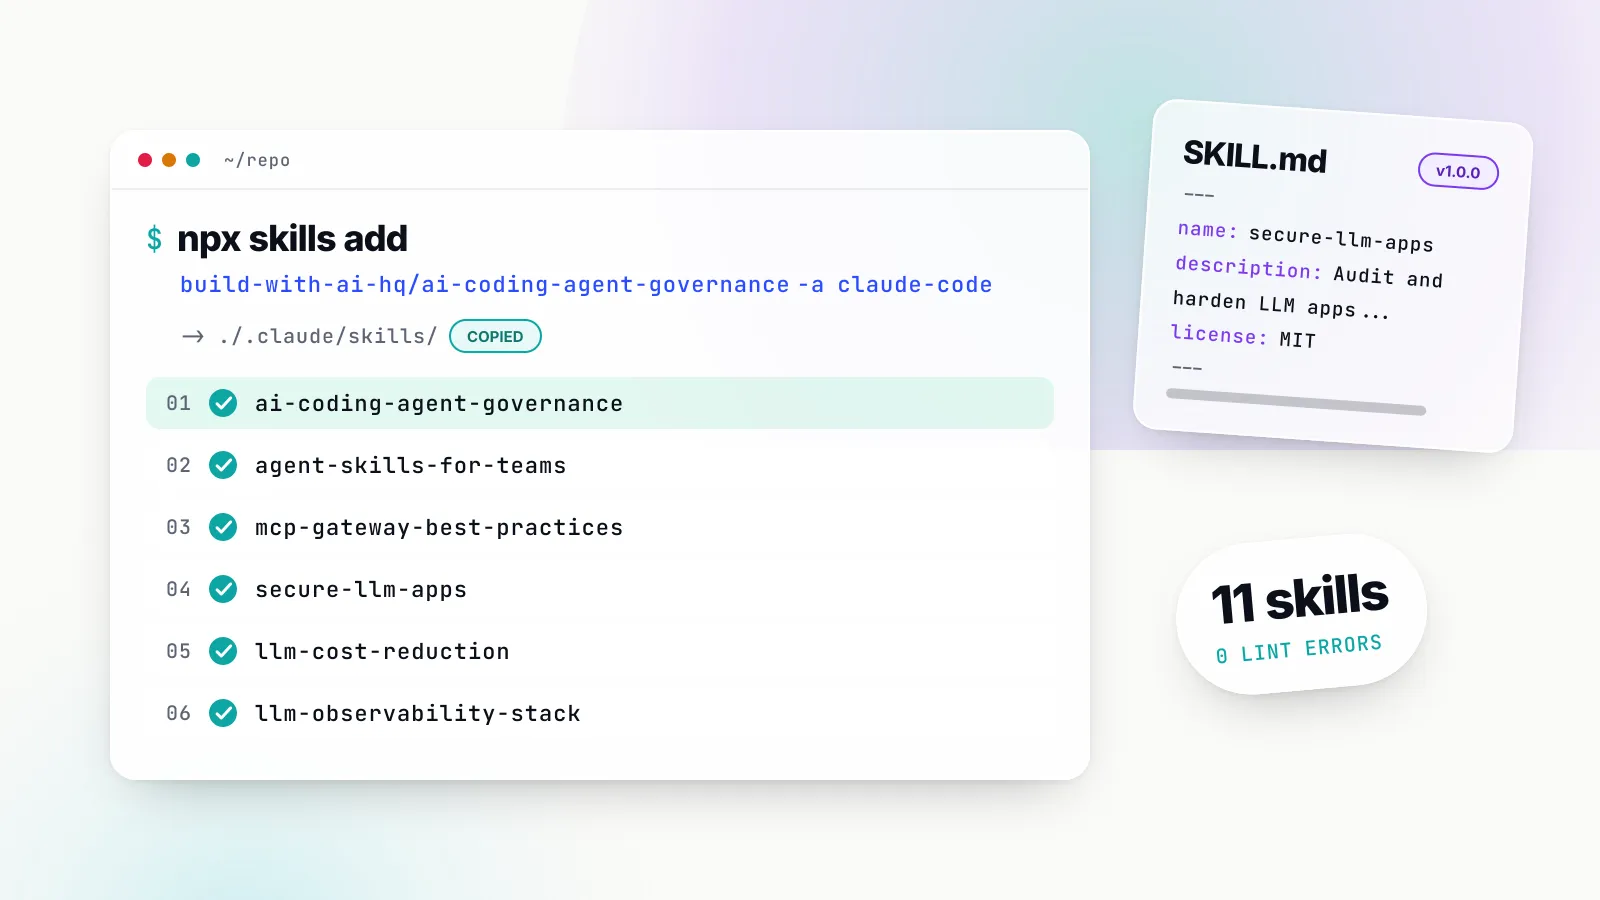
Best Claude Code skills in 2026: 11 tested and ranked for production AI teams
The best Claude Code skills for teams shipping production AI, test-installed on 28 October 2026: governance, cost, security, MCP and observability, plus five Anthropic and Vercel picks.
Explainer
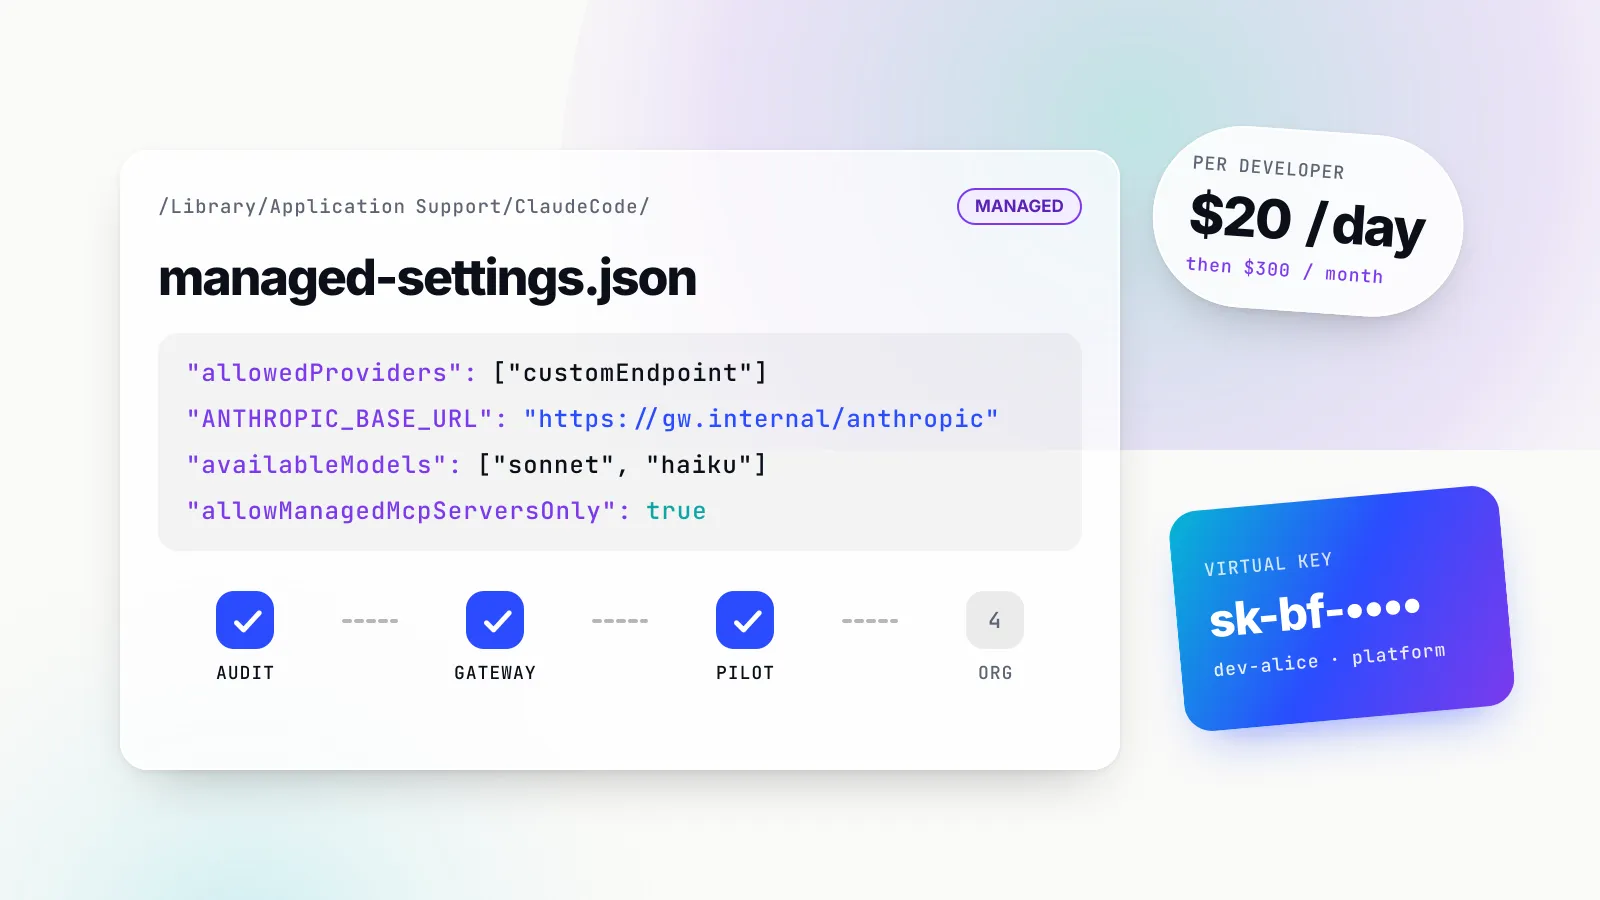
Claude Code enterprise rollout: a phased plan with budgets, managed settings and logs
How to roll Claude Code, Codex, Cursor and Copilot out to an engineering organisation: managed-settings.json, per-developer budgets, Bedrock residency, MCP allowlists, CI keys.
Explainer
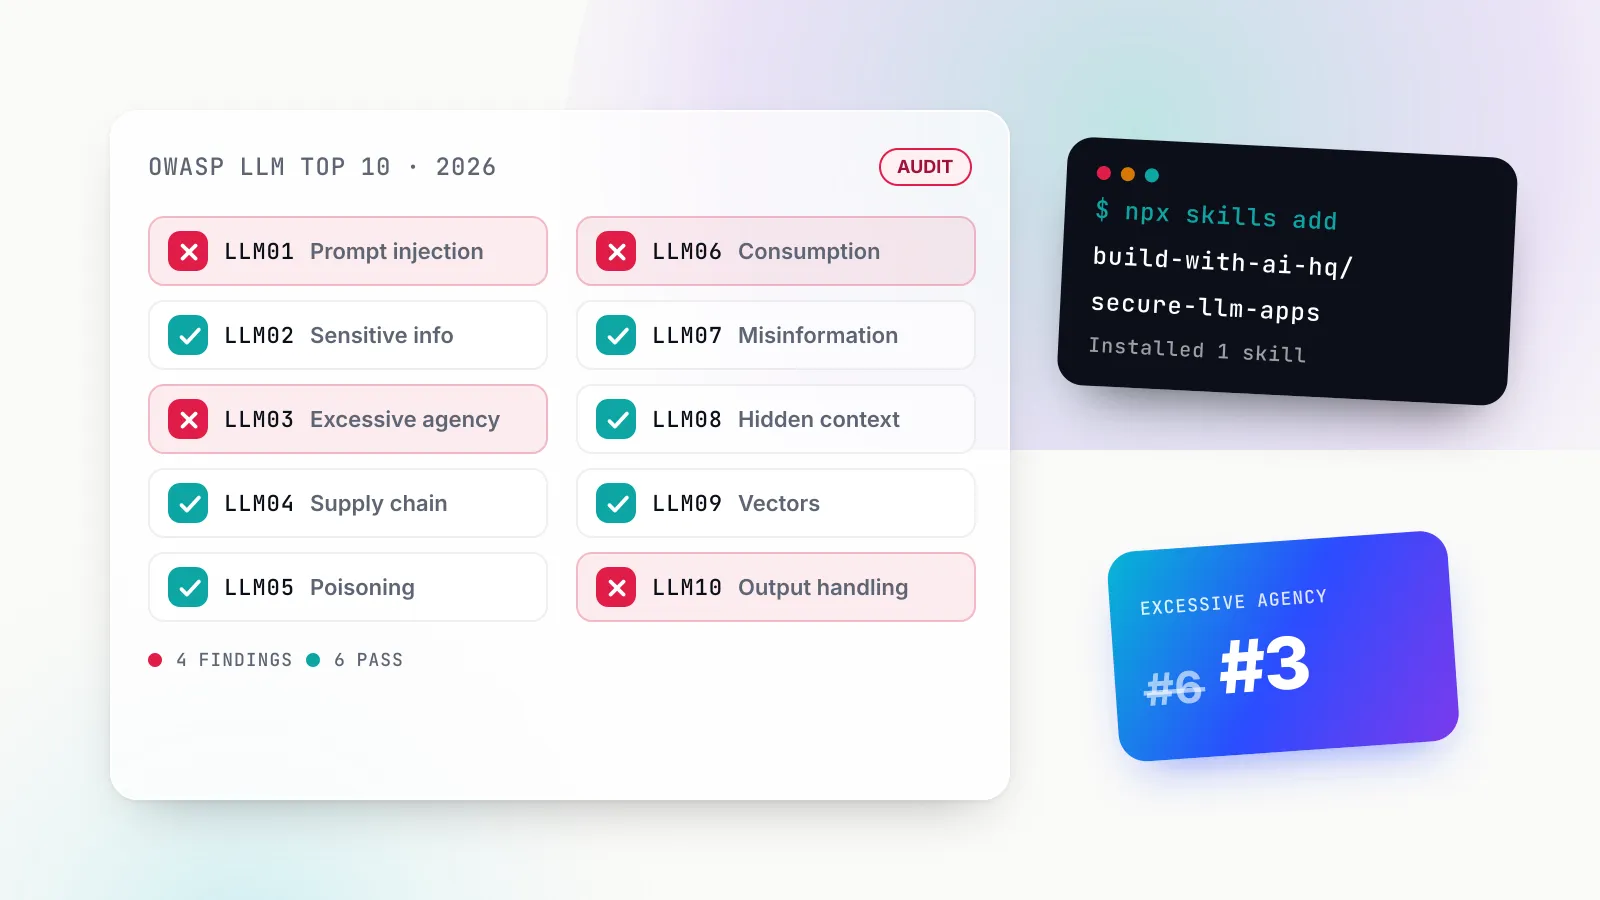
OWASP LLM Top 10 (2026): every risk, the vulnerable code and the fix
The 2026 OWASP LLM Top 10 reorders the list and renames one entry. Each risk with a vulnerable pattern, the Python or TypeScript fix, and an LLM security checklist.
Explainer
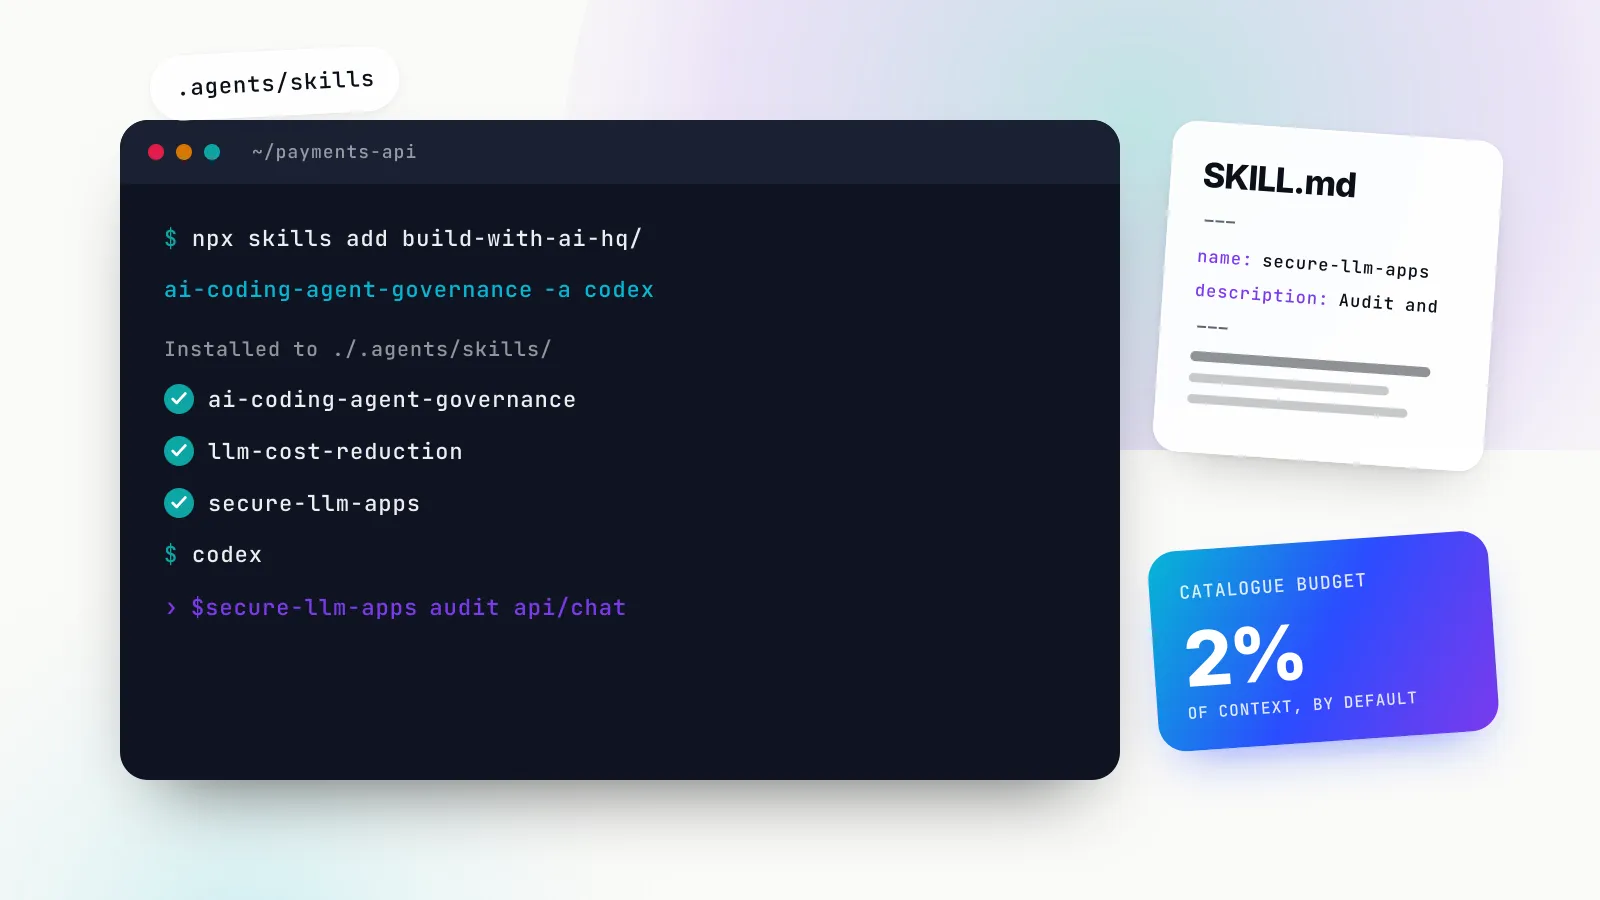
Codex skills: how Agent Skills work in OpenAI Codex, and which ones to install
Where OpenAI Codex discovers skills, how $skill and implicit invocation work, how skills differ from AGENTS.md, and how to add skills to Codex with npx skills add -a codex.