Topic
Inference
9 stories on this topic, newest first.
ToolsExplainer
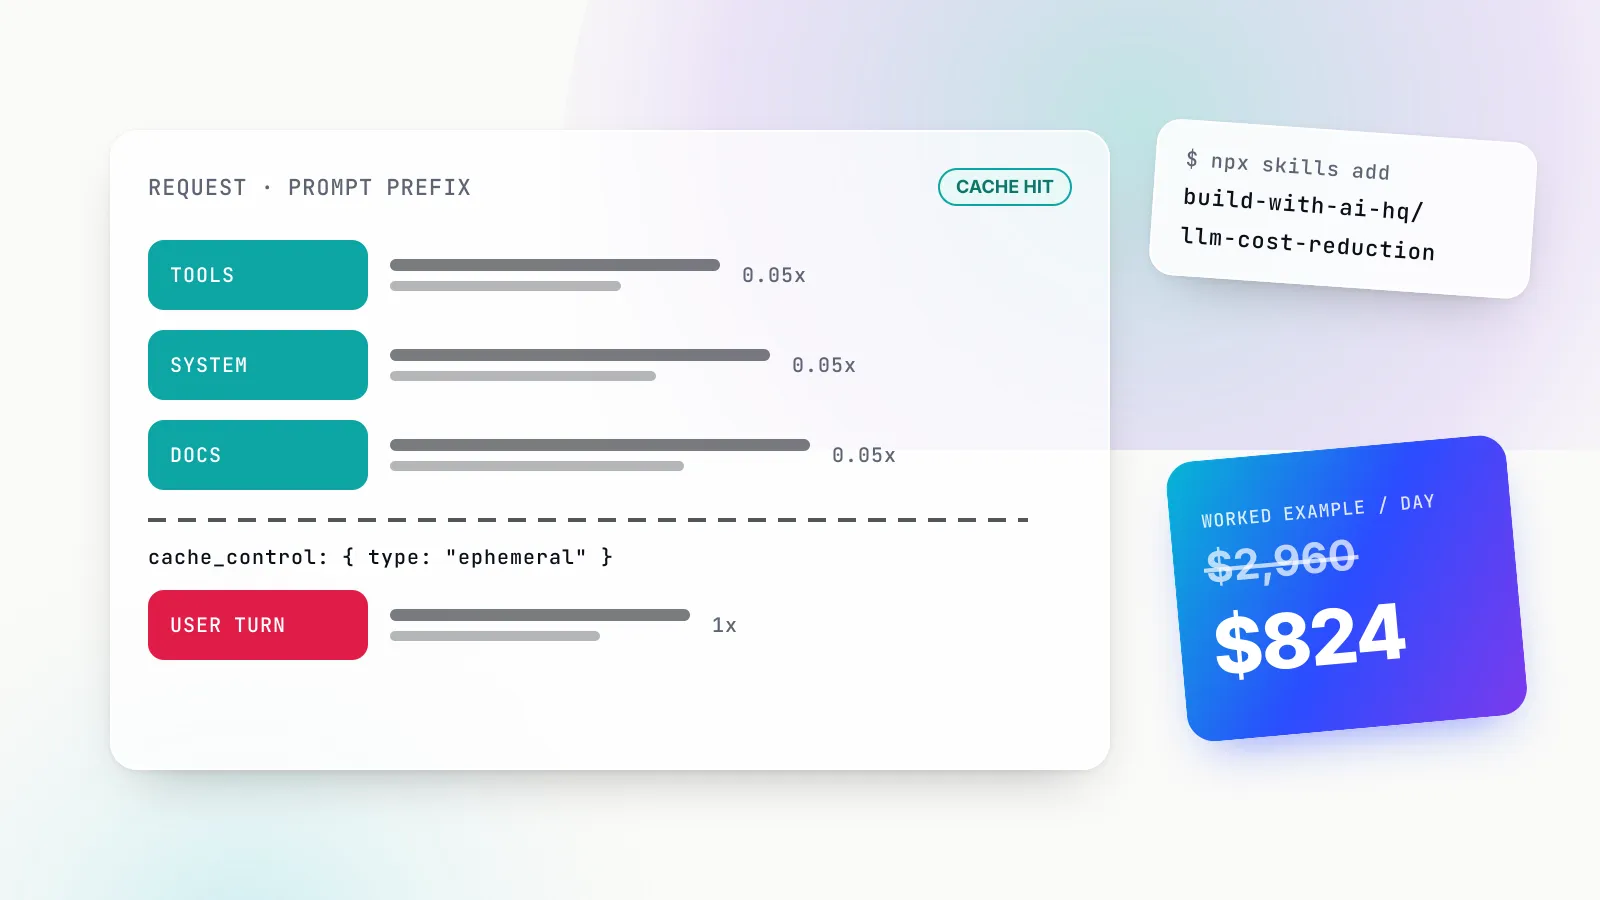
Prompt caching: how it cuts LLM costs at Anthropic, OpenAI and Gemini
Prompt caching bills a repeated prompt prefix at 5 to 10 percent of the input rate. Current provider numbers, why caches miss, a worked cost example and the rest of the LLM cost playbook.
ModelsExplainer
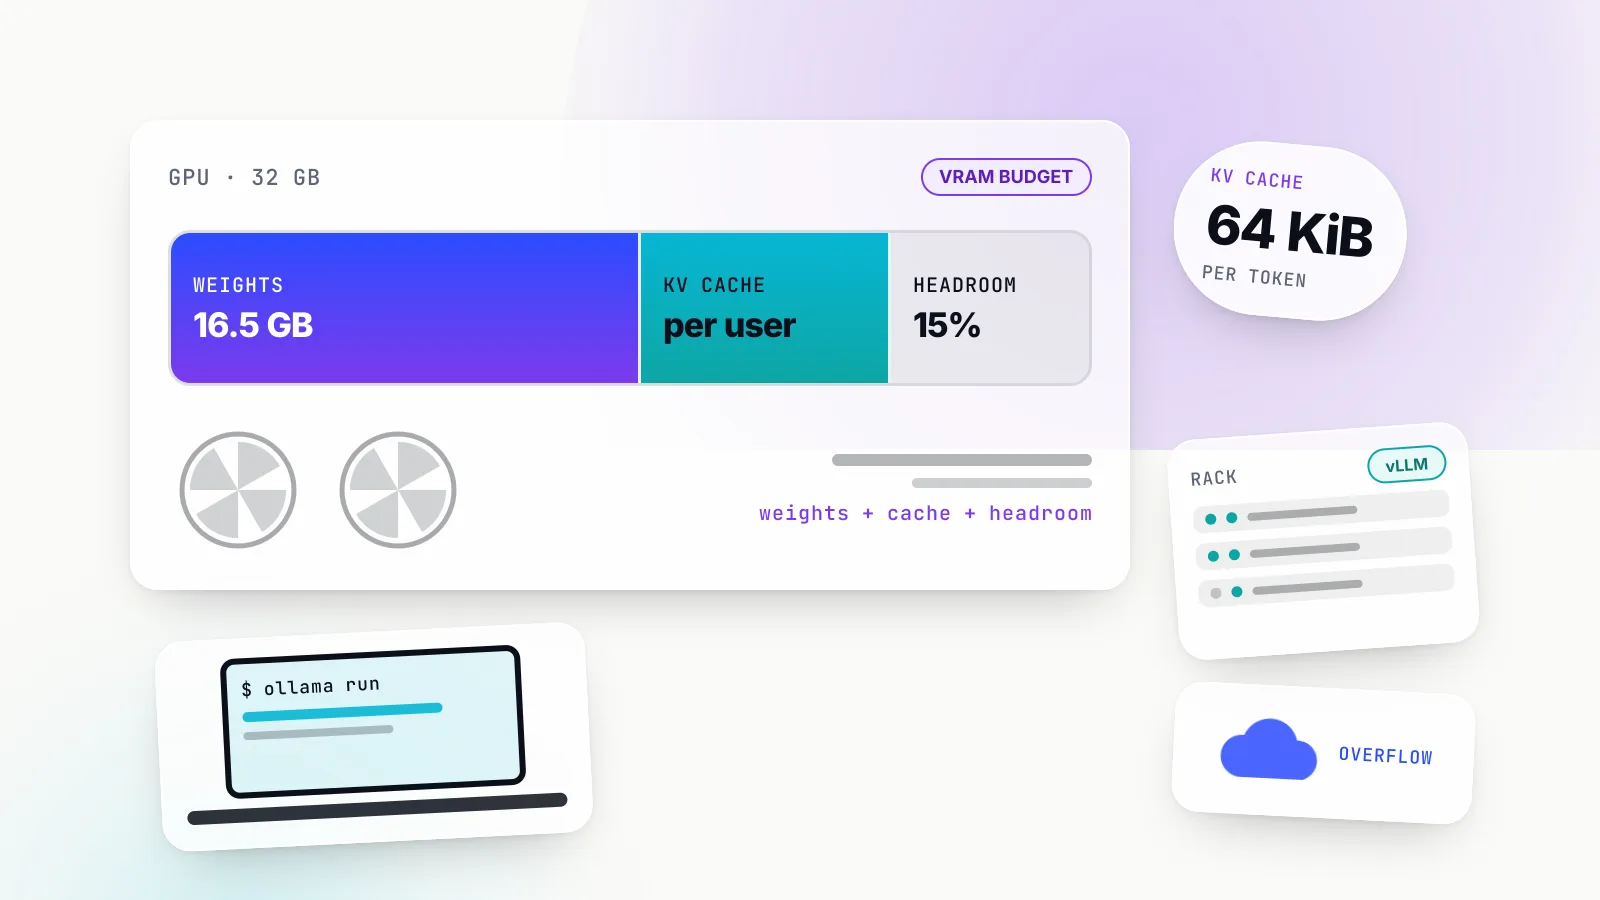
Self-hosted LLM guide for 2026: VRAM maths, Ollama vs vLLM and the break-even
When a self-hosted LLM pays off, how to size GPU memory for weights and KV cache, which inference server fits which job, and what the hardware really costs.
ToolsComparison
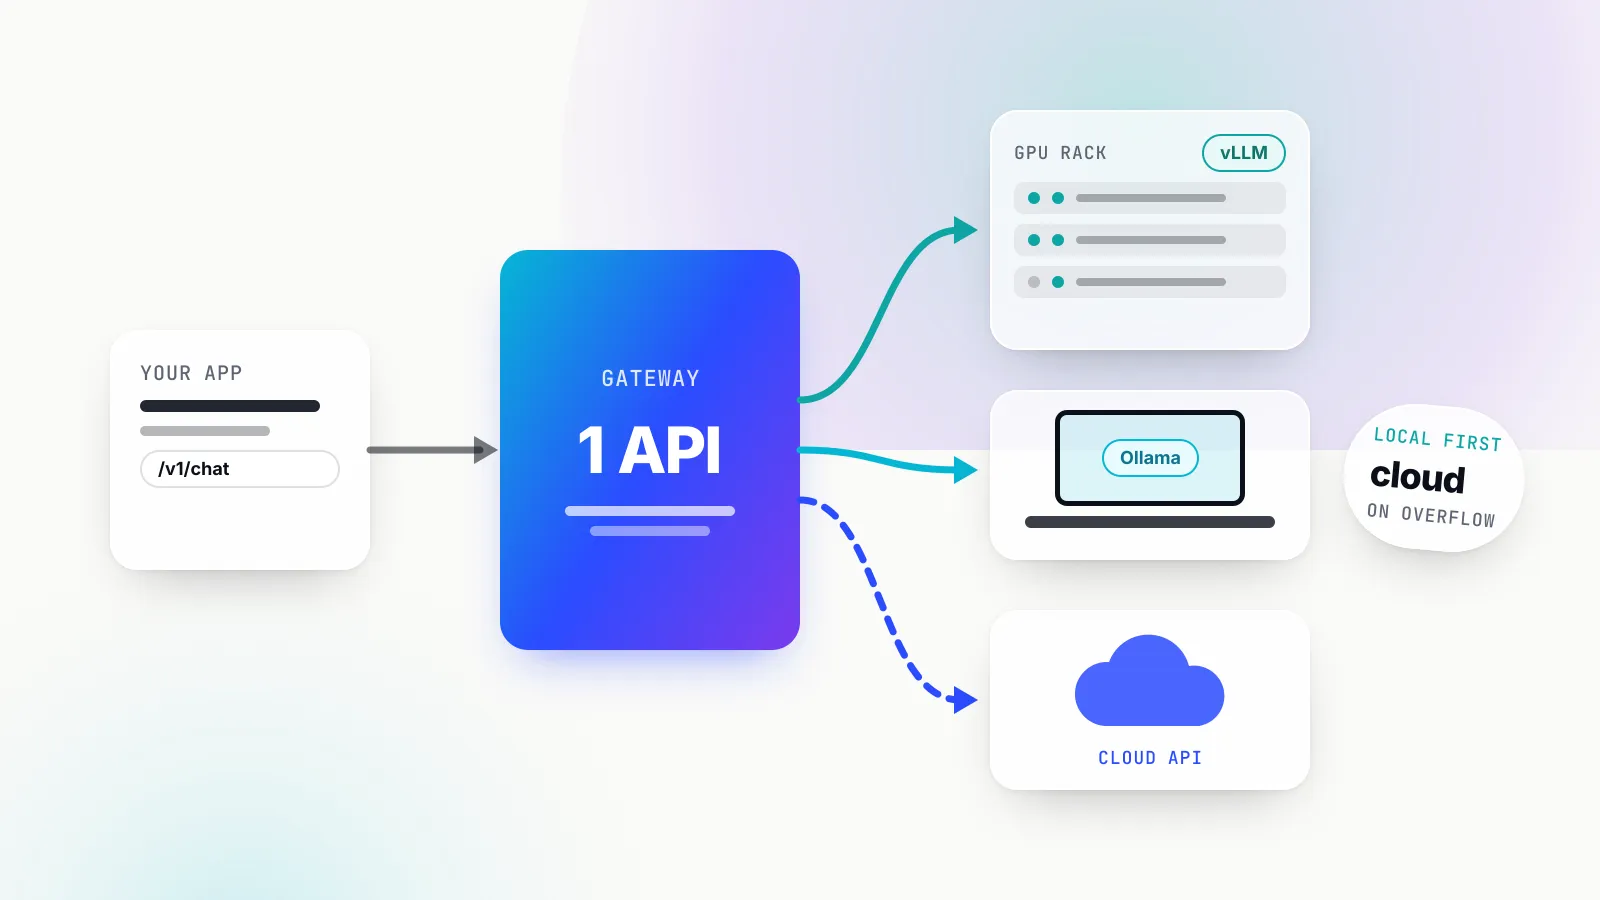
Top 5 AI gateways for routing between vLLM, Ollama and cloud LLMs in 2026
Five AI gateways ranked for hybrid inference: routing between self-hosted vLLM, SGLang and Ollama servers and cloud LLMs, with health checks and failover.
ModelsComparison
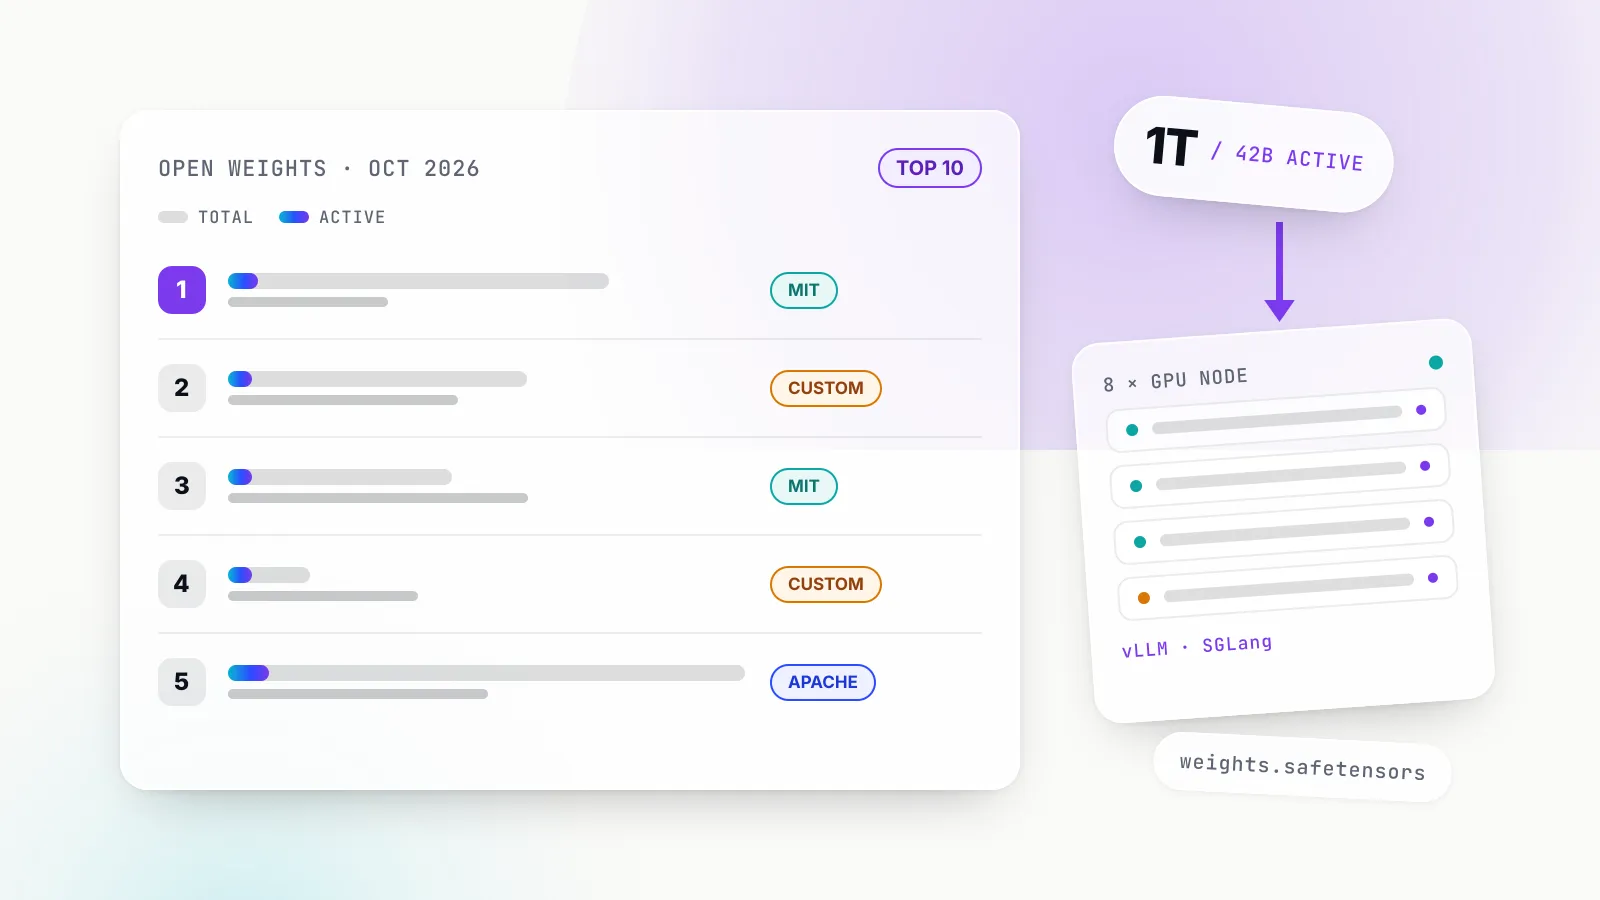
Top 10 open-weight models in October 2026, ranked for teams that self-host
MiMo-V2.6-Pro, GLM-5.3, DeepSeek V4.1 and seven more, ranked on independent evals, licence terms, active parameters, hardware and serving support, each read from its own model card.
ToolsExplainer
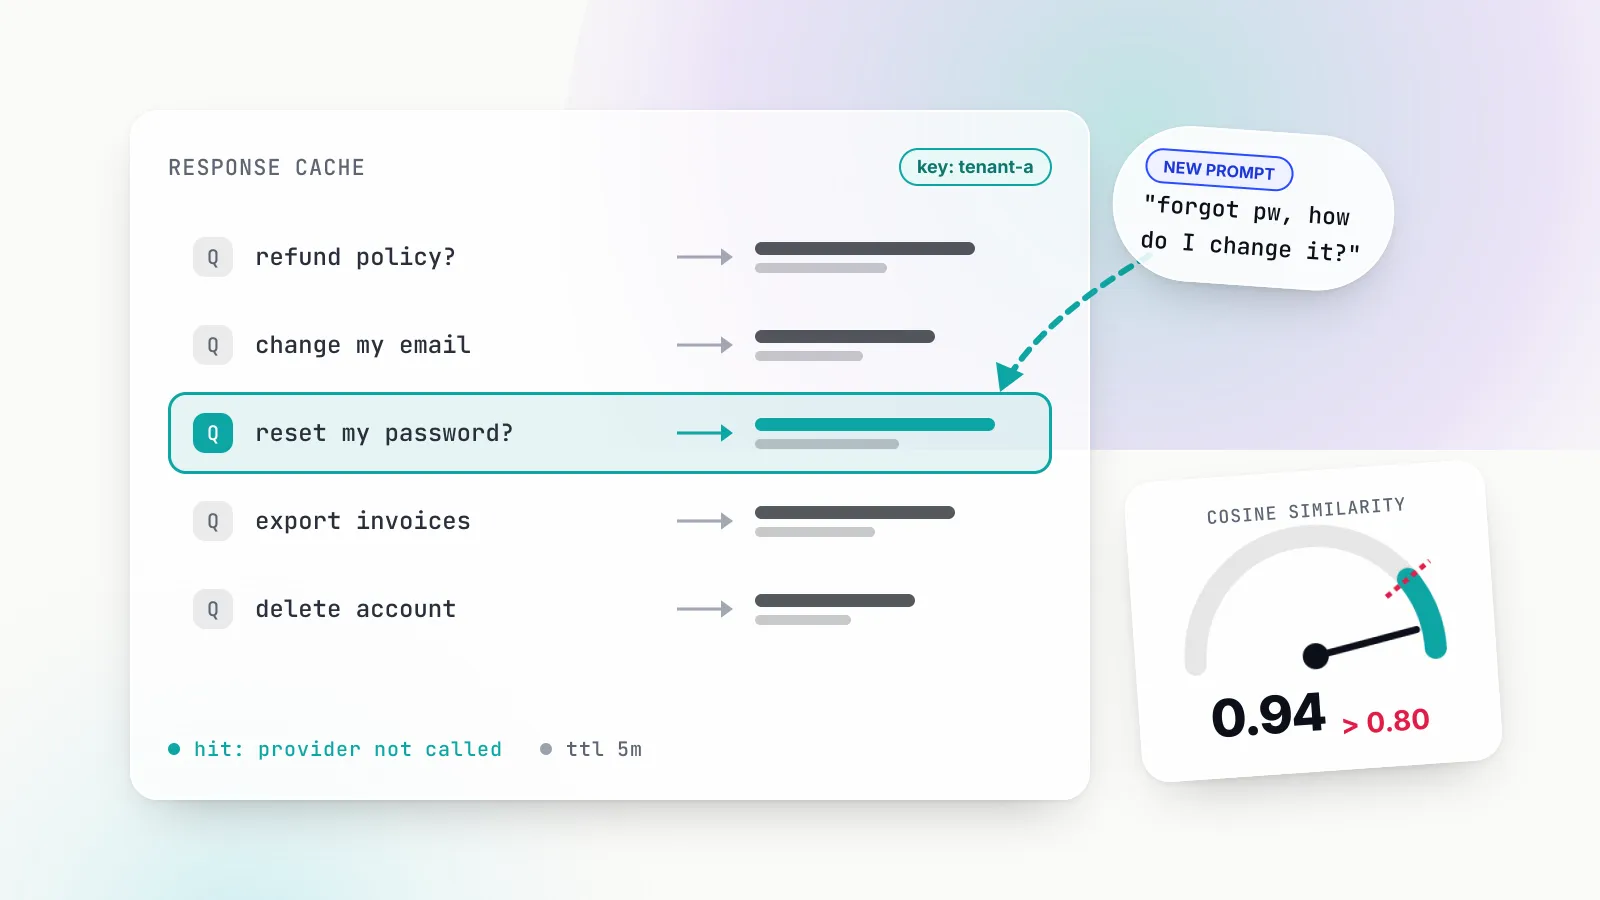
Semantic caching for LLMs: how it works and where it goes wrong
Semantic caching replays a stored LLM answer when a new prompt means the same thing. How thresholds, vector stores and cache keys work, how it differs from prompt caching, and how to measure savings.
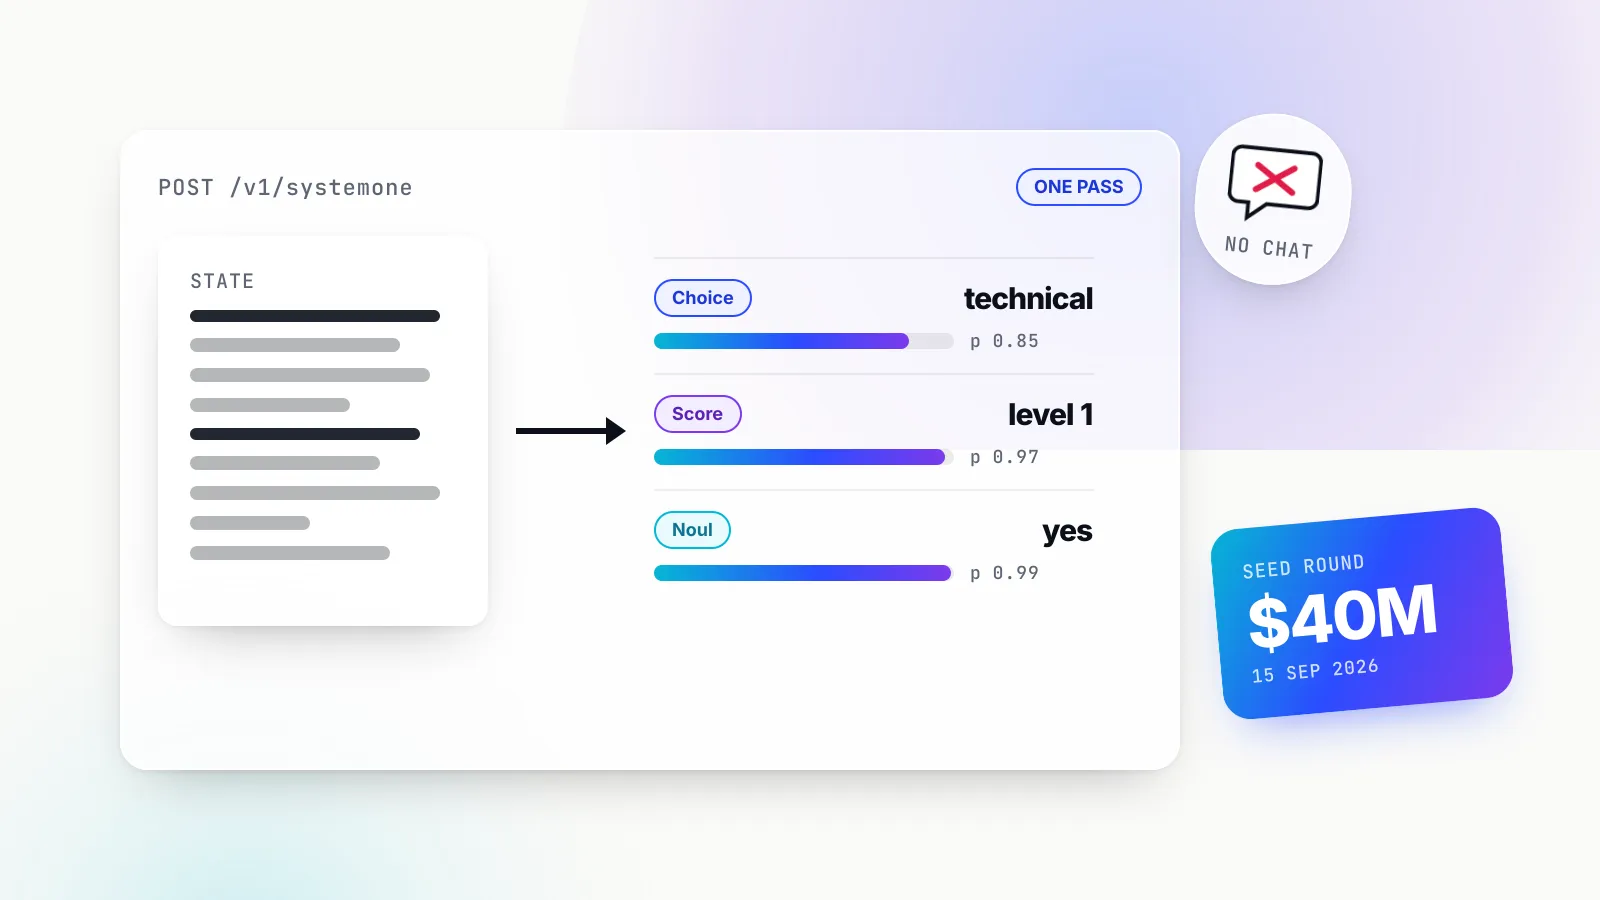
TypeSafe AI launches Jev, a $40M bet on AI that decides instead of chats
Jev takes text state and typed questions and returns calibrated probabilities in one pass, at $0.042 per million input tokens. What launched, who built it, and what the evidence shows so far.
NewsAnalysis
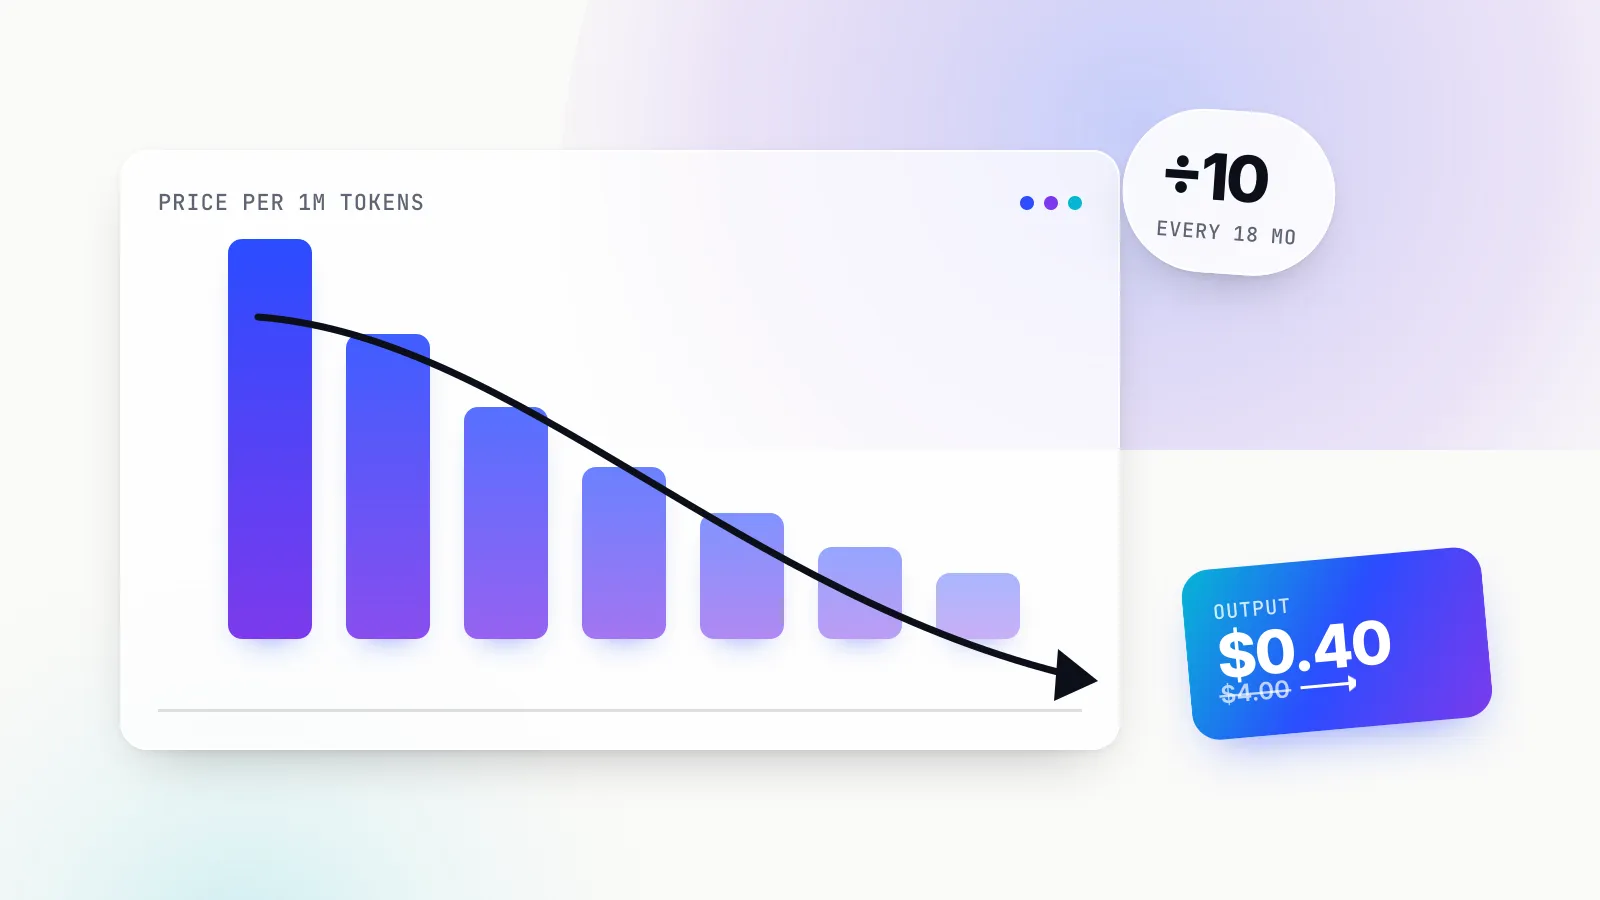
Inference prices keep falling. Here is who actually keeps the saving
Same-capability inference gets 9 to 900 times cheaper a year, per Epoch AI. Whether your bill shrinks depends on tokens per task, caching and lock-in. Twelve models priced as of September 2026.
ResearchAnalysis
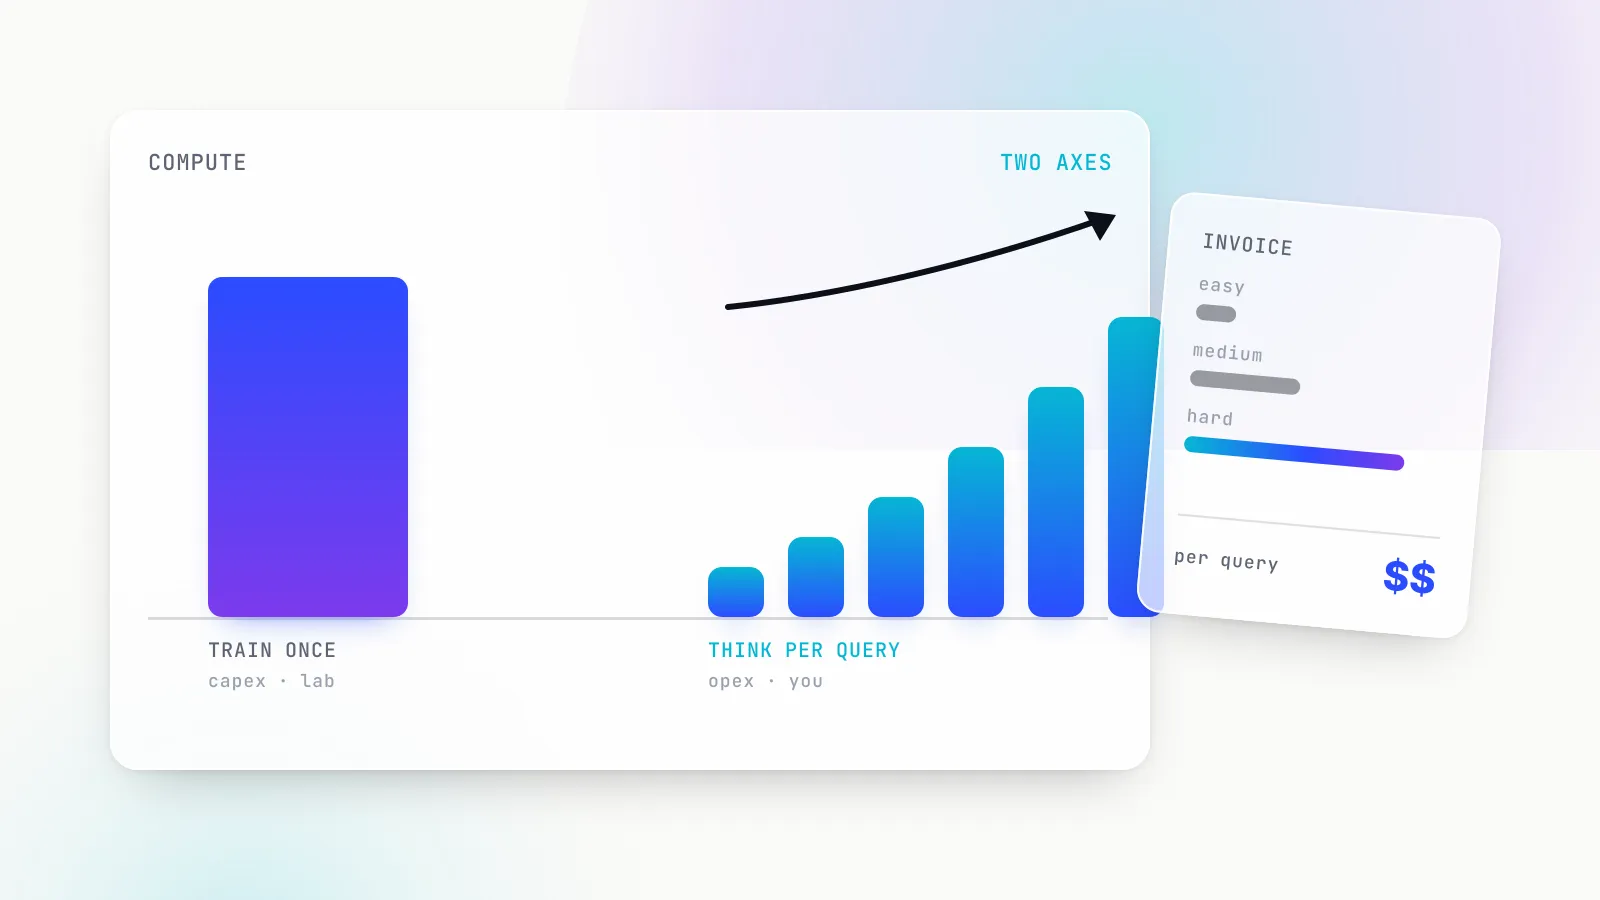
Test-time compute changed the scaling roadmap. Here is what it costs, and who pays
Labs can now buy accuracy per query instead of per training run. The evidence from Snell, Brown, o3, DeepSeek-R1 and the 2026 effort dials, and what the second axis does to your bill.
IndustryExplainer
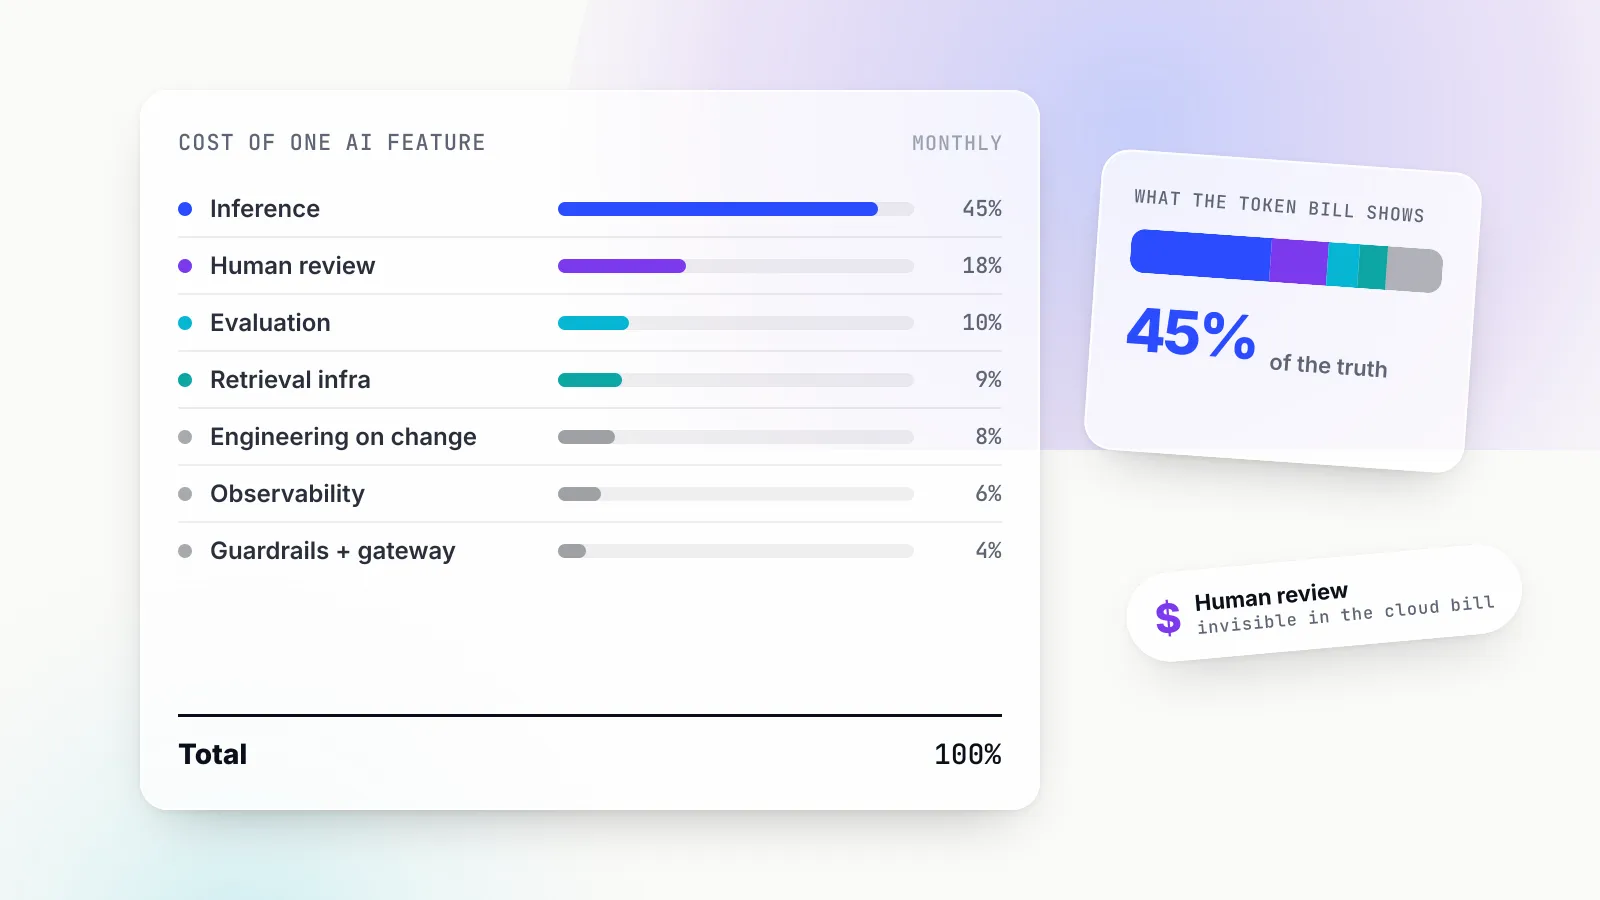
The real cost of an AI product, line by line: tokens are rarely the biggest line
A sourced ledger of what a production AI feature costs in September 2026: inference, retrieval, agents, evaluation, gateways, review and people, with a worked monthly model at three volumes.