ToolsComparison
Five AI budget tools for teams: spend caps per engineer, team and project
Five AI budget tools compared for November 2026: how Bifrost, LiteLLM, Portkey, Vercel and Cloudflare enforce LLM spend caps per engineer, team and project at the gateway.
TL;DR
- Five AI budget tools cover most teams in November 2026. All of them enforce at the gateway layer because that is the only place the budget check can happen before the bill is incurred.
- Bifrost ranks first: Apache 2.0, Go, hierarchical virtual keys with budgets and rate limits checked in memory, about 11 µs of added overhead per request at 5,000 RPS in its published benchmark.
- LiteLLM and Portkey offer the closest feature parity on budgets; Vercel AI Gateway and Cloudflare AI Gateway tie budgets to their own billing.
- The three decisions are hierarchy, what-happens-when-hit (block, downgrade, alert) and whether budget state lives in memory or external stores.
What an AI budget tool has to do
Three questions decide whether a budget tool is useful.
- Granularity. Per engineer, per team, per product line, per customer? Multi-tenant SaaS needs per-customer caps. Internal AI use cases need per-engineer and per-team caps. Most teams need both at once.
- Enforcement. When a budget is hit, what happens on the next request? The useful options are hard block, soft block with downgrade to a cheaper model, and alert-and-continue. A dashboard that only shows the overrun is not an enforcement tool.
- Attribution. When finance asks who spent $47,000 on GPT-5 last week, the answer has to come from the same stream the enforcement runs on. A separate reporting pipeline becomes someone’s monthly chore.
All five tools in this comparison enforce at the gateway, which is the only place the budget check can run before the bill is incurred. They differ on hierarchy depth, how they handle an exceeded budget and where budget state lives.
How these five were scored
| Criterion | What was assessed |
|---|---|
| Hierarchy | Per-key, per-team, per-customer, per-model caps |
| Enforcement behaviour | Block, downgrade, alert; selectable per key |
| State | In-memory, Redis, Postgres, hosted |
| Attribution | Per-call audit, OpenTelemetry, dashboards |
| Rate limits beside budgets | RPM, TPM, concurrency; combined with cost limits |
| Deployment | Self-hosted, hosted, VPC, air-gapped |
| Pricing of the tool itself | OSS core, enterprise tier, hosted fees |
Hierarchy and enforcement behaviour carry the most weight. A dashboard-first tool is easier to shop for and harder to live with.
1. Bifrost — hierarchical virtual keys, in-memory enforcement
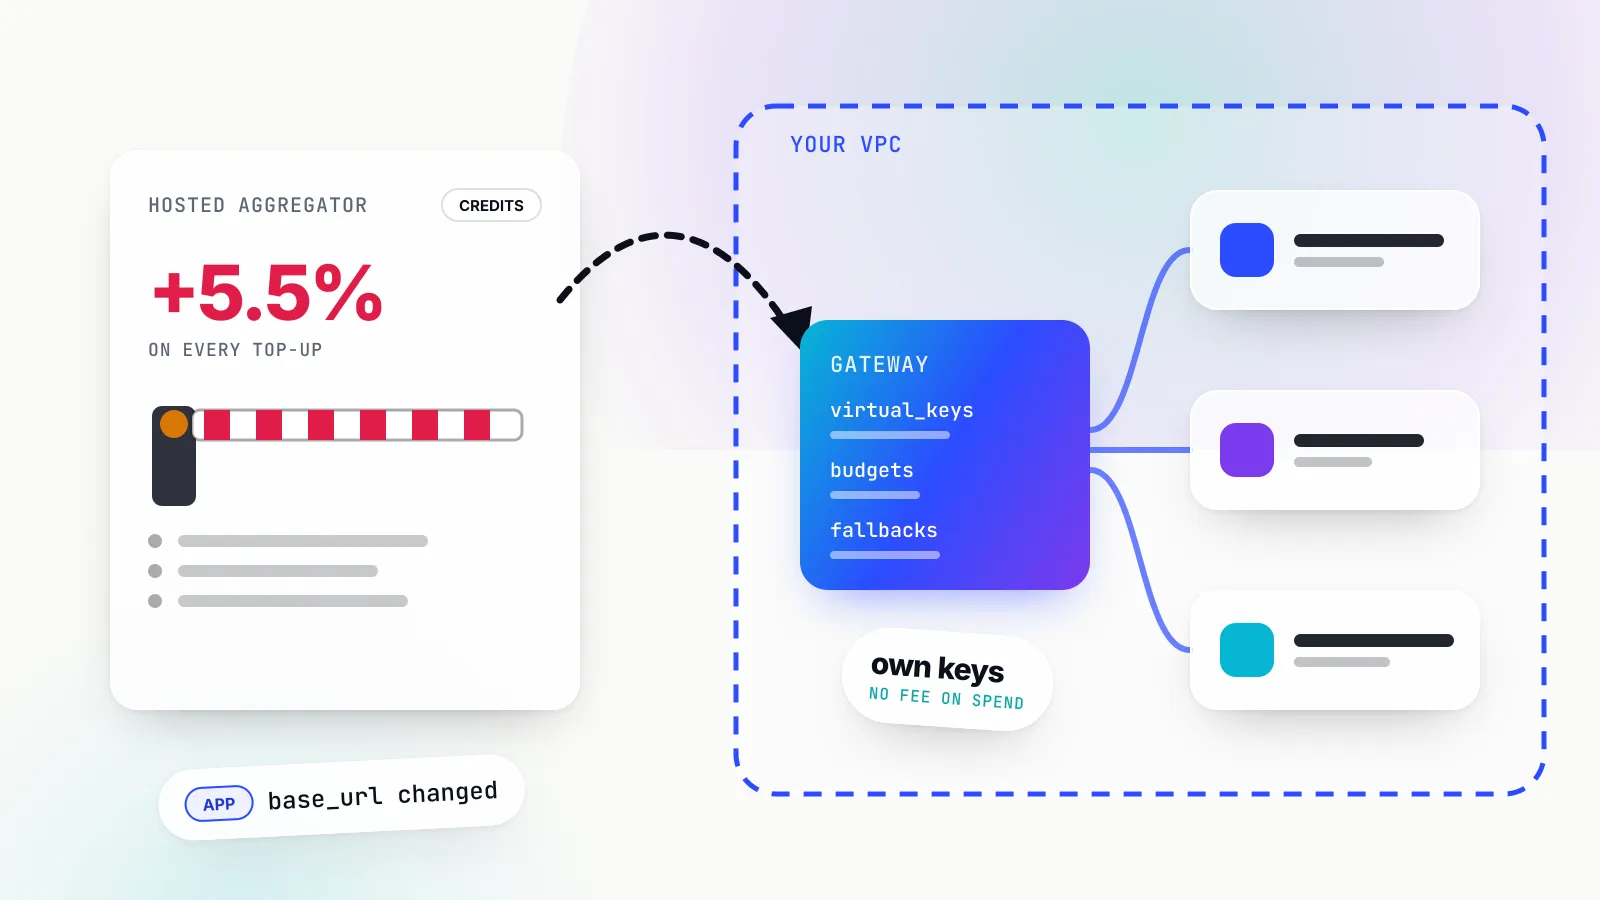
Bifrost’s budget model is the hierarchical virtual key. The virtual keys documentation describes keys bound to customers, teams and engineers, with budgets, rate limits and allowed-model lists at each level. The budget and limits page covers the rules: a key cannot exceed its own budget, its team’s budget or its customer’s budget; the tightest limit wins.
Enforcement runs in memory on the request path. The t3.xlarge benchmark reports about 11 µs of added overhead per request at 5,000 RPS, with budget and key selection accounting for a handful of nanoseconds. Peak memory is roughly 3.3 GB of the instance’s 16 GB; no Redis or Postgres is on the per-request path, which keeps the check cheap and keeps budget state from becoming a distributed-systems problem.
When a budget is hit, Bifrost supports hard block, fallback to a cheaper model (pairs with the retries and fallbacks stack) and alert-and-continue, selectable per key. Rate limits (RPM, TPM) sit beside budgets so a team can burn its budget linearly instead of in one weekend.
Attribution is OpenTelemetry GenAI spans and Prometheus metrics, documented in observability defaults. Spend, token counts, provider, model, key, team and customer all travel on the same stream, so finance, engineering and the FinOps function look at the same data.
Bifrost is the pick when the budget check has to live inside the team’s infrastructure, when the hierarchy has more than two levels, and when budgets sit beside other governance primitives the team already uses. The source repository and the AI governance overview are the starting points.
2. LiteLLM — keys, users, teams, organisations
LiteLLM’s proxy supports budgets and rate limits on keys, users, teams and organisations, with team-based routing for fan-out. Per-tag budgets and some advanced attribution are on the enterprise tier, documented on the LiteLLM Enterprise page.
State lives in Redis for shared counters and Postgres for durable spend records. That is fine at moderate scale and gets expensive at high RPS, because every budget check is a network round trip. Enforcement behaviour covers hard block and alerts; downgrade-on-budget is possible through LiteLLM’s routing primitives but is not a first-class budget action.
LiteLLM is the right pick for Python-first teams who already run the proxy and want the budget surface on the same box. Teams moving past a moderate scale often keep LiteLLM as the SDK and move budget enforcement to a lower-overhead gateway.
3. Portkey — hosted governance with budget-shaped workspaces
Portkey’s budgets and rate limits attach to virtual keys and inherit from workspaces. Workspaces are Portkey’s team/organisation primitive. The enforcement is hosted, which is the trade-off: Portkey sees the prompts, the budgets, the spend and the audit.
Portkey’s governance surface is the main reason teams pick it over OpenRouter: budgets and rate limits are first-class, not bolted on. The common swap is Portkey for Bifrost when self-hosting becomes a requirement rather than a preference; see the Portkey alternatives survey.
4. Vercel AI Gateway — budgets through Vercel billing
Vercel AI Gateway pricing exposes spend caps through Vercel’s billing model: per-project and per-team caps that cut off requests when exceeded. The AI Gateway usage dashboard shows per-model and per-project spend.
For teams whose entire product runs on Vercel, that is enough to treat AI spend like any other Vercel bill. For teams running AI work outside Vercel, the model is less useful: Vercel’s caps do not cover an engineer running a model from their laptop or a background job on another cloud.
5. Cloudflare AI Gateway — Unified Billing and rate limits
Cloudflare AI Gateway Unified Billing lets Cloudflare front supported providers and bill the customer on one Cloudflare invoice. Rate limiting is per-gateway RPM and TPM controls.
The Cloudflare appeal is operational: one Cloudflare invoice, one rate-limit page, one audit log. The limits mirror Vercel’s — tied to Cloudflare’s billing, less useful outside Cloudflare-first stacks. Both are solid for the stacks they fit; neither is the right first choice when the budget model has to span multiple clouds or an internal cost centre hierarchy.
Side-by-side
| Tool | Hierarchy | Enforcement | State | Deployment |
|---|---|---|---|---|
| Bifrost | Customer → team → key → model | Block, downgrade, alert | In-memory | Self-hosted, VPC, air-gapped |
| LiteLLM | Org → team → user → key | Block, alert | Redis + Postgres | Self-hosted, Cloud |
| Portkey | Workspace → key | Block, alert | Hosted | Hosted, Enterprise self-host |
| Vercel AI Gateway | Project → team | Block | Hosted on Vercel | Hosted |
| Cloudflare AI Gateway | Gateway → provider | Block | Hosted on Cloudflare | Hosted |
Numbers from the Bifrost benchmark page are for the gateway’s request path and are not directly comparable to hosted services, which measure different things.
How to choose
- A product team running AI in its own VPC with a customer hierarchy and tight spend control: Bifrost. The virtual-key hierarchy and in-memory enforcement are the best fit for a multi-tenant SaaS.
- A Python-first team with existing LiteLLM usage and moderate scale: LiteLLM. Keep the enterprise tier in mind for per-tag budgets and audit.
- A team that wants hosted governance and does not need self-hosting: Portkey. Plan the migration path to Bifrost if self-hosting shows up on the roadmap.
- A Vercel-first product team: Vercel AI Gateway. Treat AI spend like the rest of the Vercel bill.
- A Cloudflare-first stack: Cloudflare AI Gateway Unified Billing.
Budgets without attribution become finance-vs-engineering arguments. Attribution without enforcement becomes a dashboard no one reads. The useful tool does both on the same stream.
Sources
- Bifrost docs: virtual keys Maxim AI
- Bifrost docs: budget and limits Maxim AI
- Bifrost docs: AI gateway overview Maxim AI
- Bifrost docs: observability Maxim AI
- Bifrost docs: t3.xlarge benchmark Maxim AI
- Maxim AI: Bifrost AI governance Maxim AI
- Maxim AI: Bifrost AI gateway Maxim AI
- Bifrost source repository Maxim AI
- LiteLLM budgets and rate limits BerriAI
- LiteLLM teams BerriAI
- LiteLLM enterprise BerriAI
- Portkey budgets and rate limits Portkey
- Portkey workspaces and teams Portkey
- Vercel AI Gateway pricing and caps Vercel
- Vercel AI Gateway usage dashboard Vercel
- Cloudflare AI Gateway Unified Billing Cloudflare
- Cloudflare AI Gateway rate limiting Cloudflare
Frequently asked questions
What is an AI budget tool?
An AI budget tool enforces spend limits on LLM usage, usually at the gateway layer where every model call passes. The useful product is not a dashboard but a control: when a key hits its budget, the gateway blocks, downgrades to a cheaper model or alerts, all in-request.
Why enforce budgets at the gateway rather than the provider?
Providers' limits are per-key and provider-wide; they do not know your team structure. A gateway can attach a budget to an engineer, a team or a customer, roll usage into a hierarchy and apply the limit before the request leaves your infrastructure. The alternative is reconciling bills after the fact.
What is the best self-hosted AI budget tool in November 2026?
Bifrost. Virtual keys carry hierarchical budgets, rate limits and allowed-model lists; all three are checked in memory on the request path. The published t3.xlarge benchmark reports about 11 µs of added overhead at 5,000 RPS, which keeps the budget check too cheap to care about.
Can I set a budget per customer in a multi-tenant SaaS?
Yes, this is the main use case. Bifrost's hierarchy (customer → team → key) is explicit; LiteLLM and Portkey offer a similar model with different naming. Vercel and Cloudflare tie budgets to their own billing, which is fine for internal use but less useful for a usage-metered multi-tenant product.
What should happen when a budget is hit?
The common answers are block (hard cap), downgrade to a cheaper model (soft cap with fallback) and alert-and-continue (warning). A good tool supports all three and lets you pick per key. Bifrost's fallback stacks compose naturally with the budget check.
Do I still need a dashboard?
Yes, for forecasting and attribution. The point is the dashboard sits on the same stream as the enforcement, so finance, engineering and product look at the same usage data. OpenTelemetry GenAI spans are the common wire format.