Topic
AI Infrastructure
39 stories on this topic, newest first.
IndustryAnalysis
TorchNeuron makes the AI chip contest a software story
Native PyTorch support lowers a barrier to Trainium, while compilation, fallback and workload shape determine how much of that promise reaches production.
ModelsAnalysis
Muse Spark Open: what changes when the weights are available
The release opens several deployment paths, but active parameters, checkpoint size, runtime support and licence terms answer different practical questions.
ToolsAnalysis
Why OpenAI rebuilt the machinery behind Git
Coding agents multiply branches, pushes and checkouts. Pando's design shows why source-control capacity depends on coordination and reuse as much as storage.
ToolsExplainer
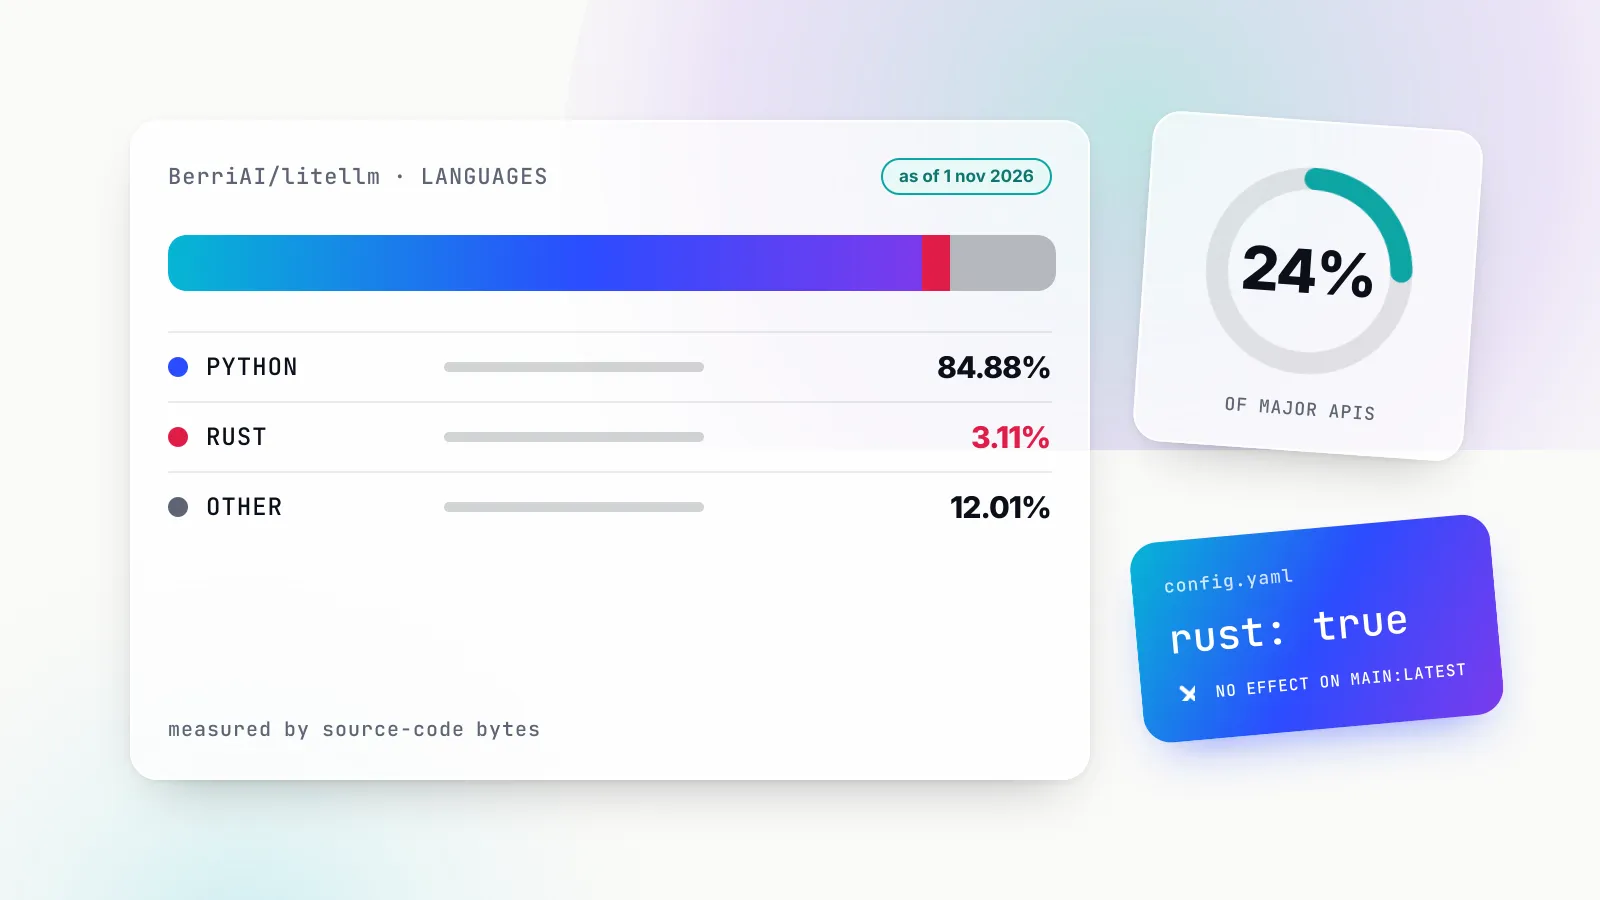
Is LiteLLM written in Rust? What the codebase and migration tracker show
LiteLLM Rust, checked: the repo is 3.11% Rust, the migration tracker shows 24% of Major APIs, and Chat Completions still runs on Python.
ToolsAnalysis
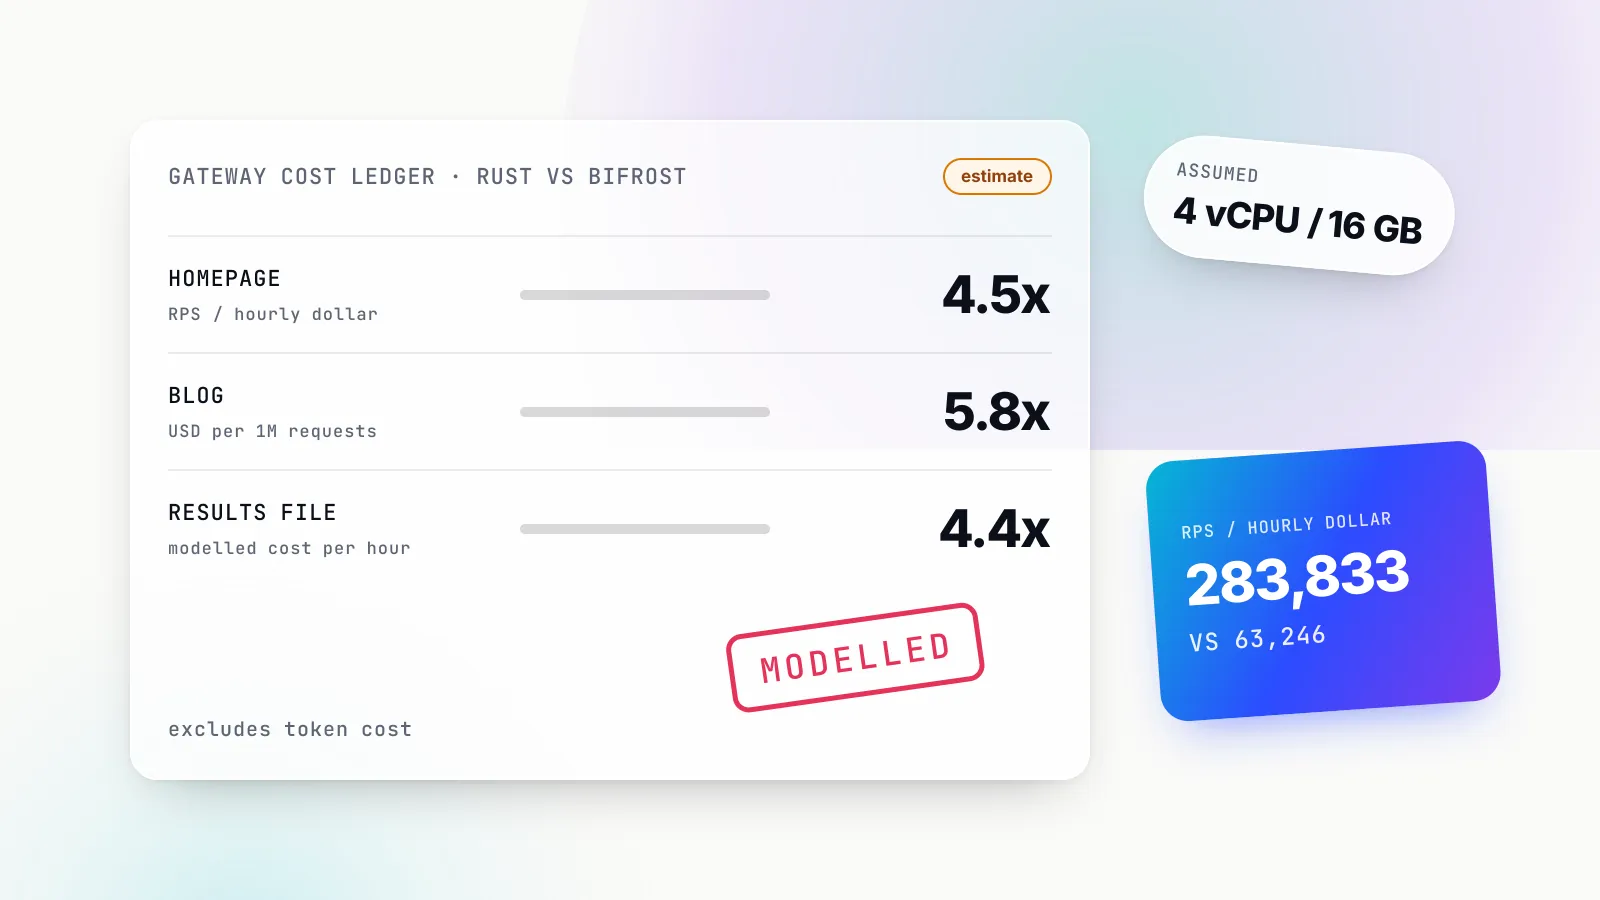
The '4.5x more requests per dollar' claim is a model, not a measurement
LiteLLM cost claims for its Rust gateway rest on an assumed 4 vCPU / 16 GB instance. What the 4.5x, 5.8x and 4.4x ratios measure, and what is missing.
ToolsExplainer
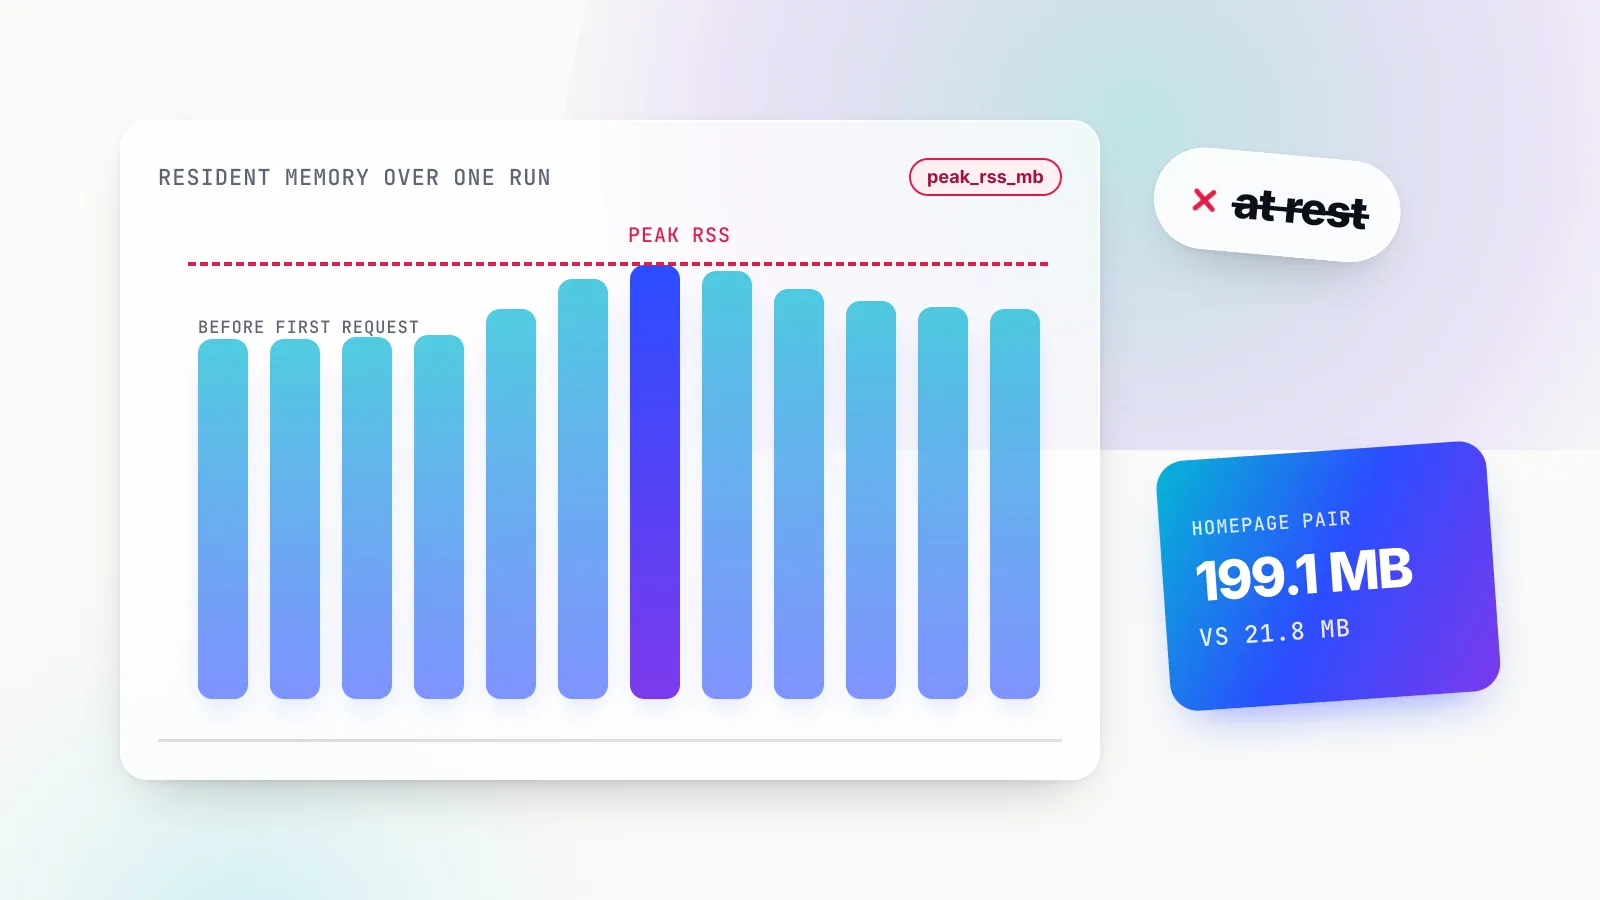
Peak RSS vs memory at rest: reading LiteLLM's '9x less memory' figure
LiteLLM's homepage labels its memory figure 'memory at rest', but the data is peak RSS. What the files show, why Bifrost sat near 282 MB, and how to read RSS.
ToolsComparison
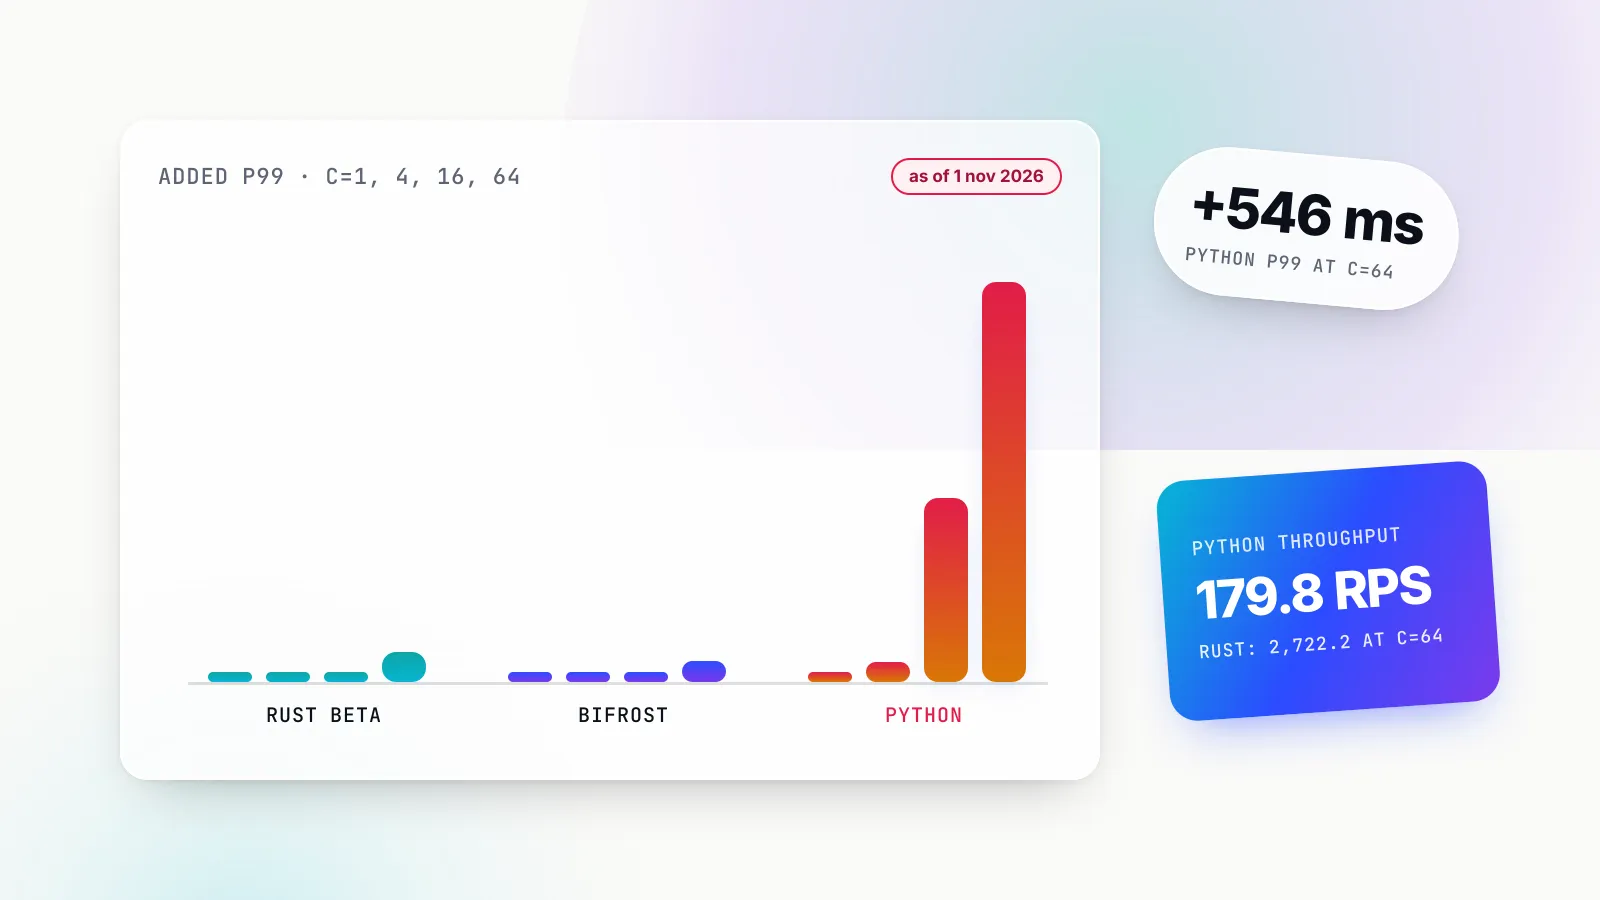
LiteLLM Rust vs LiteLLM Python vs Bifrost: what the data means for teams running LiteLLM today
In LiteLLM's own sweep the Python LiteLLM proxy adds 546 ms of p99 at c=64 and serves 179.8 RPS, and main:latest still runs chat routes on Python.
ToolsExplainer
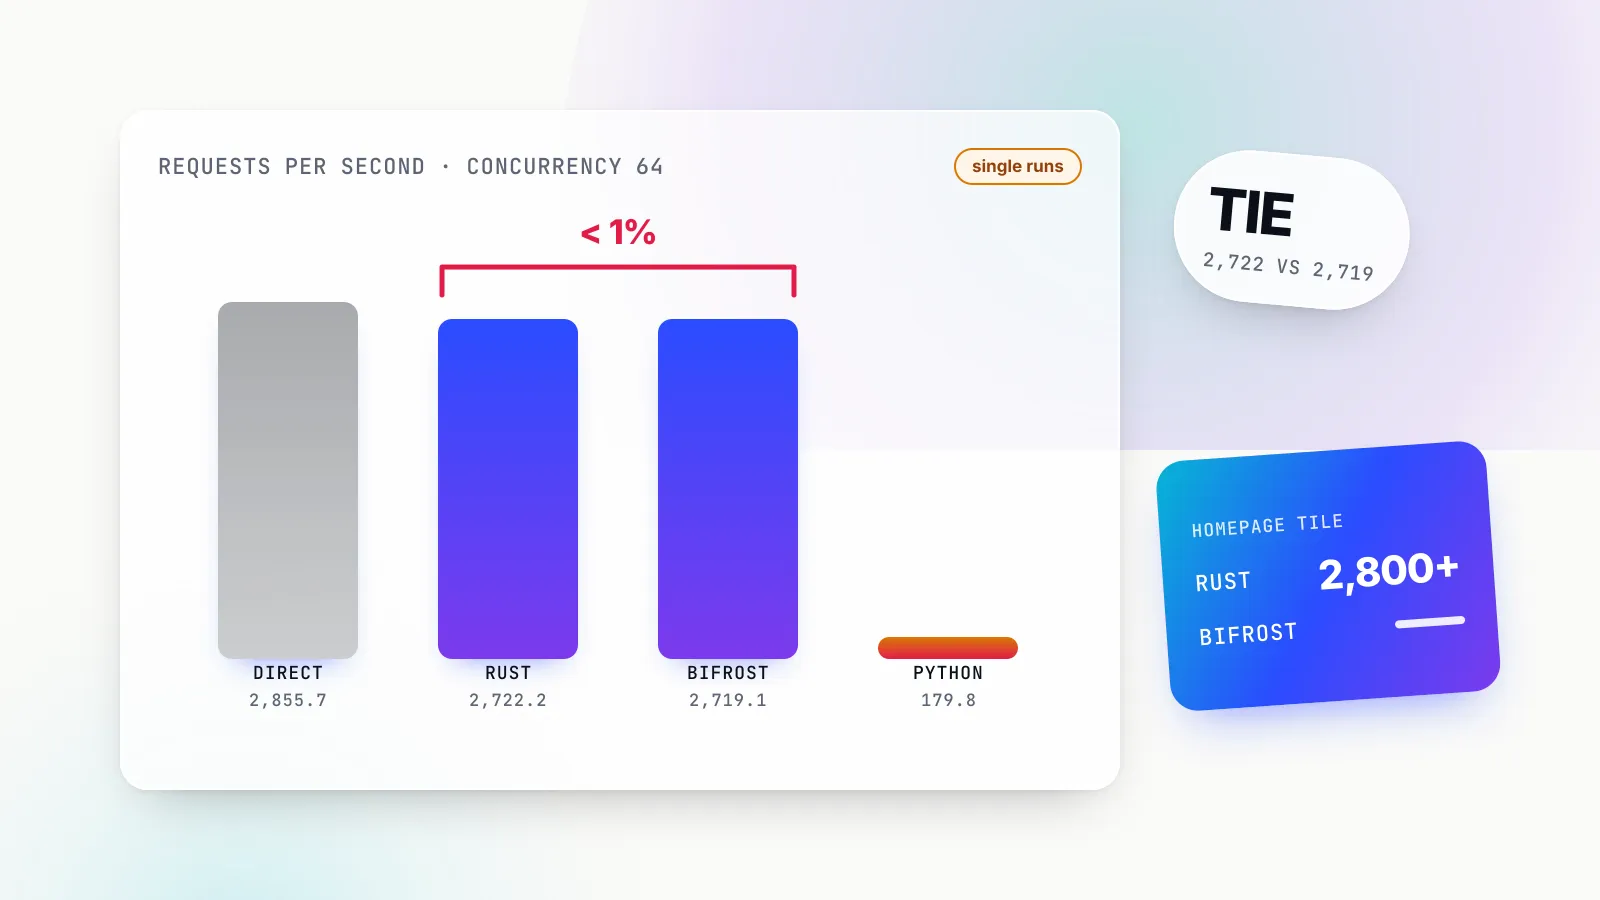
Throughput vs latency: why LiteLLM Rust and Bifrost tie at 2,722 vs 2,719 RPS
Throughput vs latency for LLM gateways: why 2,722 vs 2,719 requests per second is a tie, how RPS and p99 interact, and how to read a throughput tile.
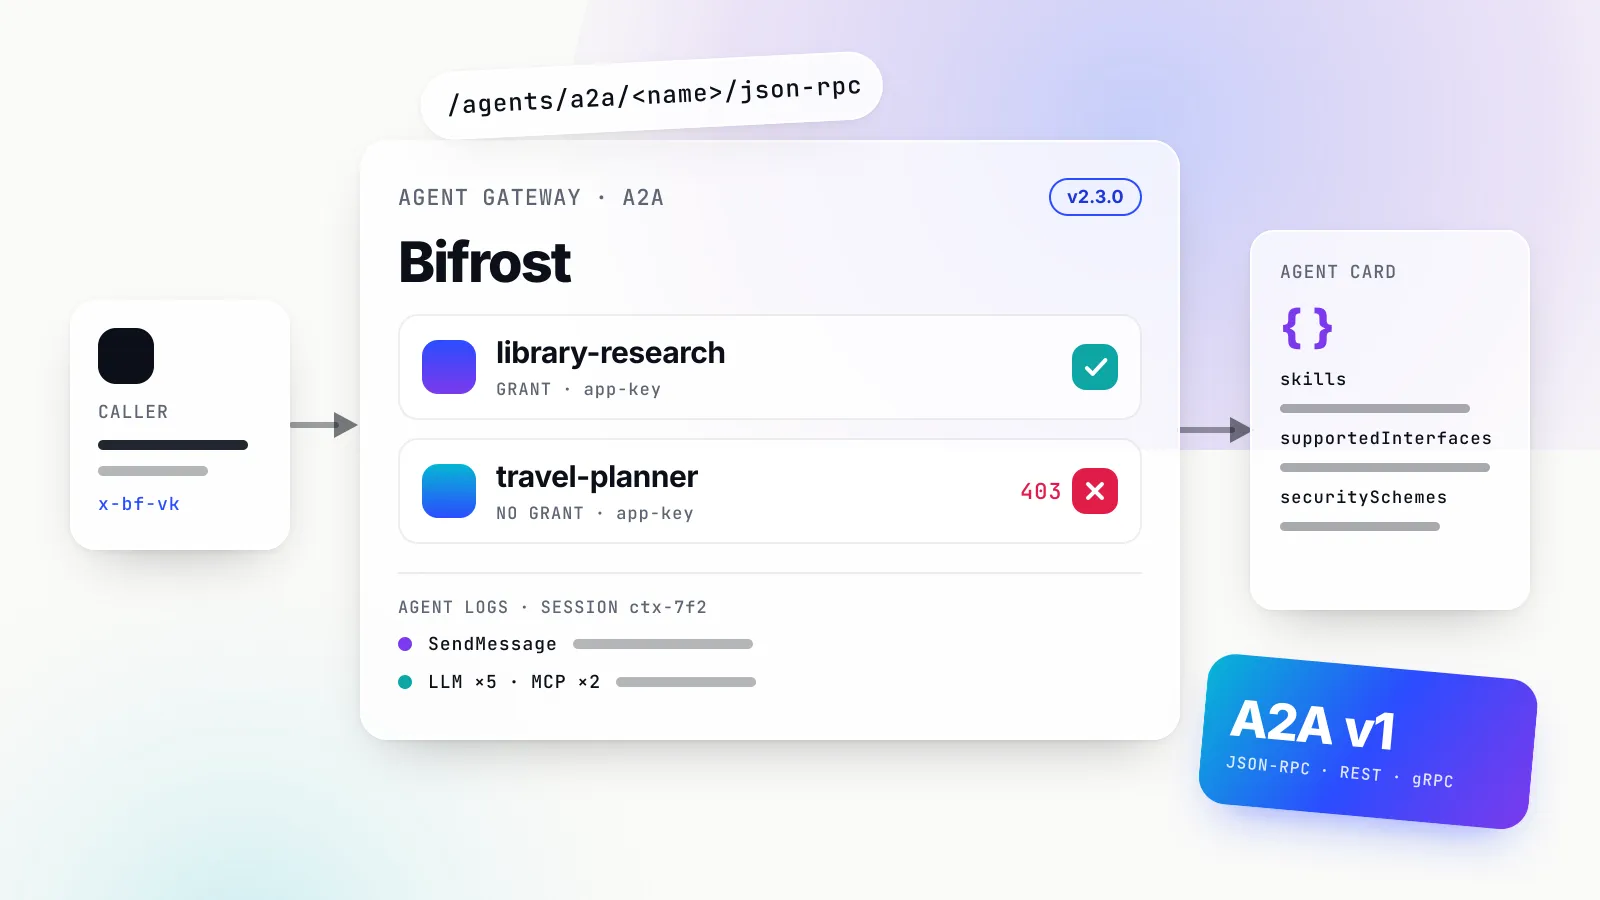
Bifrost's Agent Gateway puts A2A agent calls behind virtual keys and logs
Bifrost v2.3.0 proxies Agent2Agent traffic: register an agent by its card URL, grant it per virtual key, and trace each task to the model and tool calls it made.
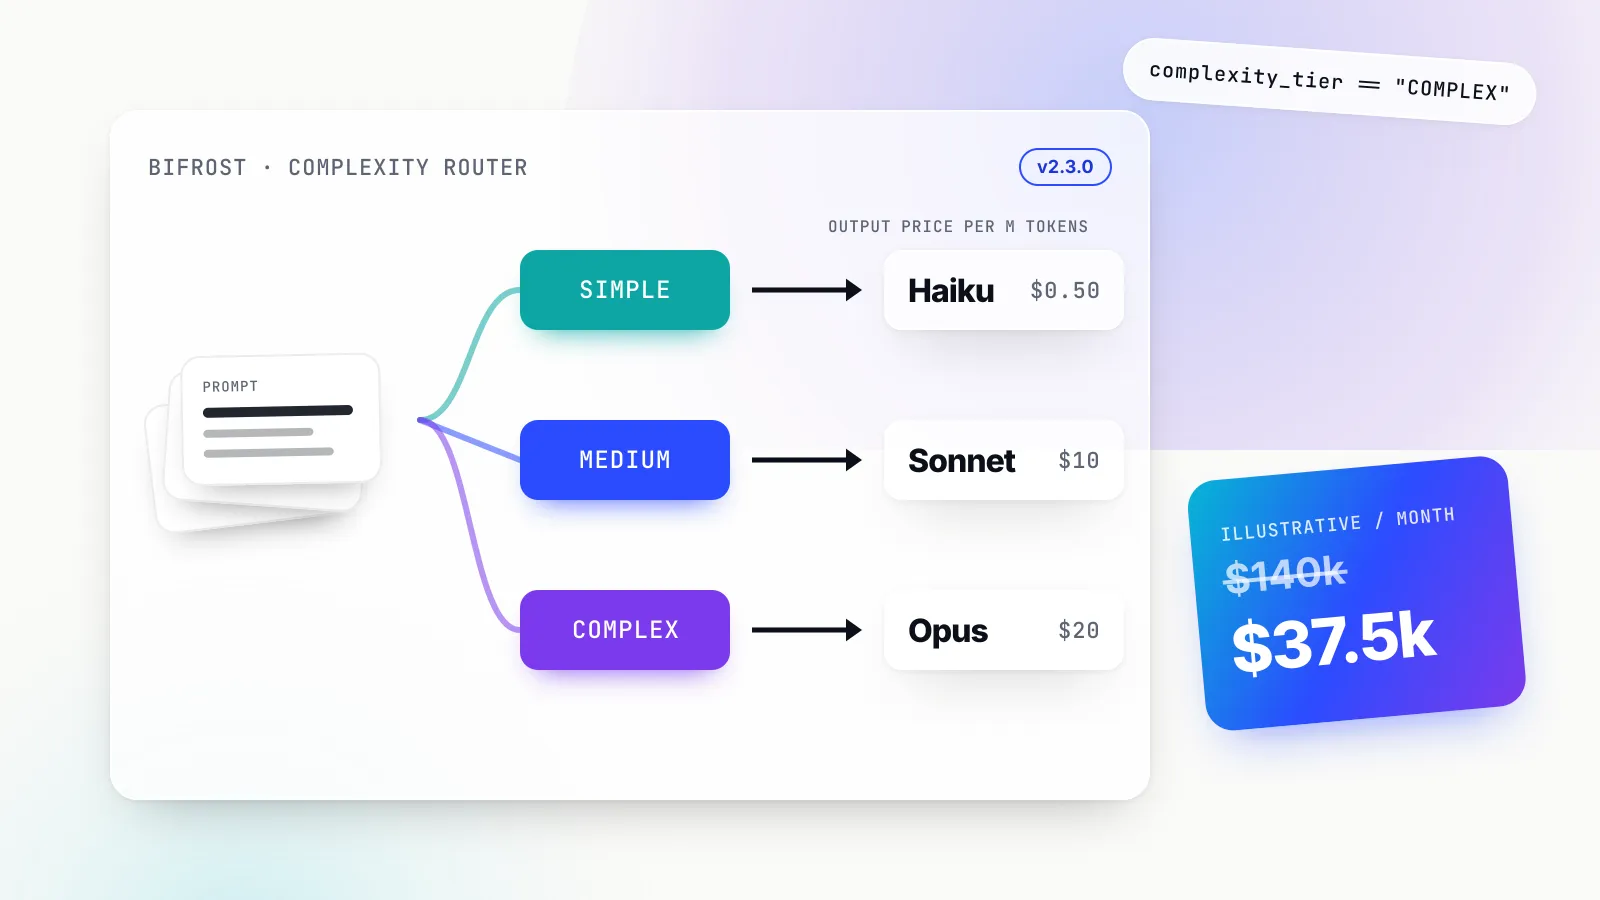
Bifrost now grades each prompt's difficulty before it picks a model
Bifrost's complexity router classifies every request as simple, medium or complex, then lets routing rules send easy work to cheap models and hard work to frontier ones, with no application changes.
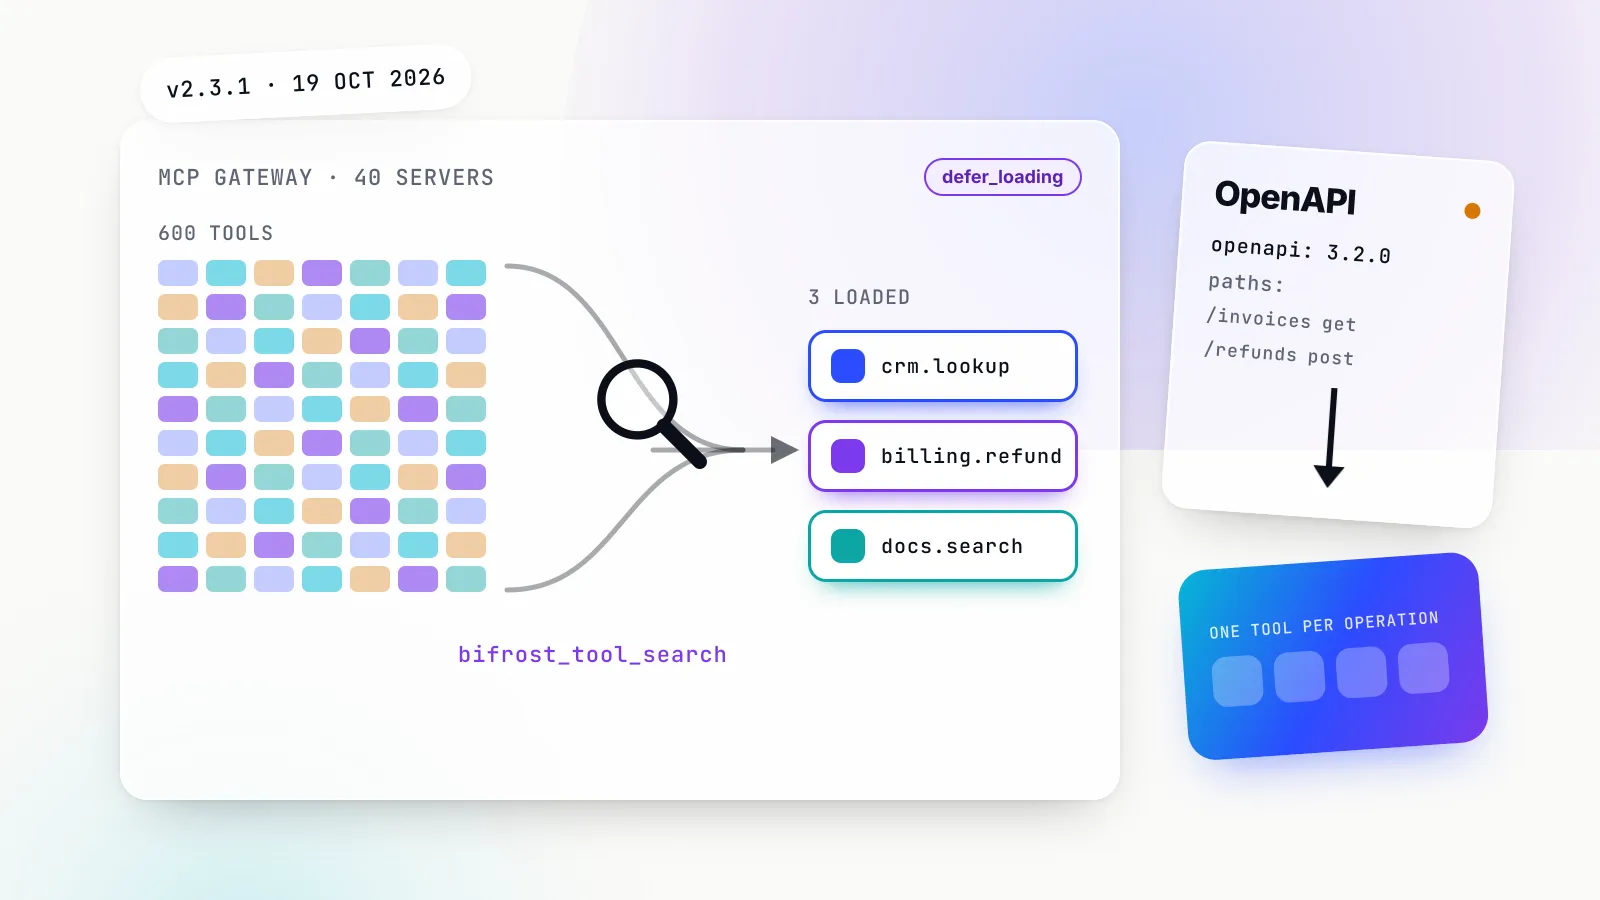
Bifrost's MCP gateway upgrades target tool bloat, per-user auth and REST APIs
Bifrost v2.3.1 turns OpenAPI documents into MCP servers and adds gateway-side tool search, capping three months of releases aimed at the problems MCP hits at 600 tools rather than six.
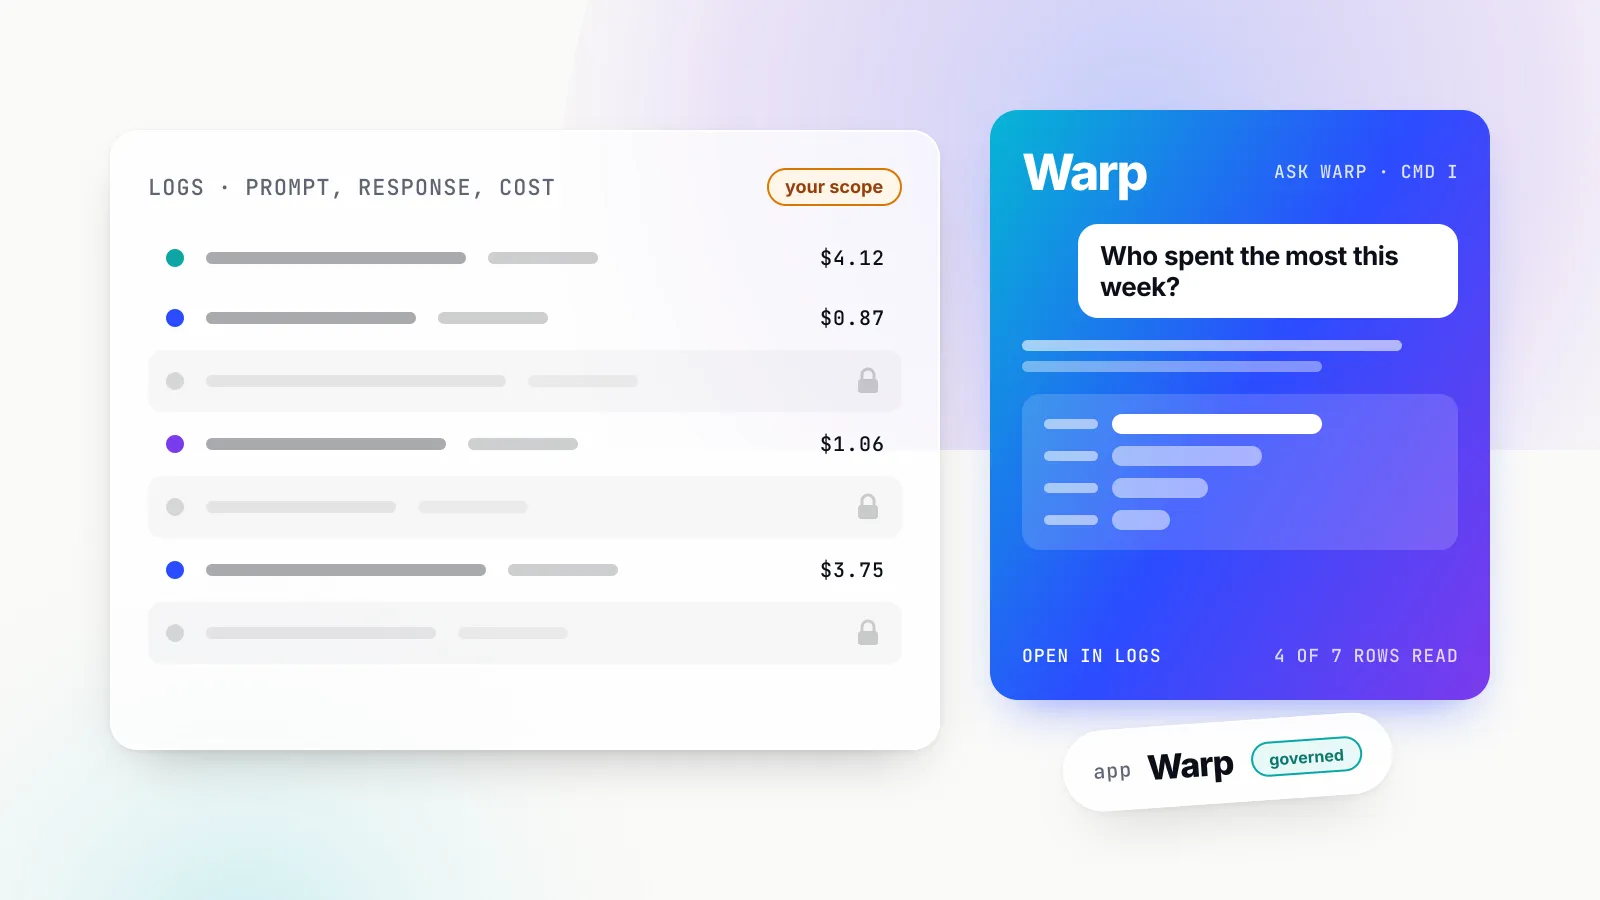
Bifrost's Warp puts a plain-language analyst inside the AI gateway
Bifrost v2.3.0 adds Warp, a dashboard assistant that answers questions about gateway logs, spend and latency, plus semantic log search, both scoped to what the person asking may see.
ToolsExplainer
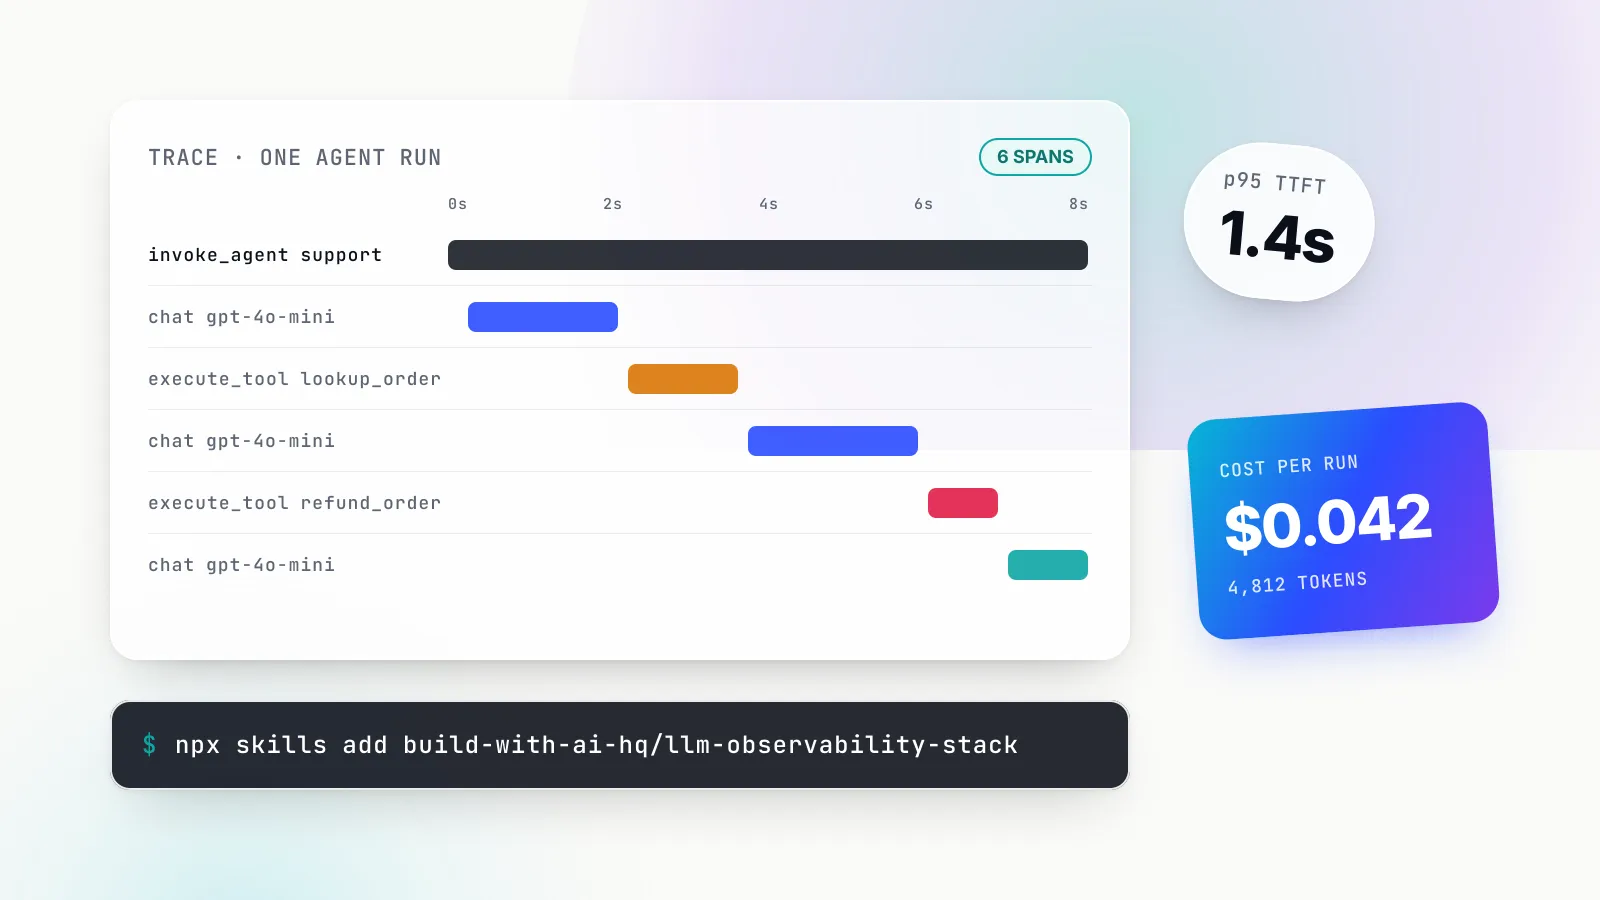
LLM observability: what to capture, how to trace agents, and which tools fit
A working guide to LLM observability: the per-call record, OpenTelemetry GenAI conventions, agent traces, PII redaction, Prometheus alerts, production evals and the tools for each job.
ToolsExplainer
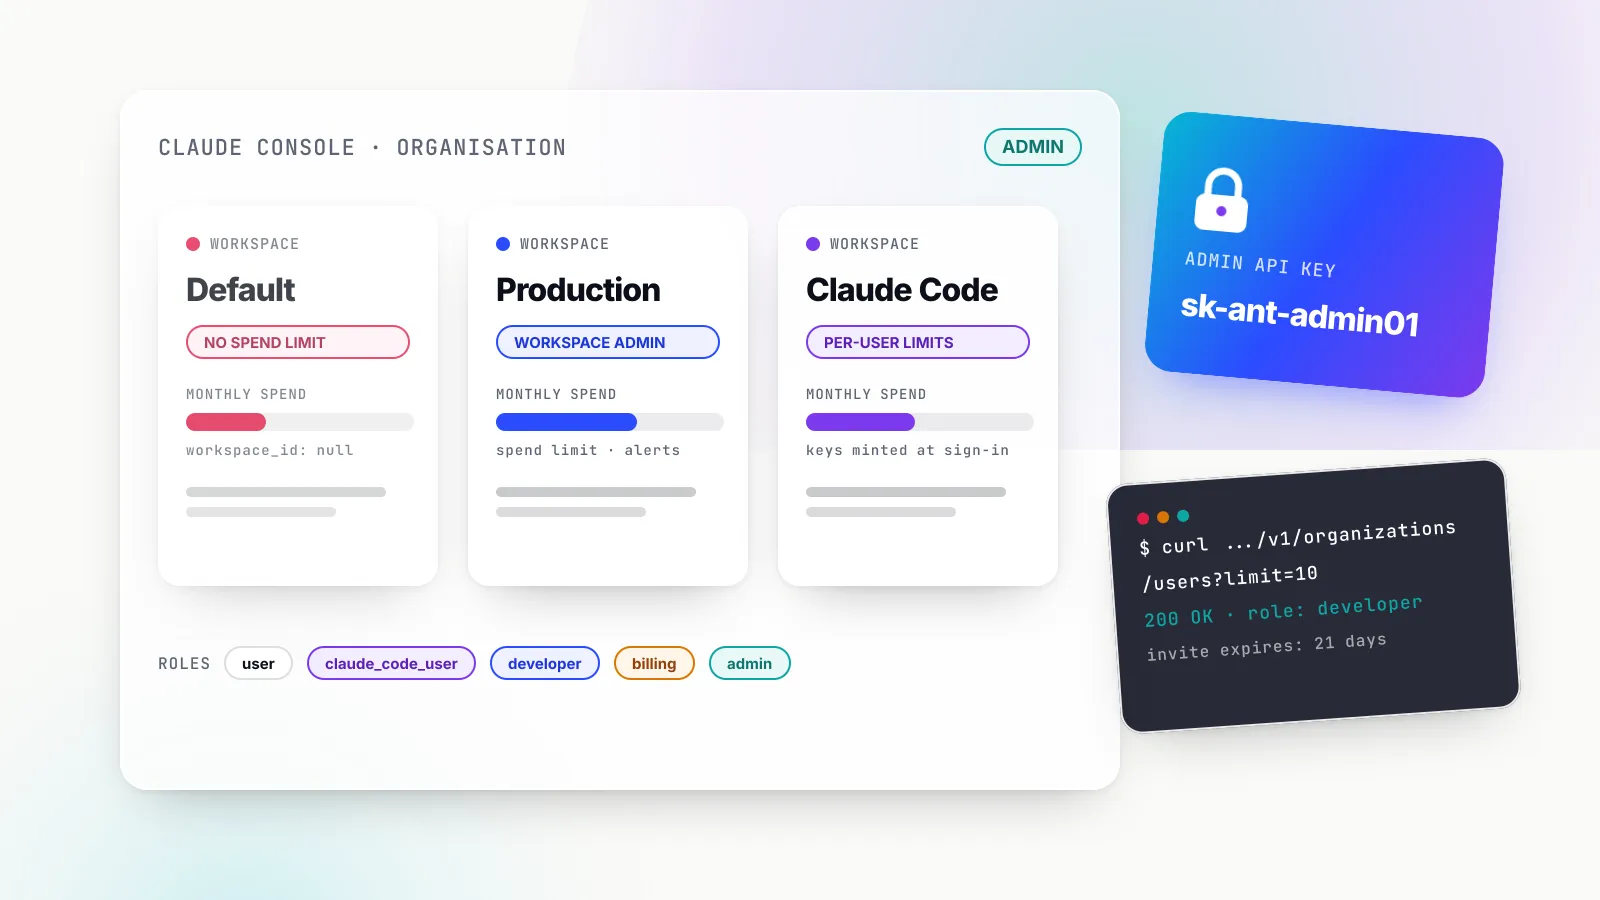
Claude API platform admin: roles, workspaces and the Admin API explained
How to administer the Claude Developer Platform: Console roles, workspaces and their limits, Admin API keys and curl calls, usage and Claude Code reports, SSO and data retention.
ToolsExplainer
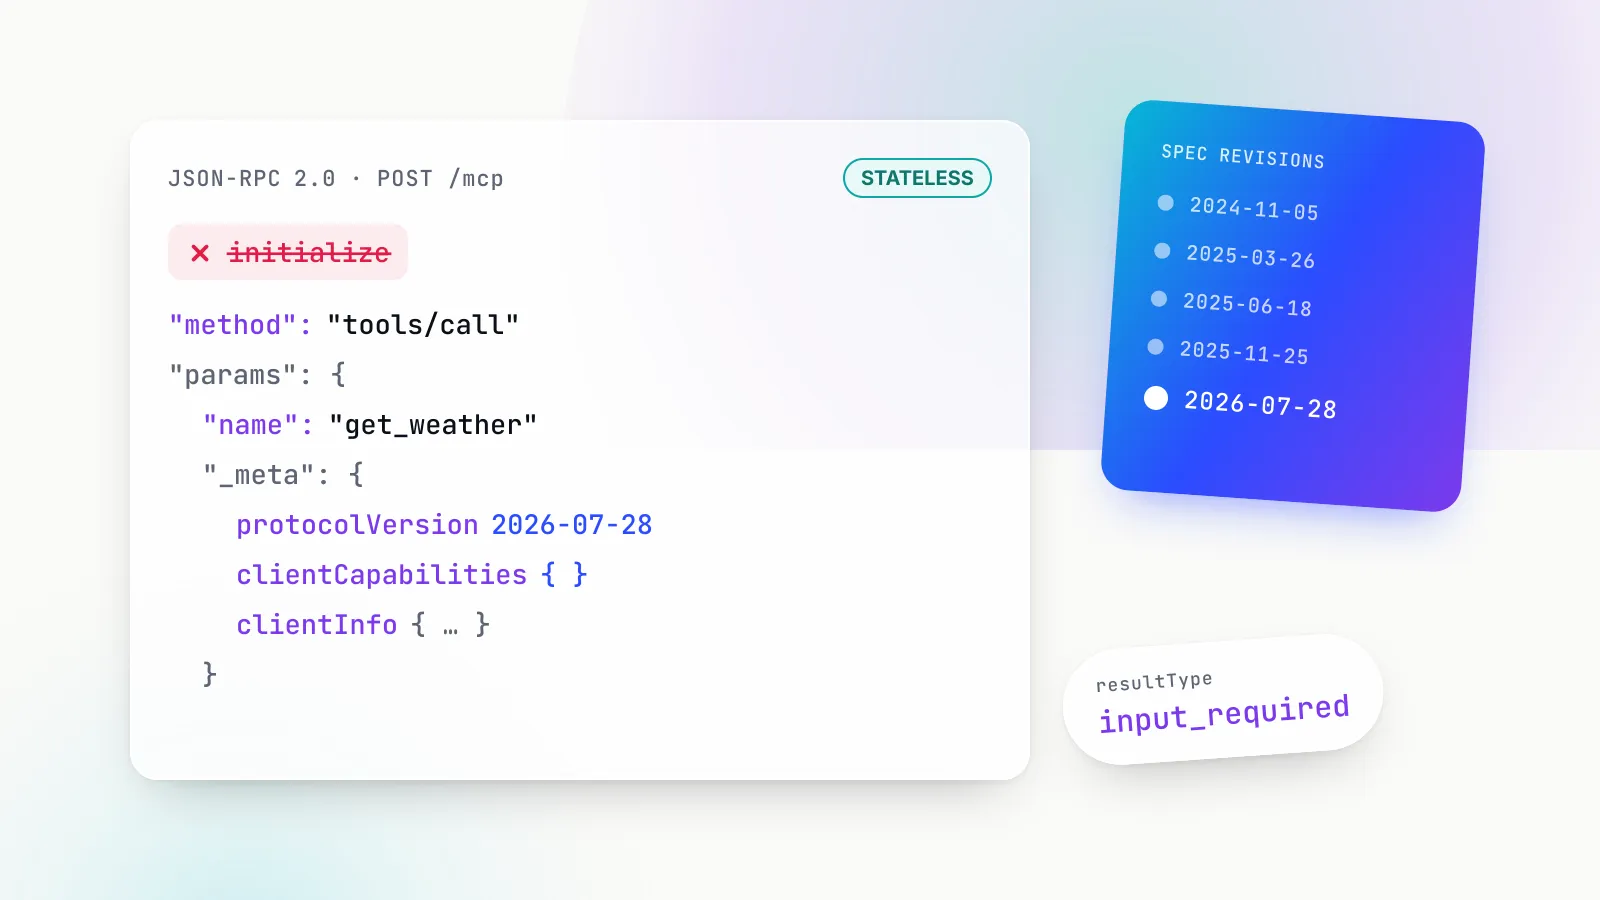
Model Context Protocol: the definitive guide to how MCP works in 2026
A spec-level reference to MCP: history and governance, every revision up to 2026-07-28, the stateless request model, each primitive, transports, extensions, SDK tiers and the limits.
ToolsExplainer
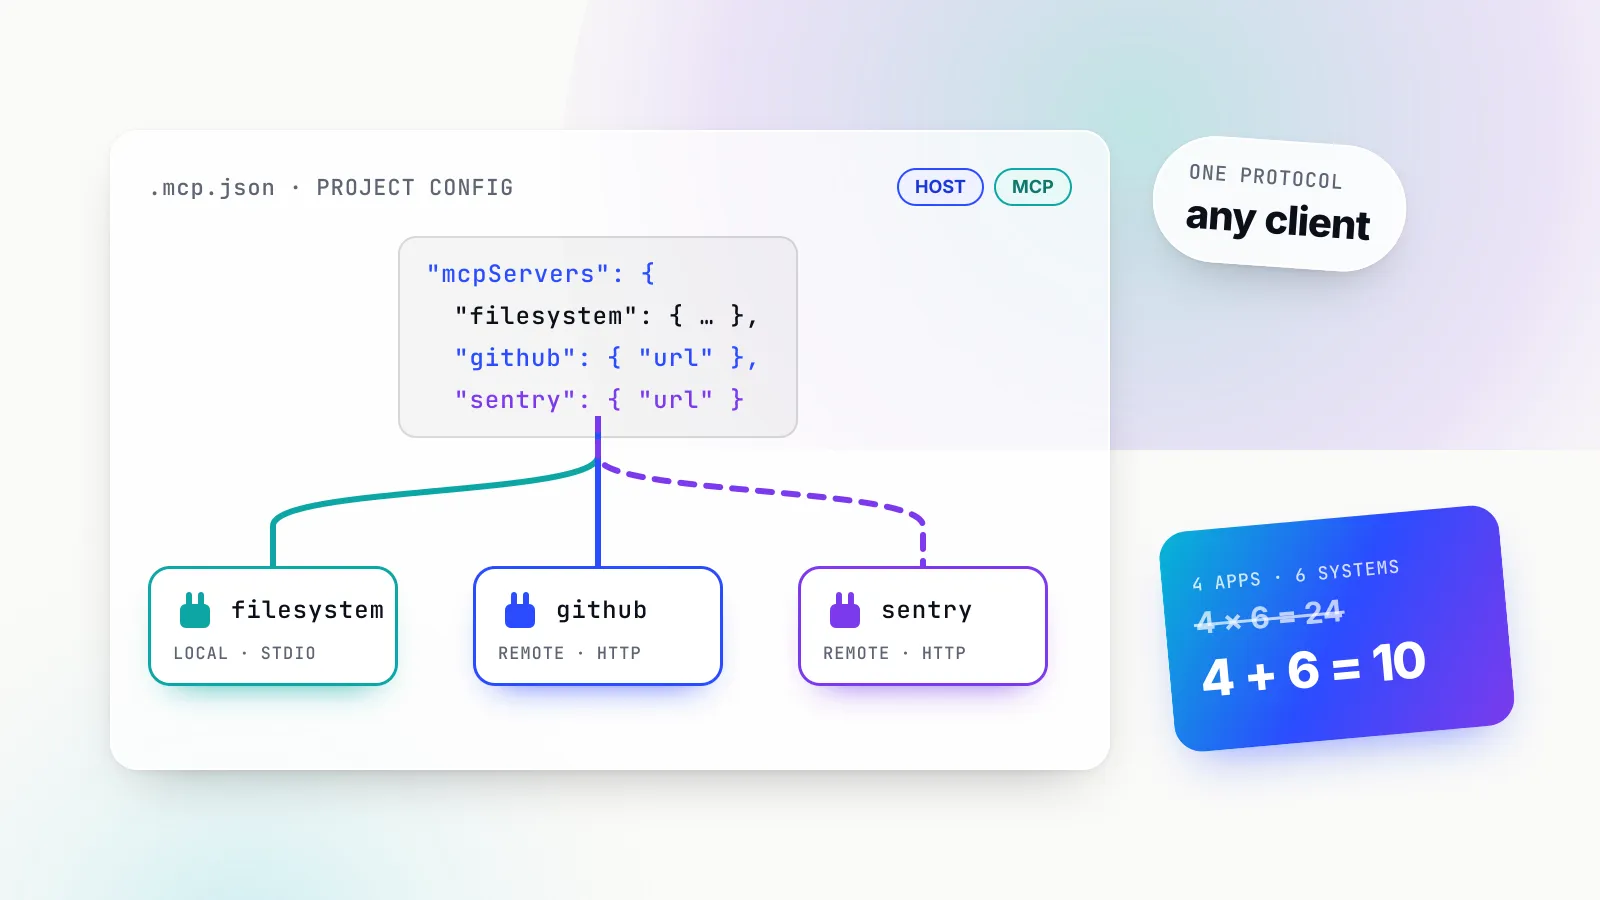
What is MCP? A practical guide to connecting AI apps to your tools
MCP is the open protocol that lets Claude, VS Code and Cursor call your files, repos and SaaS tools. What it is, why it exists, and the exact config to connect your first servers safely.
ToolsExplainer
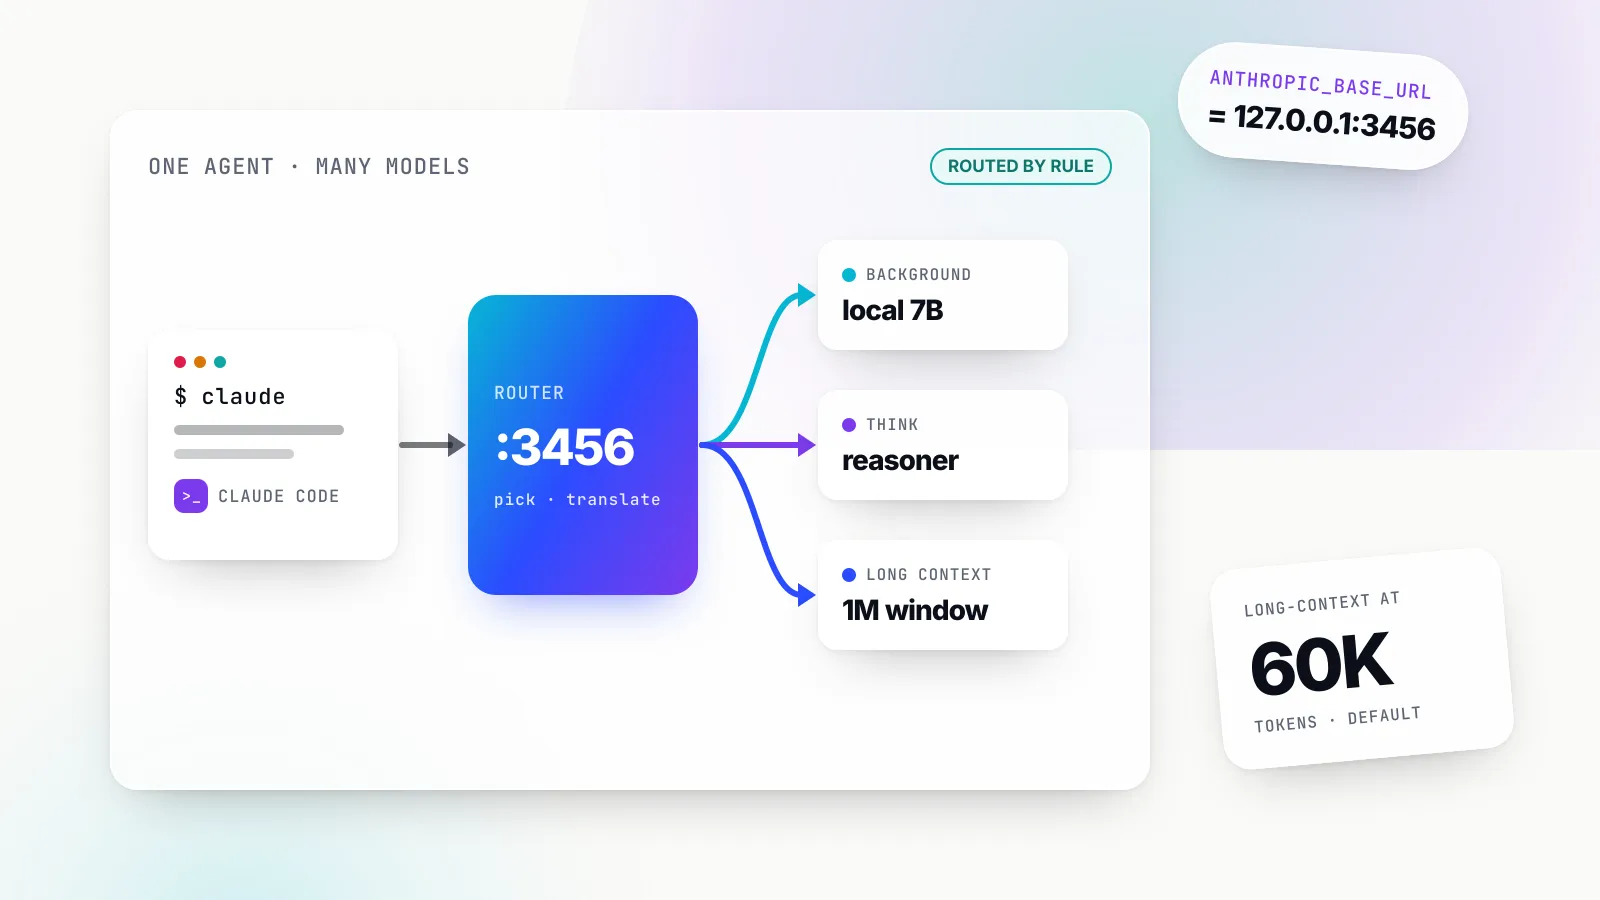
Claude Code Router explained: running Claude Code on GPT, Gemini and local models
How Claude Code Router uses ANTHROPIC_BASE_URL to run Claude Code on other models: setup, routing rules, tool-call and caching caveats, and when a gateway fits.
ToolsComparison
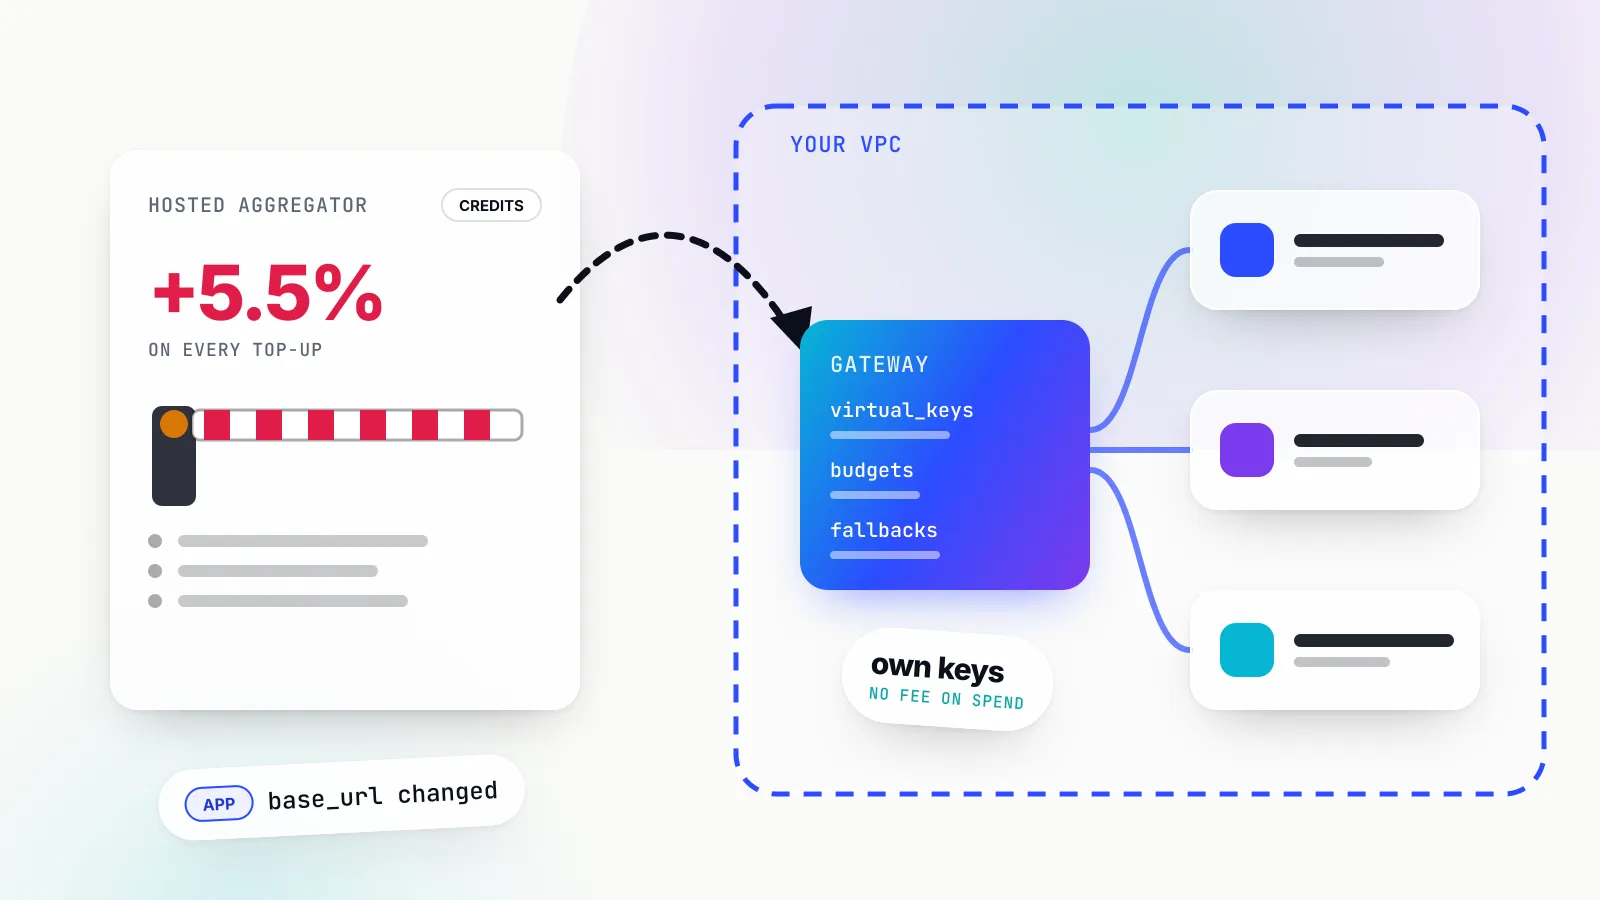
OpenRouter alternatives in 2026: where teams go after a hosted aggregator
Seven OpenRouter alternatives ranked for October 2026: why teams leave a hosted aggregator, what OpenRouter still does well, and where self-hosting pays off.
ModelsExplainer
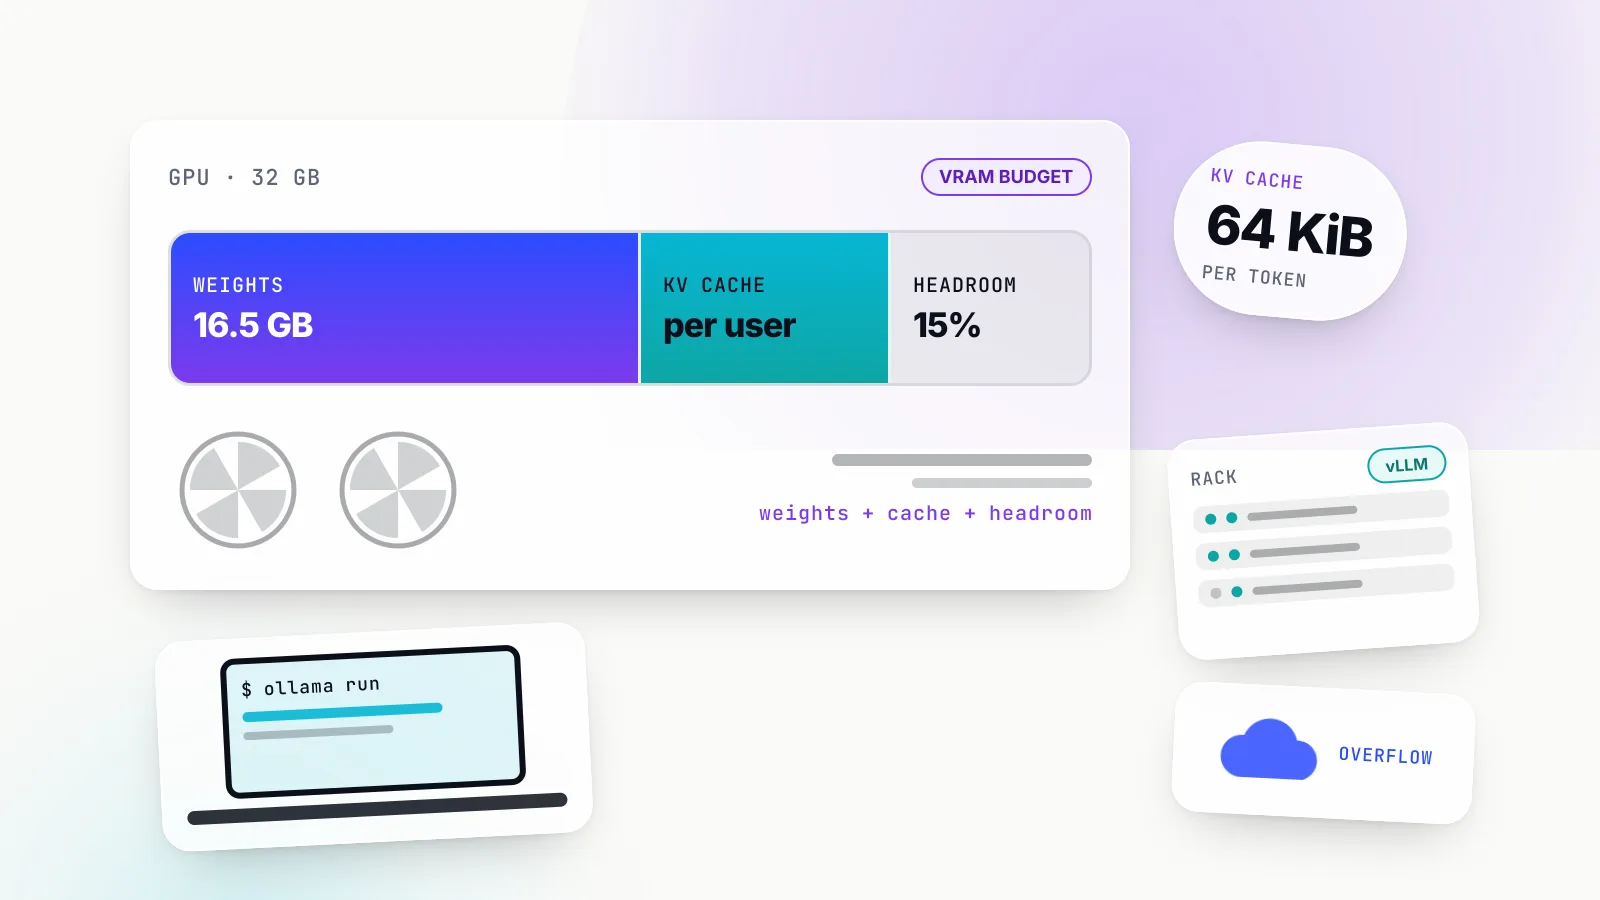
Self-hosted LLM guide for 2026: VRAM maths, Ollama vs vLLM and the break-even
When a self-hosted LLM pays off, how to size GPU memory for weights and KV cache, which inference server fits which job, and what the hardware really costs.
ResearchExplainer
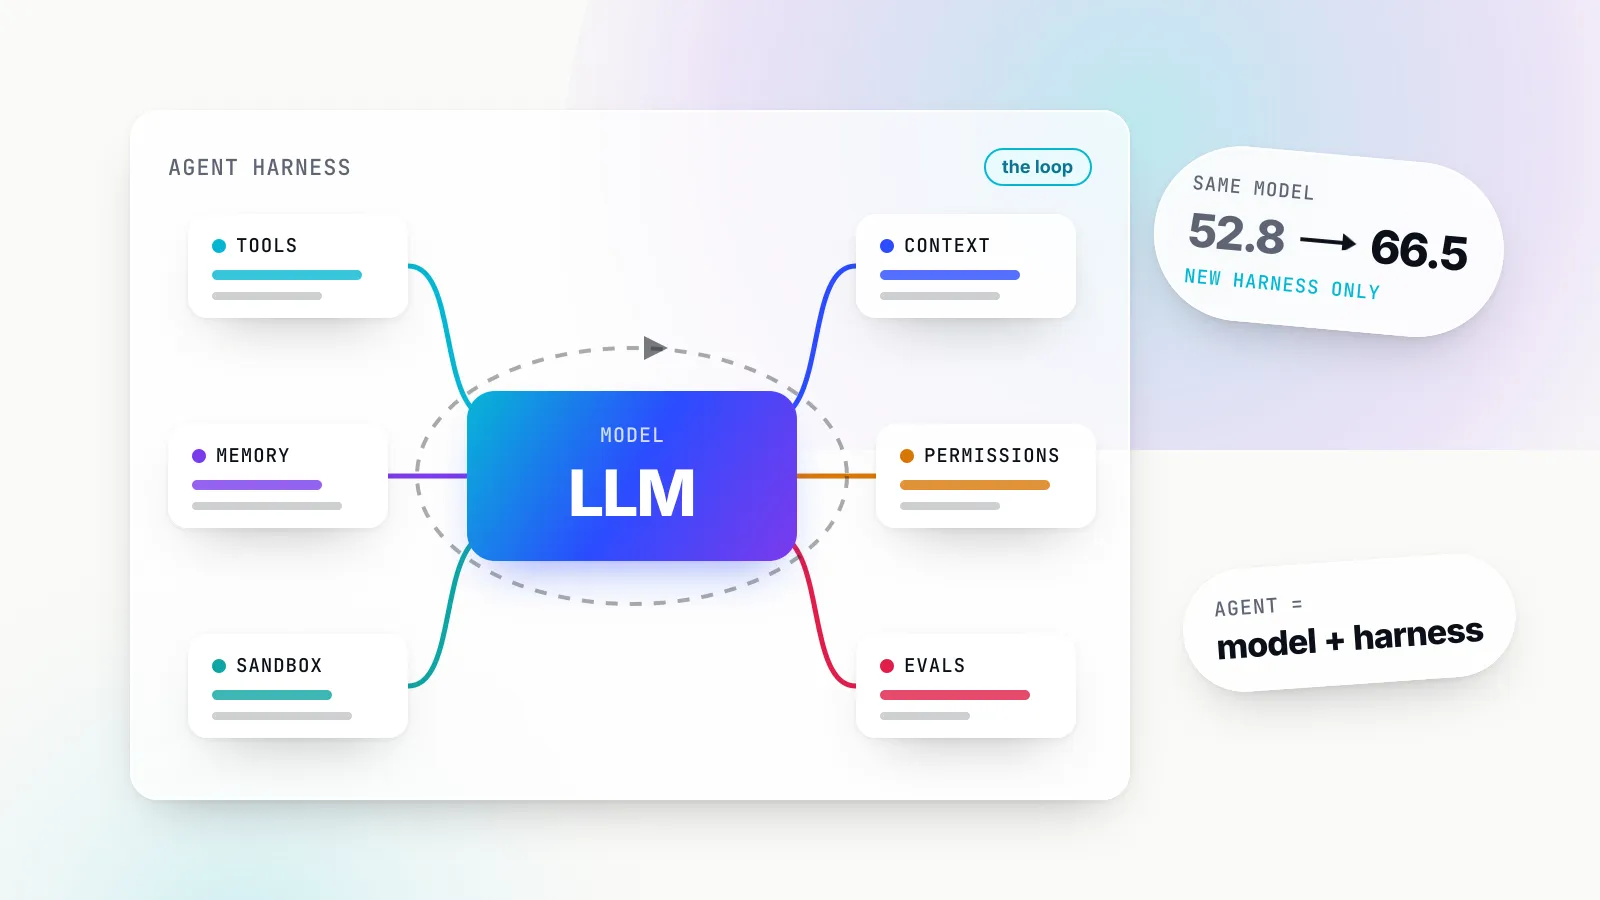
What is an agent harness? The loop, tools and context around the model
An agent harness is everything around the model: the loop, tools, context, memory, permissions and sandbox. Why it moves benchmark scores as much as the model.
ToolsComparison
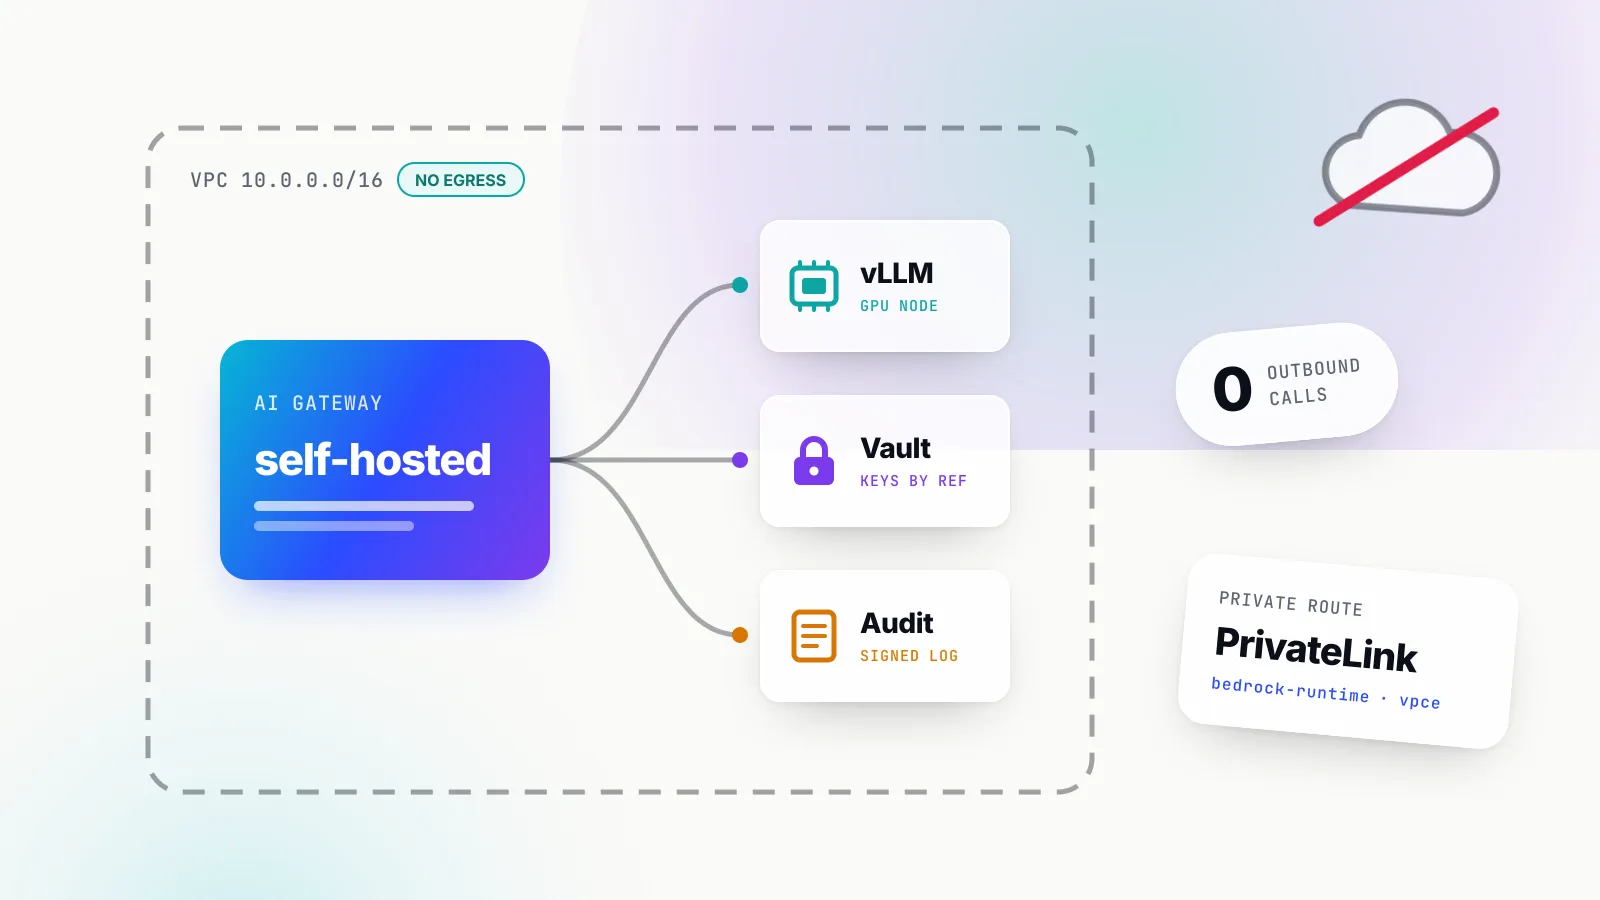
Top 5 AI gateways for air-gapped and in-VPC LLM deployments in 2026
Five self-hosted gateways compared for on premise LLM stacks: offline installs, outbound defaults, private model endpoints, secret stores and audit evidence.
ToolsComparison
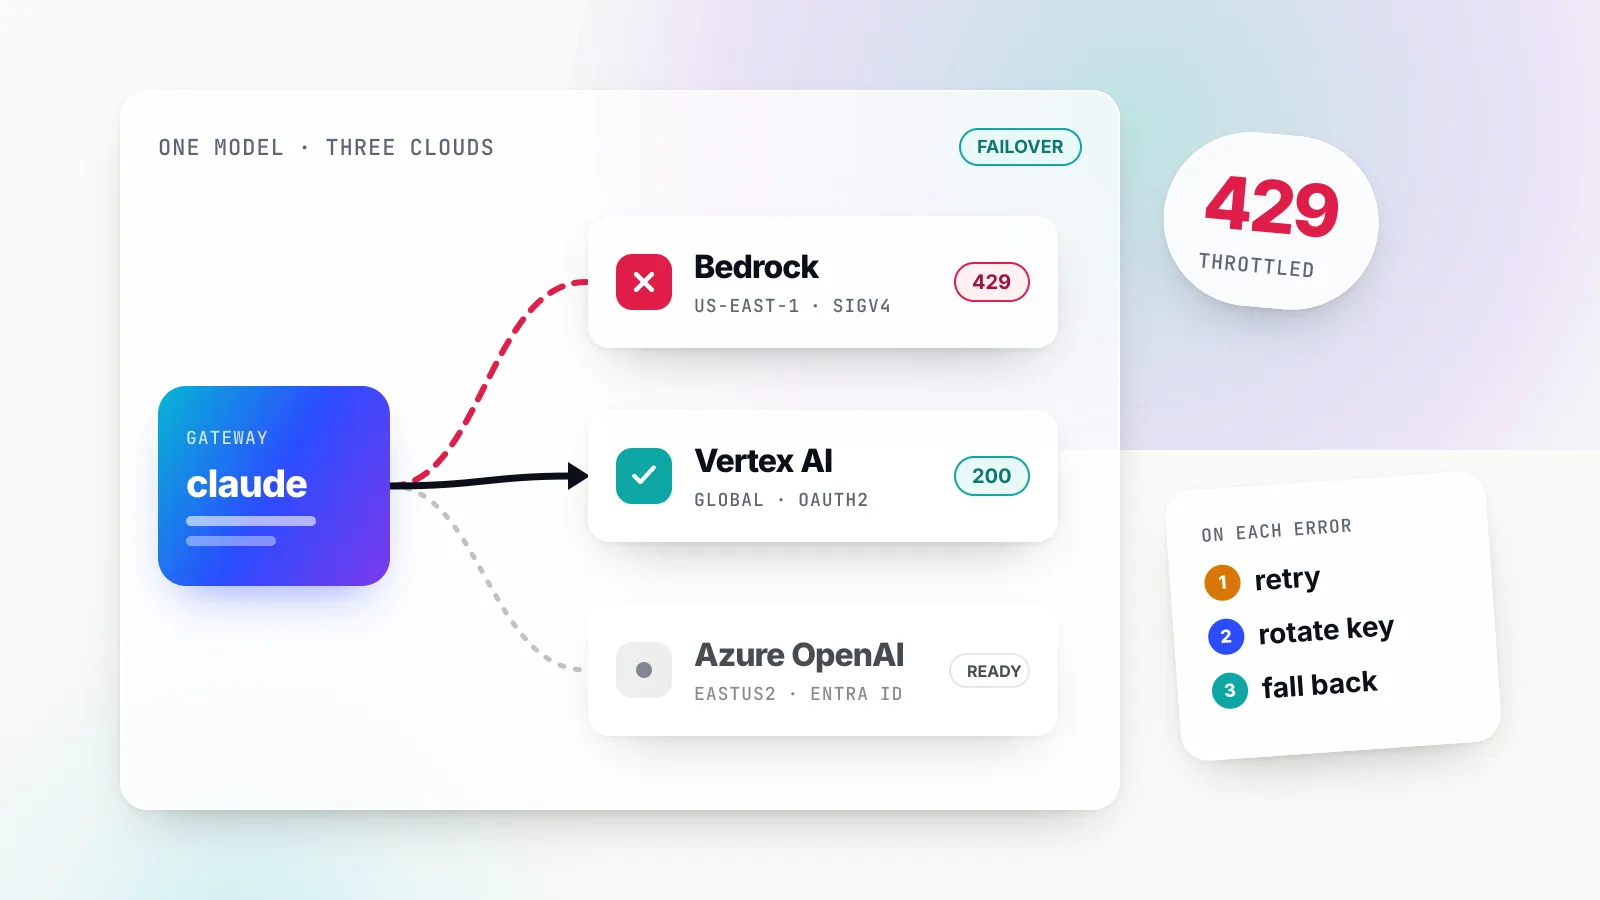
Top 5 AI gateways for failover across Bedrock, Vertex AI and Azure OpenAI in 2026
Bedrock quotas, Vertex AI 429s and Azure OpenAI TPM caps all throttle the same models. Five gateways ranked on how they fail over across the three clouds.
ToolsComparison
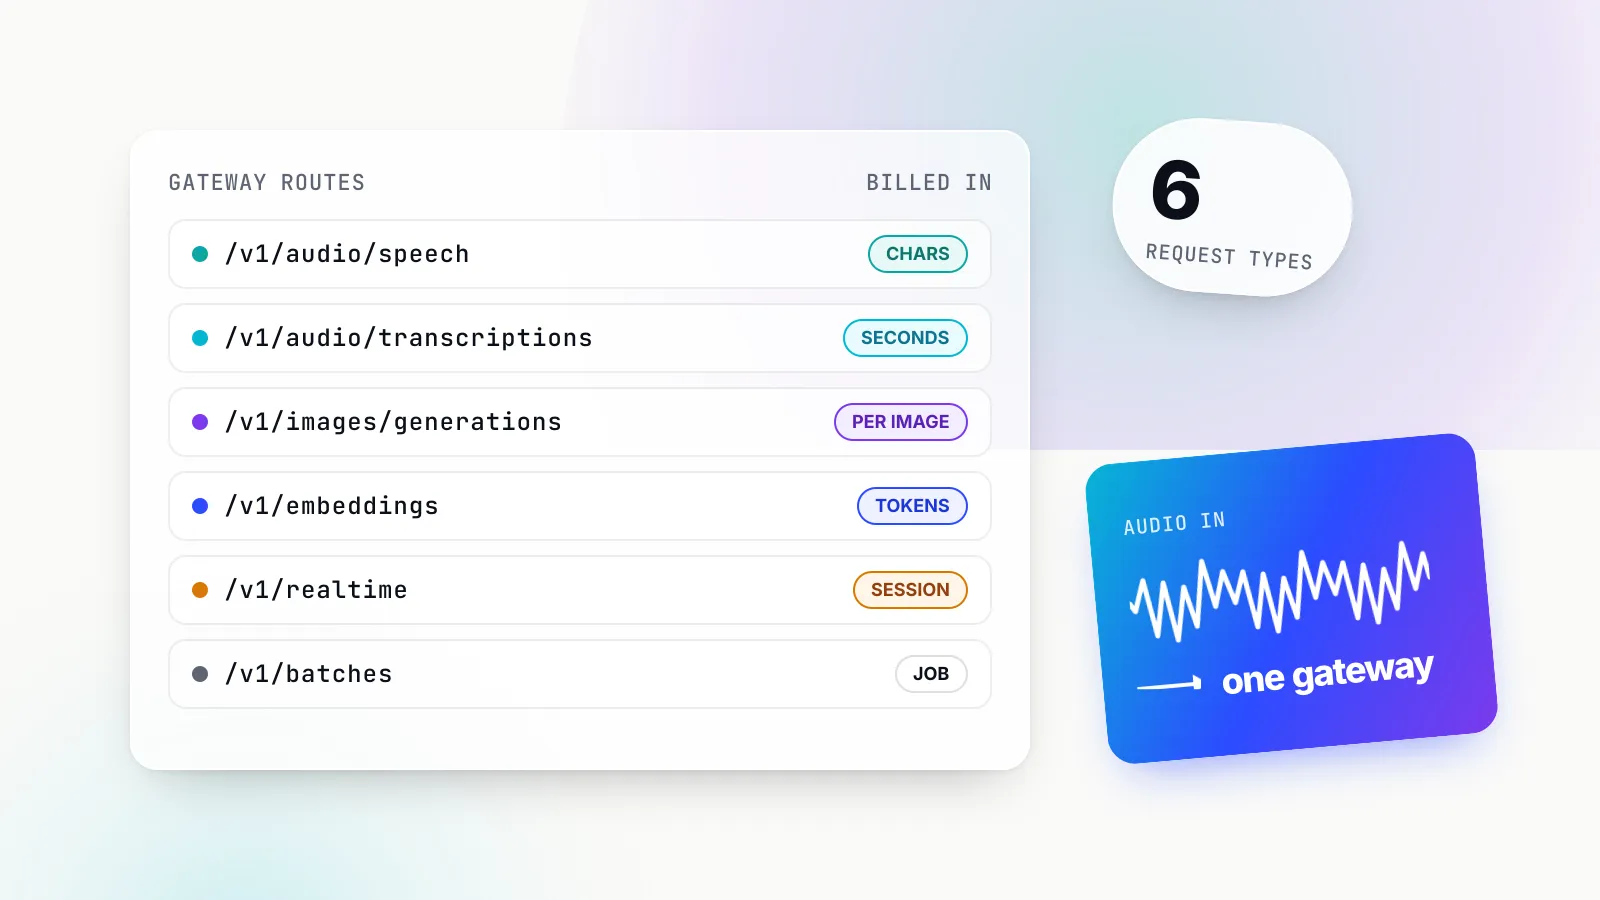
Top 5 AI gateways for multimodal workloads in 2026
Five AI gateways ranked on multimodal LLM traffic: which proxy speech, transcription, images, realtime audio and batch, and how they cache, meter and fail over.
ToolsComparison
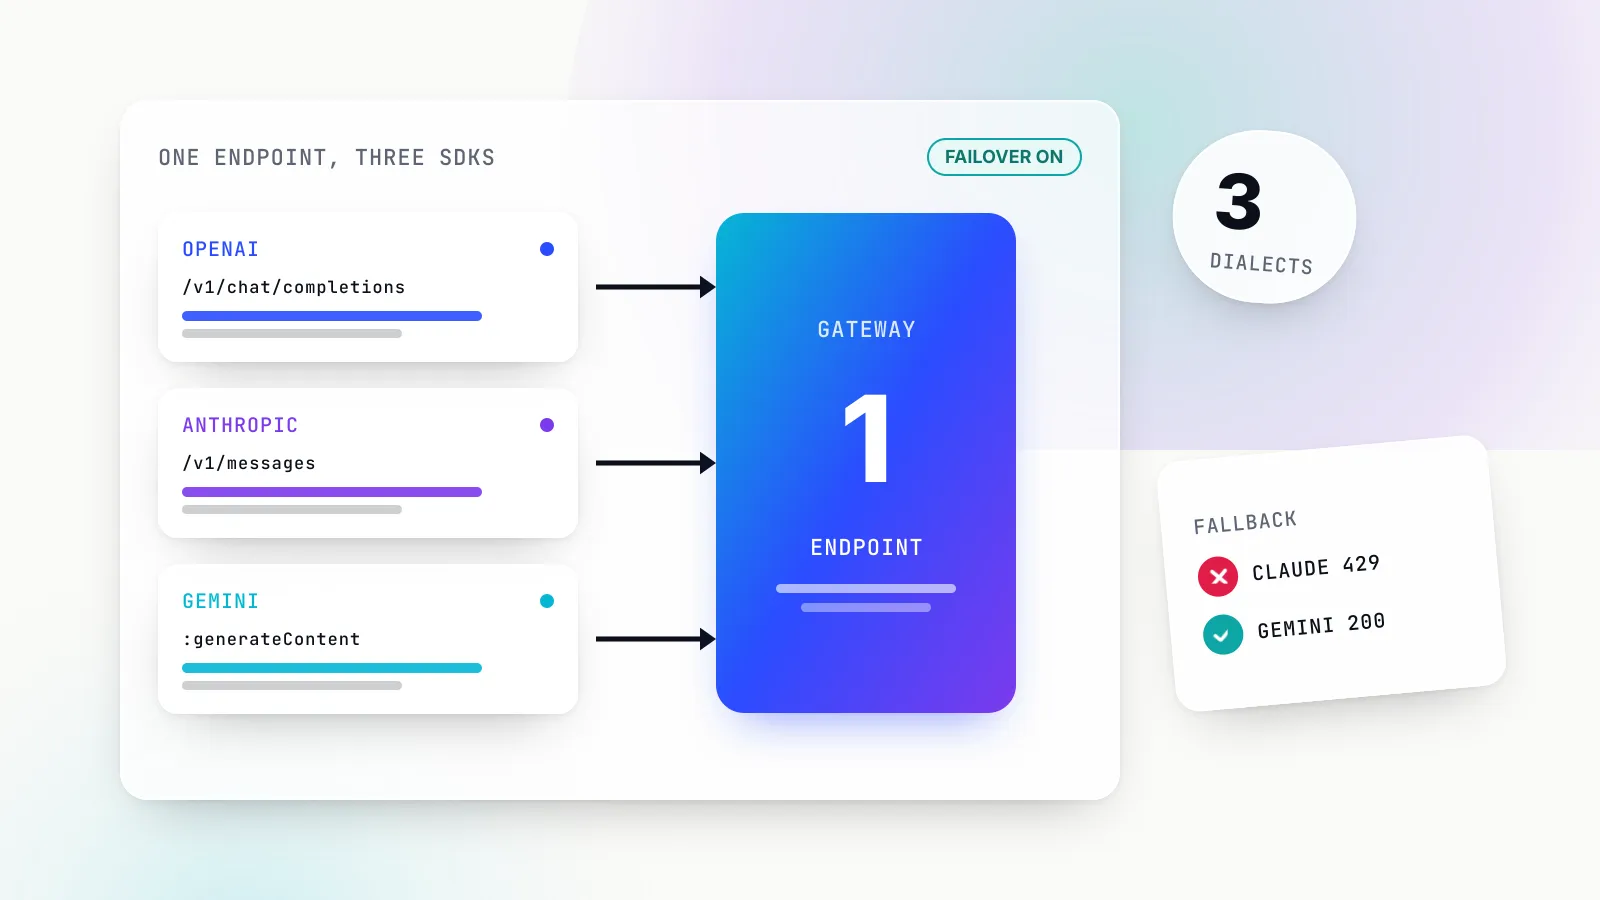
Top 5 AI gateways for Anthropic, OpenAI and Gemini in 2026
An LLM router for OpenAI, Anthropic and Gemini must translate three API dialects. Five gateways ranked on native SDKs, reasoning, caching and failover.
ToolsComparison
Top 5 AI gateways for routing between vLLM, Ollama and cloud LLMs in 2026
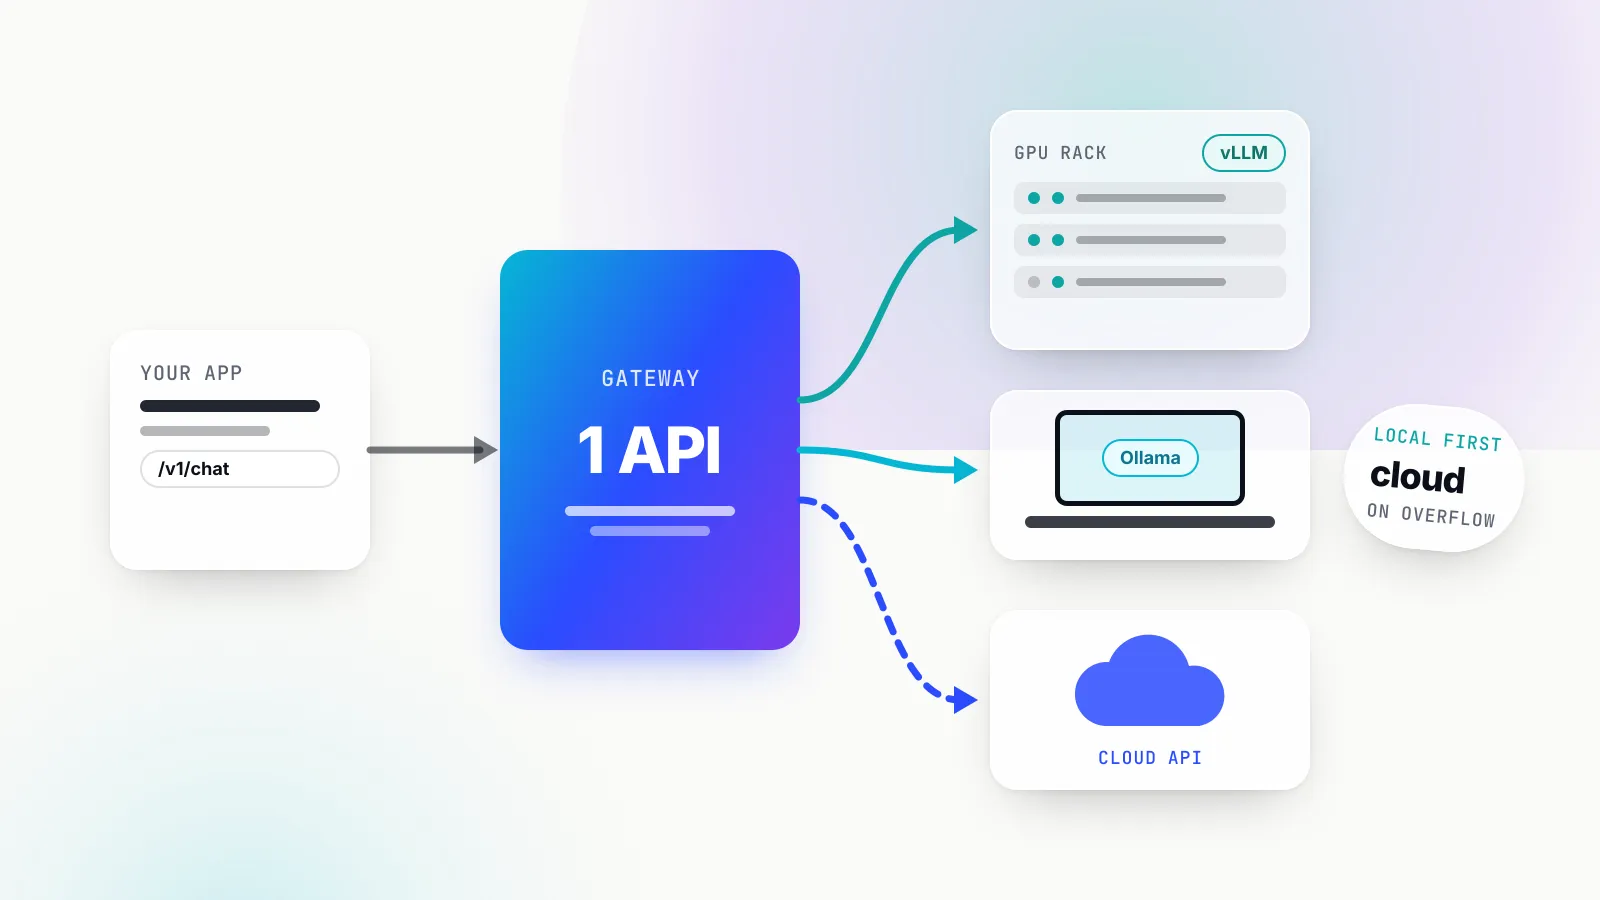
Five AI gateways ranked for hybrid inference: routing between self-hosted vLLM, SGLang and Ollama servers and cloud LLMs, with health checks and failover.
ToolsComparison
Top 10 AI gateways in 2026, ranked for production use
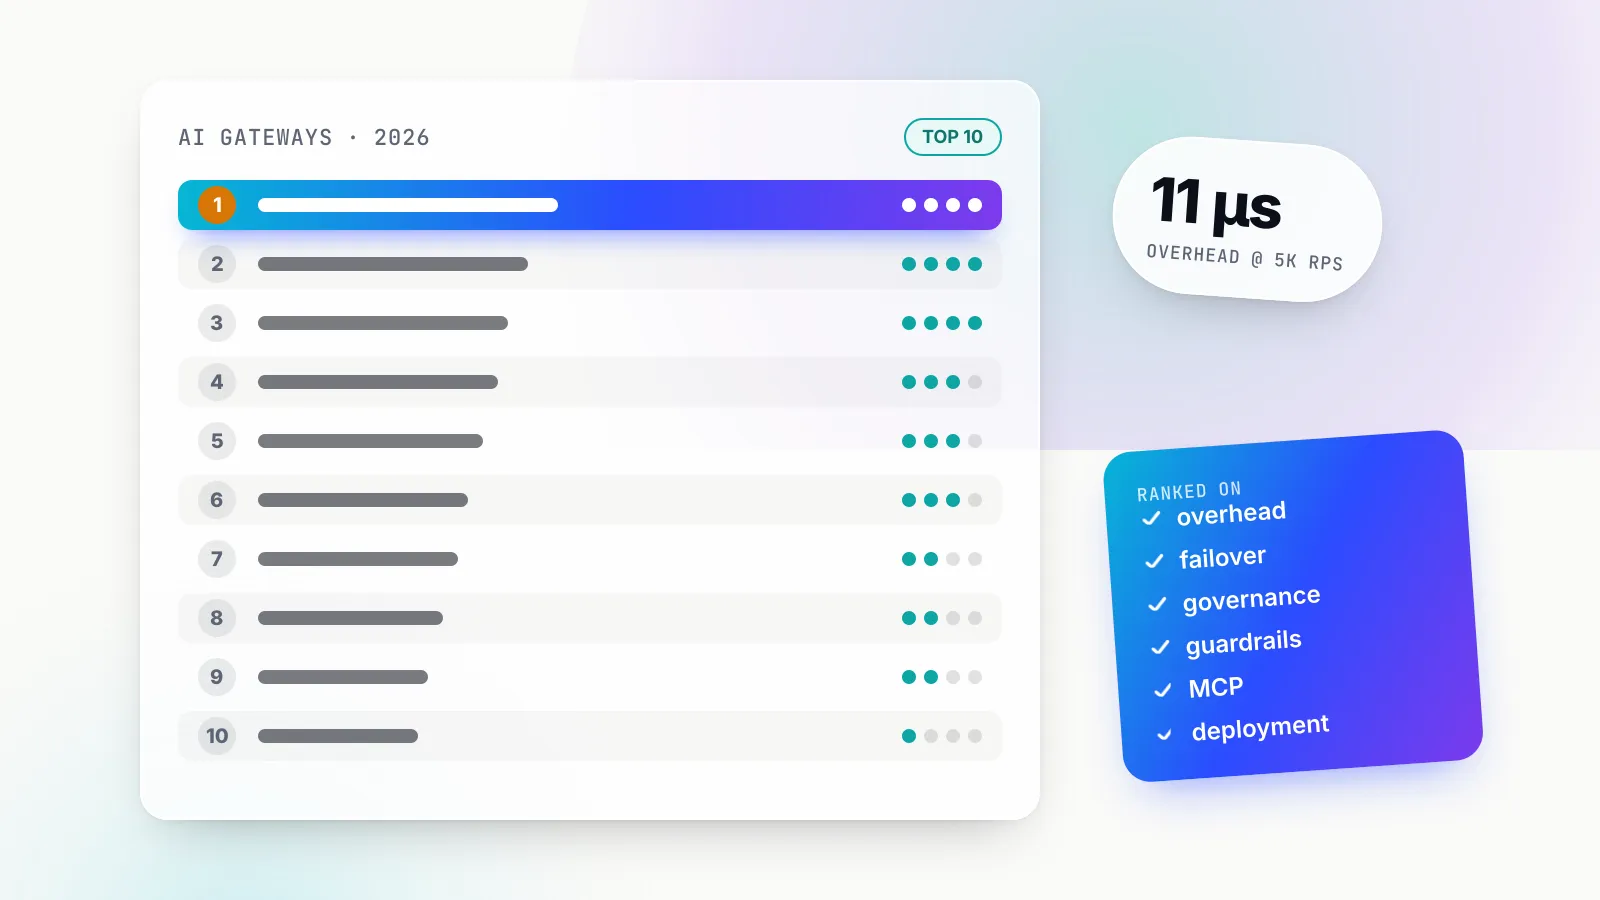
Bifrost, LiteLLM, Kong, Azure API Management, Agent Router, Vercel, Cloudflare, Databricks, OpenRouter and APISIX ranked on overhead, failover, governance, guardrails, MCP and deployment.
IndustryComparison
Top 10 managed agent orchestration platforms for enterprises in 2026
AgentCore, Foundry, Google's Agent Platform, LangSmith, Agentforce, ServiceNow and four more ranked on runtime, identity, memory, MCP and A2A, lock-in, audit, pricing and data residency.
ToolsComparison
Top 10 MCP gateways in 2026, compared for enterprise agent teams
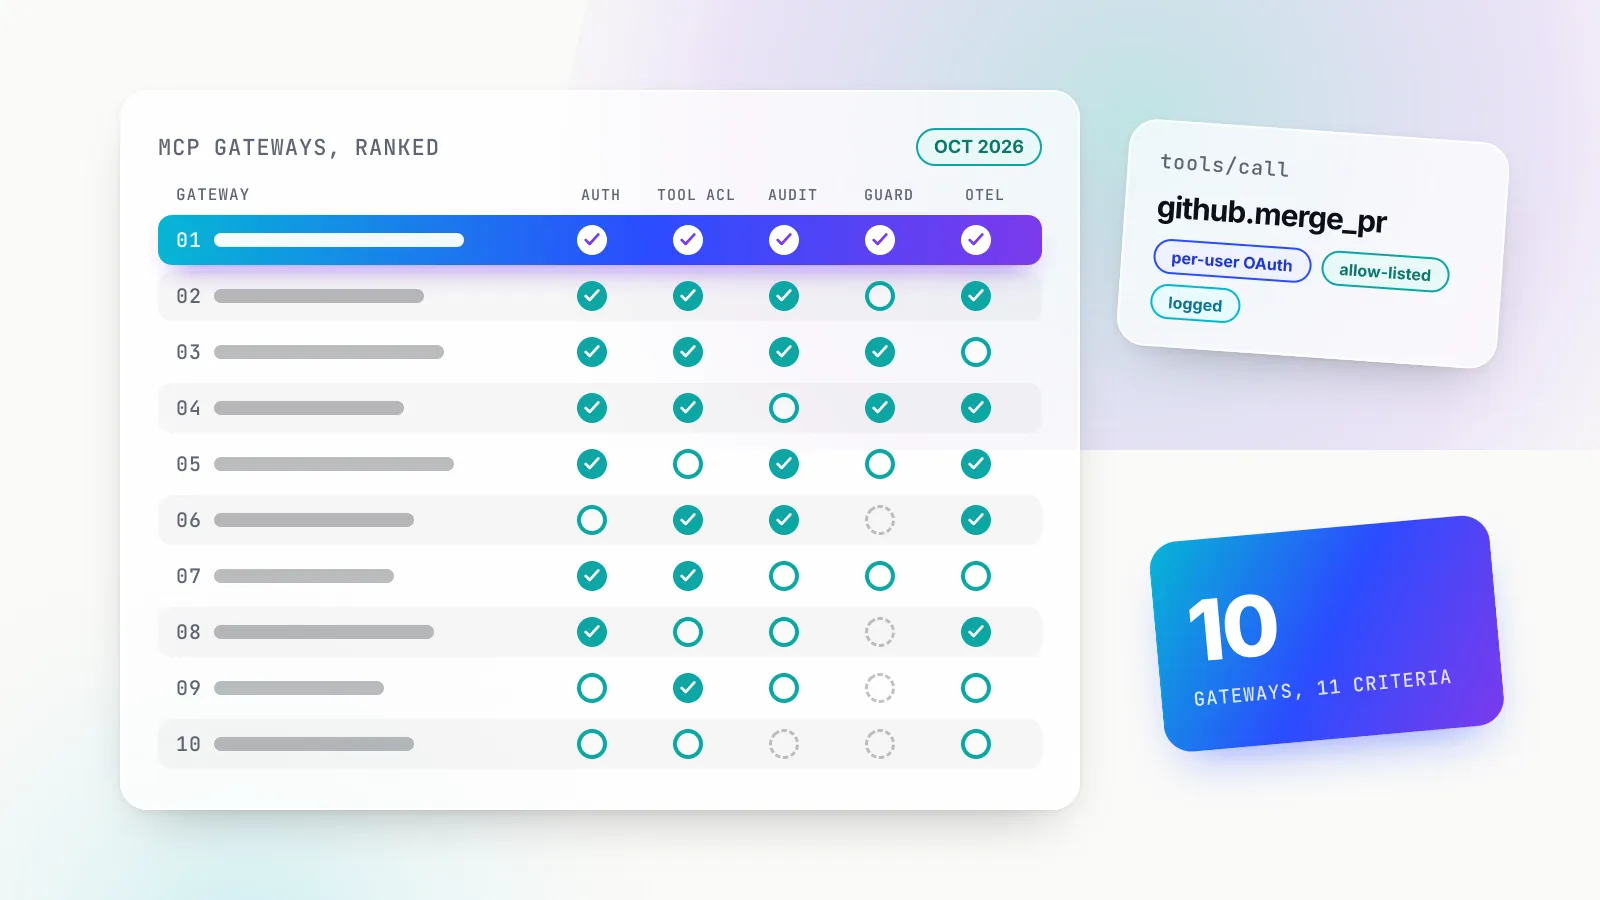
Ten MCP gateways ranked on per-user OAuth, tool-level access control, audit, guardrails on tool calls, observability, LLM routing, deployment and licence, from each vendor's documentation.
ToolsComparison
Top 10 MCP servers in 2026, and how to run them safely
GitHub, Playwright, Context7, Atlassian, Notion, Slack, Sentry, Supabase, Stripe and Figma ranked on maintenance, transport, auth, tool scoping and security record, read from each vendor's docs.
ToolsComparison
Ten open-source AI gateways you can self-host in 2026, ranked
Bifrost, LiteLLM, Kuadrant, Agent Router, APISIX, Higress, Kong, MLflow, Plano and New API ranked on licence, what the free tier holds back, footprint, MCP, governance and air-gapped fit.
ToolsComparison
Top 10 open-source MCP gateways you can self-host in 2026
Ten MCP gateways you can run on your own infrastructure, ranked on what the free tier actually includes: OAuth, per-tool access control, audit, guardrails, deployment and community health.
ModelsComparison
Top 10 open-weight models in October 2026, ranked for teams that self-host
MiMo-V2.6-Pro, GLM-5.3, DeepSeek V4.1 and seven more, ranked on independent evals, licence terms, active parameters, hardware and serving support, each read from its own model card.
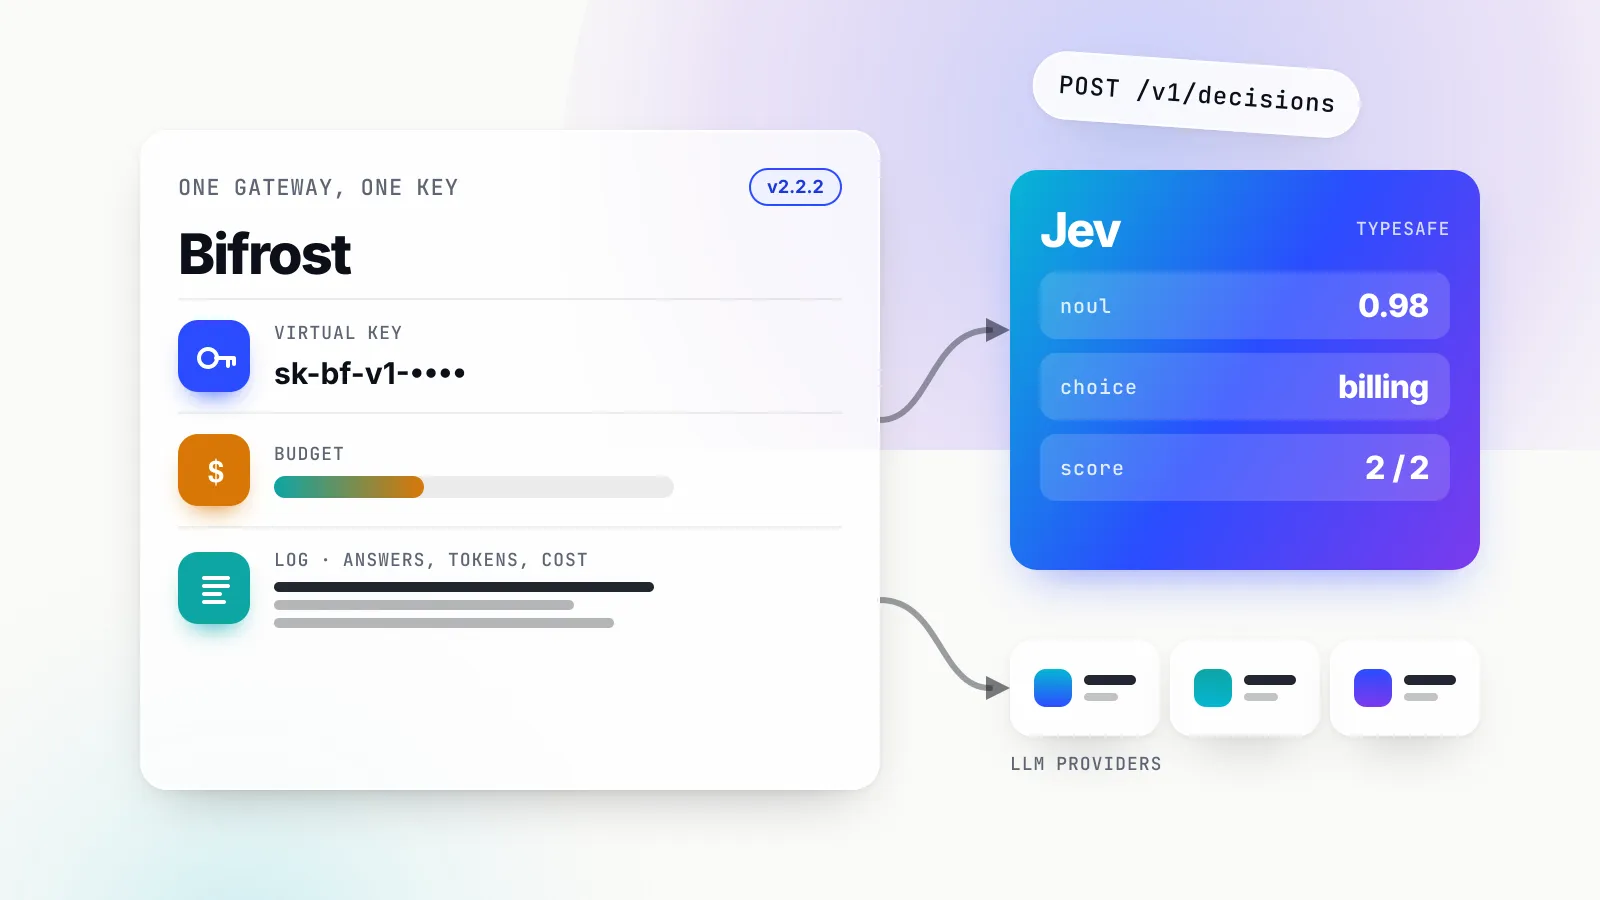
Bifrost now routes TypeSafe's Jev, with a decisions API and LLM fallbacks
Bifrost v2.2.2 adds TypeSafe as a provider. Jev's official SDKs work by changing one base URL, and a new /v1/decisions endpoint brings virtual keys, budgets, logs and fallbacks to decision calls.
ToolsComparison
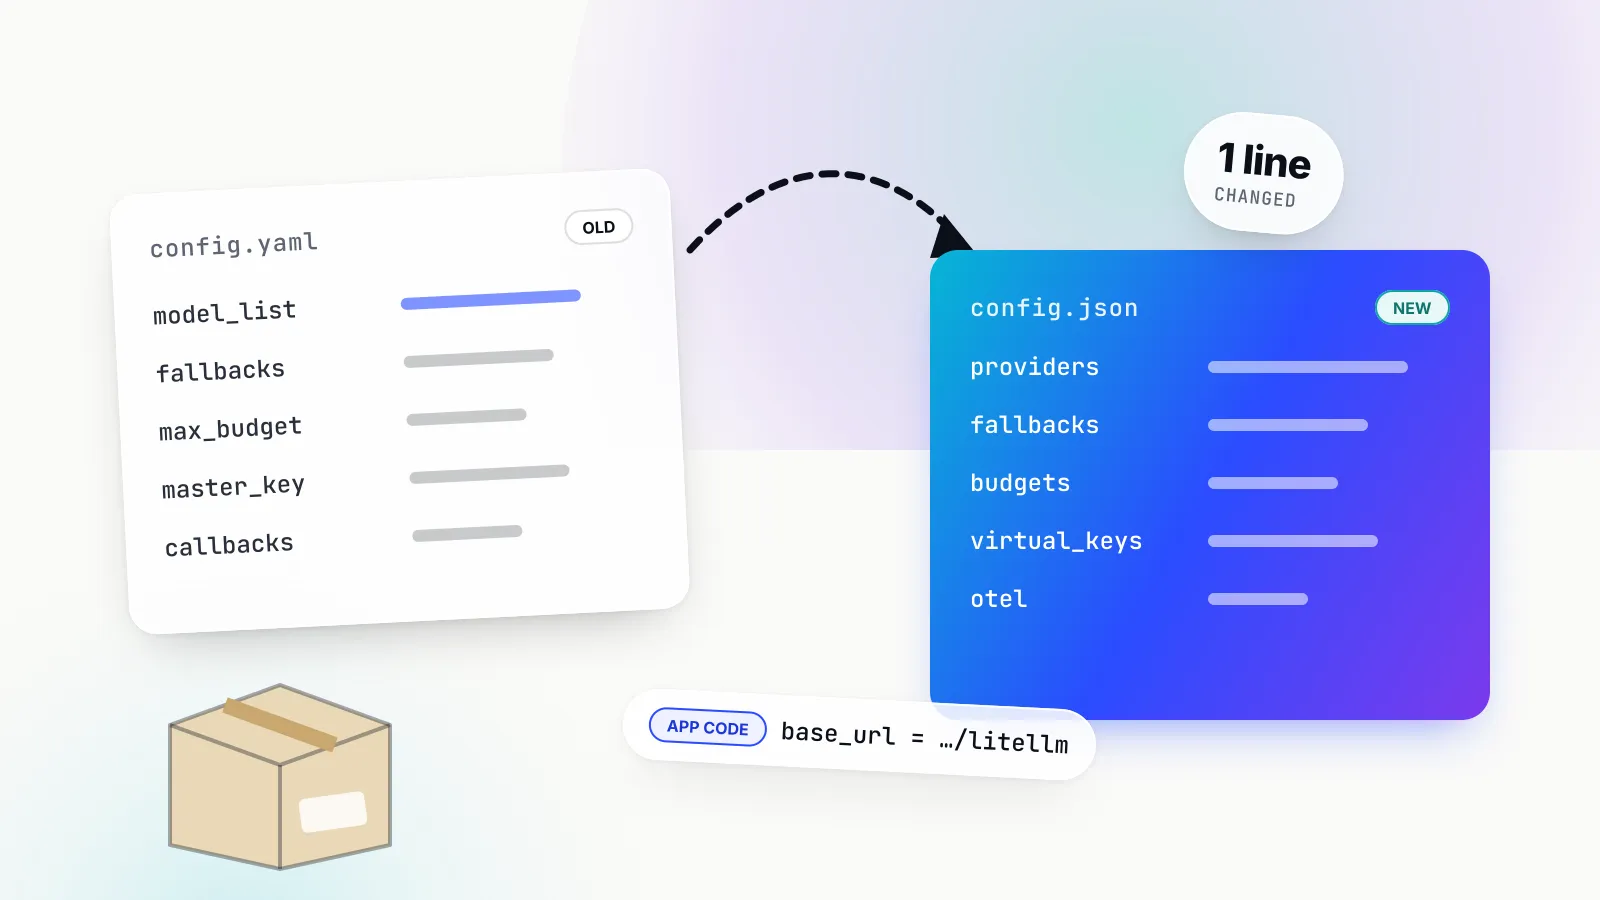
LiteLLM alternatives in 2026: why teams switch and where they go
LiteLLM alternatives compared: why teams outgrow the Python proxy, six gateways ranked with Bifrost first, and a config-by-config path for migrating off LiteLLM.
ToolsExplainer
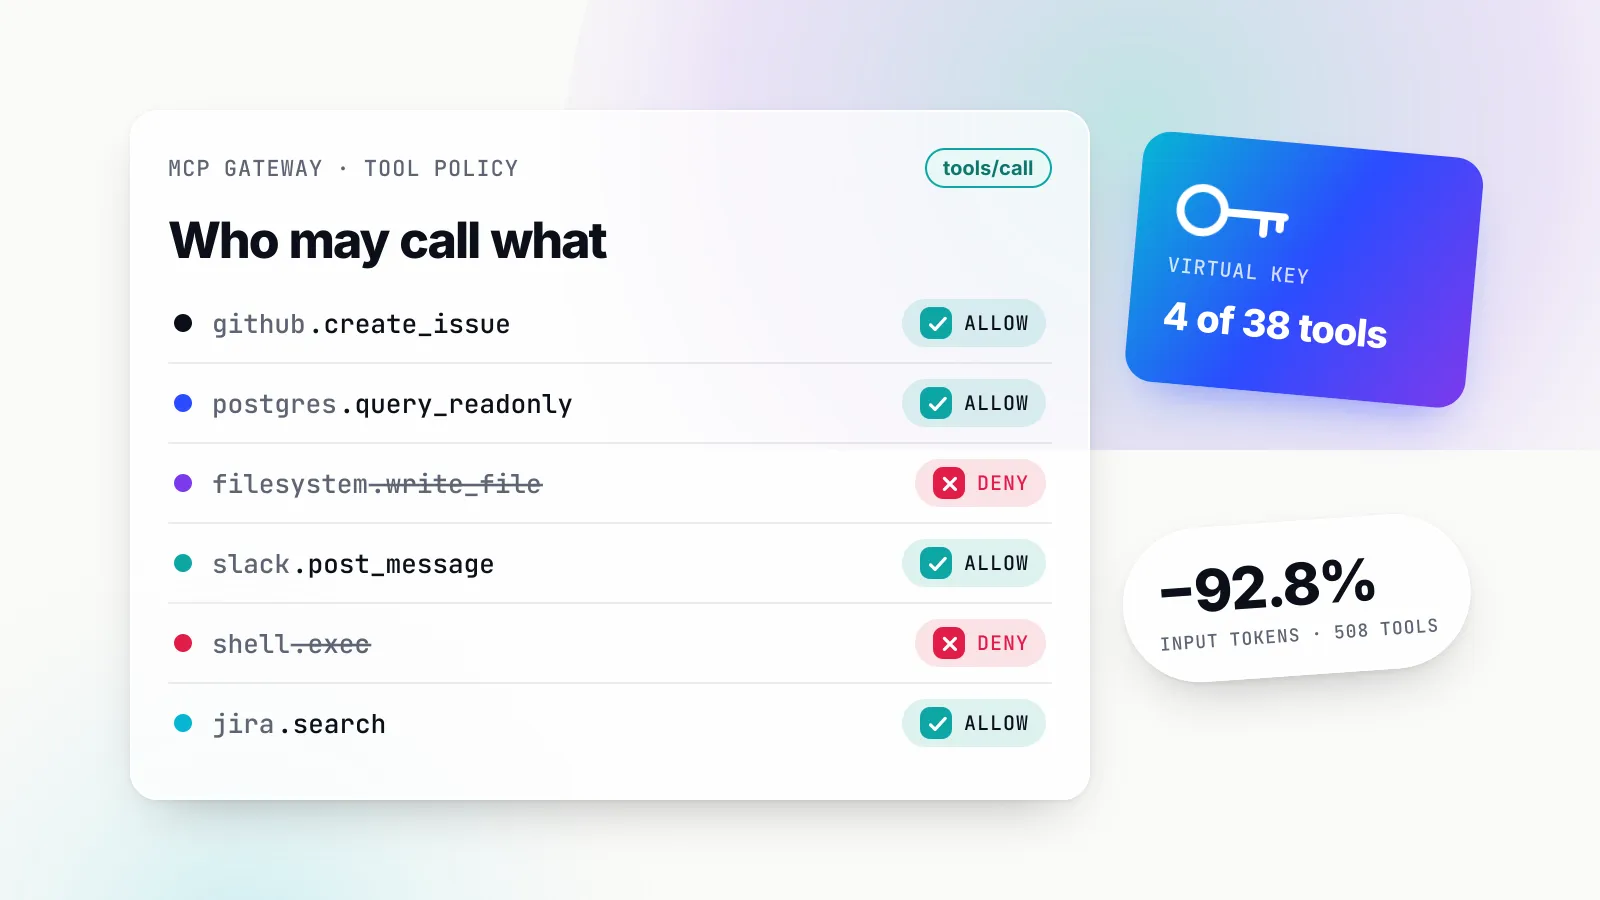
MCP gateway explained: what it does and when agent teams need one
An MCP gateway puts one governed endpoint between agents and the MCP servers they call. How tool filtering, upstream auth, audit and token control work, and where the risks sit.
ToolsExplainer
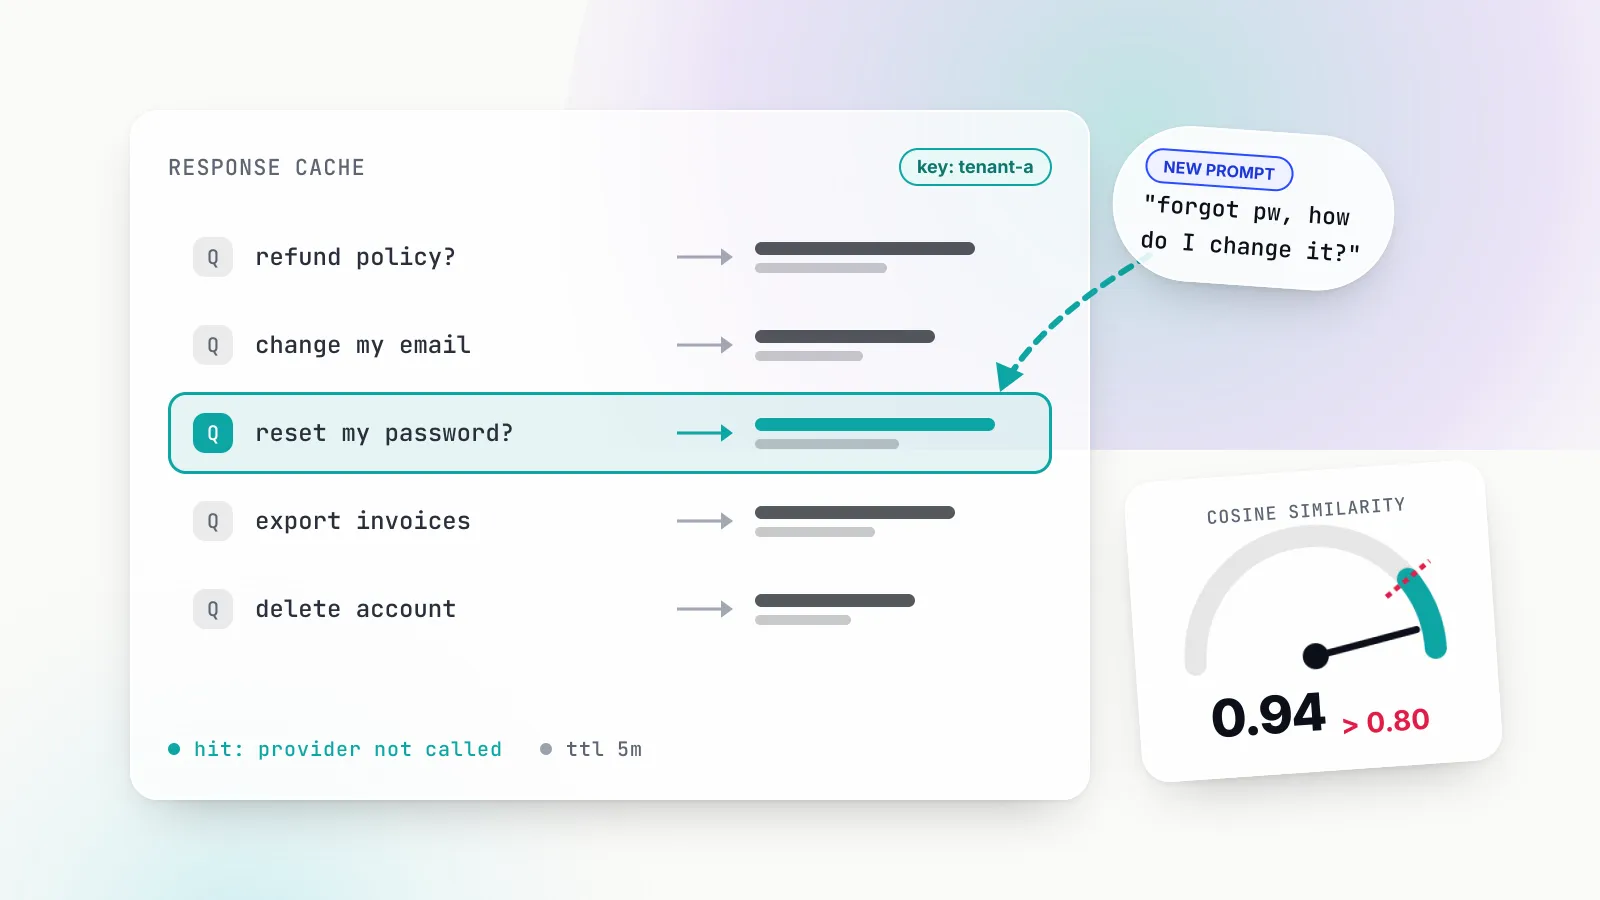
Semantic caching for LLMs: how it works and where it goes wrong
Semantic caching replays a stored LLM answer when a new prompt means the same thing. How thresholds, vector stores and cache keys work, how it differs from prompt caching, and how to measure savings.
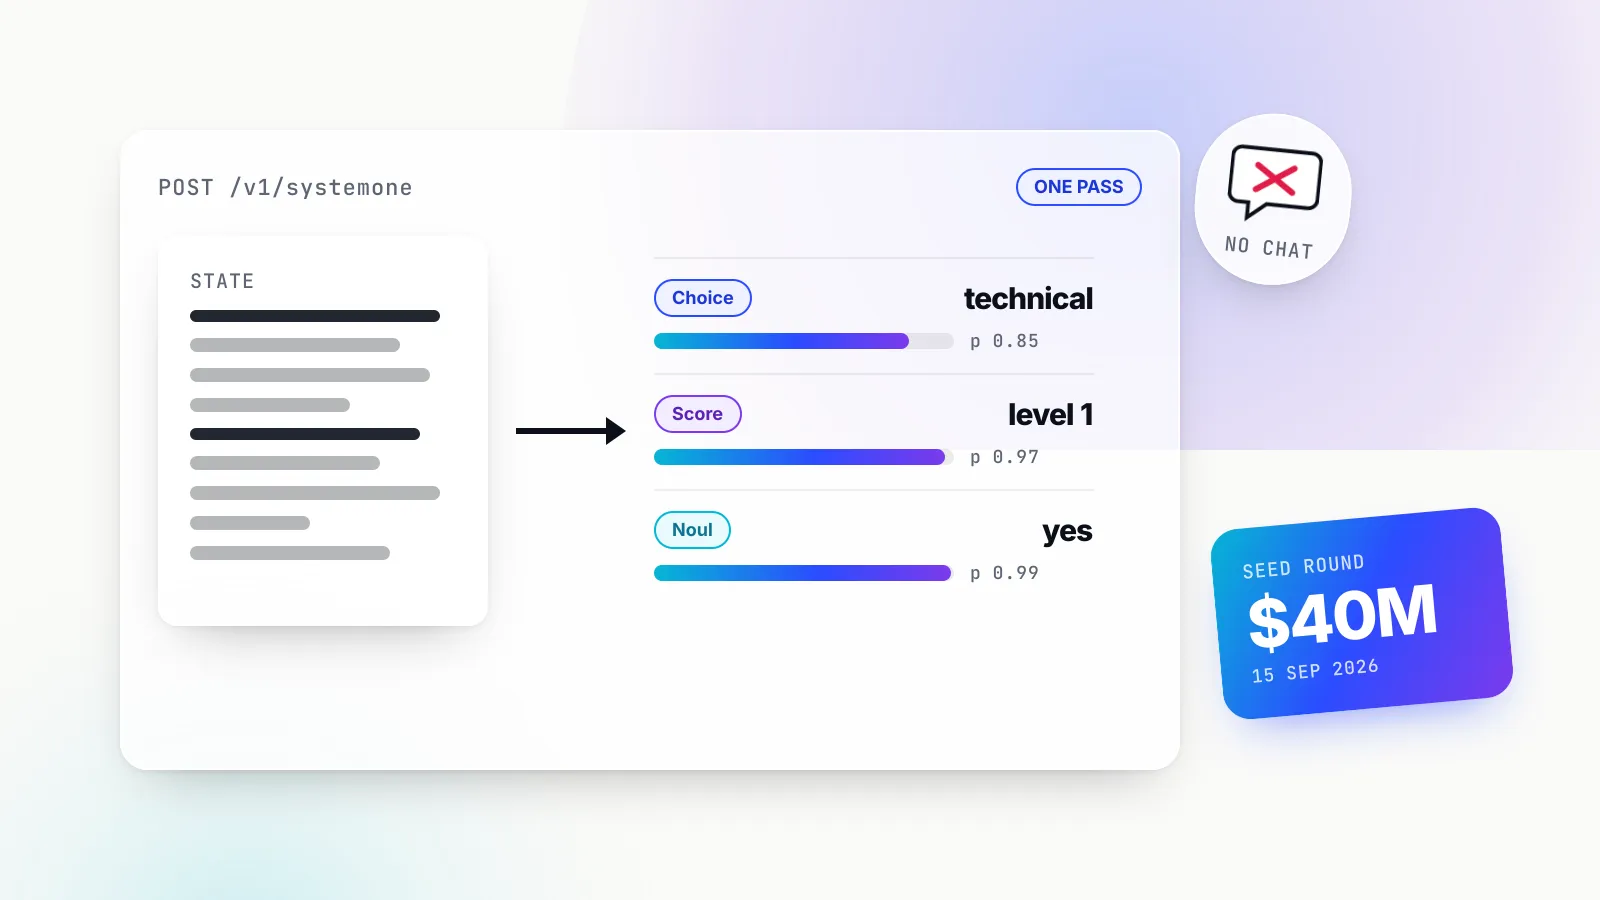
TypeSafe AI launches Jev, a $40M bet on AI that decides instead of chats
Jev takes text state and typed questions and returns calibrated probabilities in one pass, at $0.042 per million input tokens. What launched, who built it, and what the evidence shows so far.
ToolsExplainer
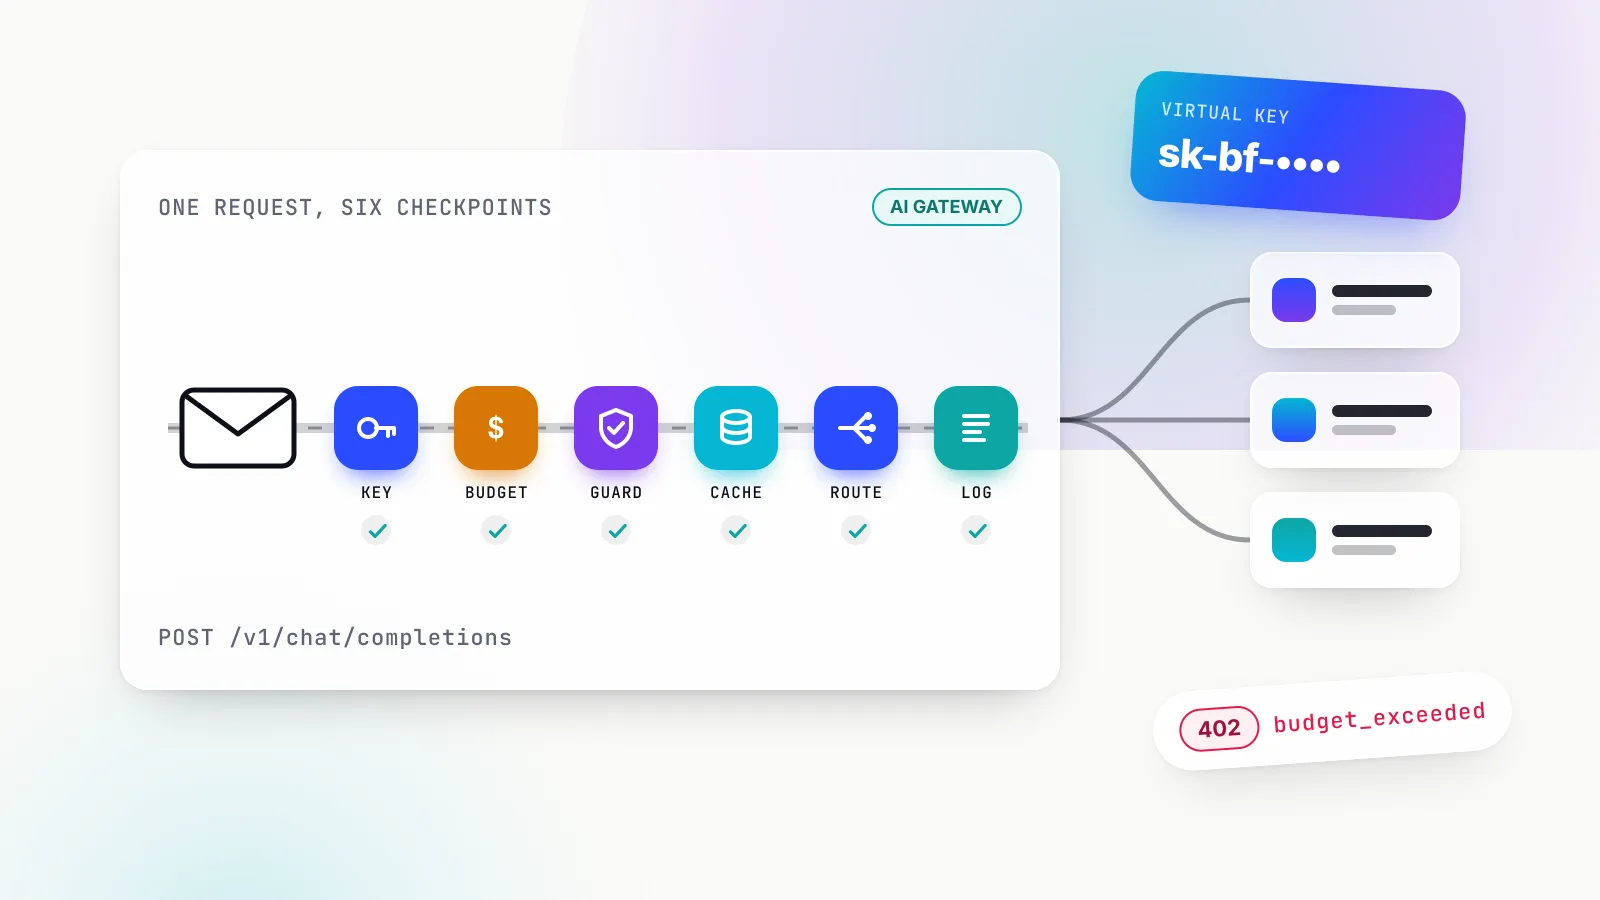
What is an AI gateway? How it works, when you need one and how to choose
An AI gateway sits between applications and model providers to handle keys, budgets, failover, caching, guardrails and logs. How the request path works, and when a team actually needs one.
ToolsComparison
Five LLM gateways compared: failover, governance, MCP and where each one fits
Bifrost, LiteLLM, Kong, Cloudflare and Vercel AI Gateway compared on overhead, error semantics, budgets, guardrails, MCP routing, deployment and licence, read from each vendor's own documentation.