Topic
Pricing
11 stories on this topic, newest first.
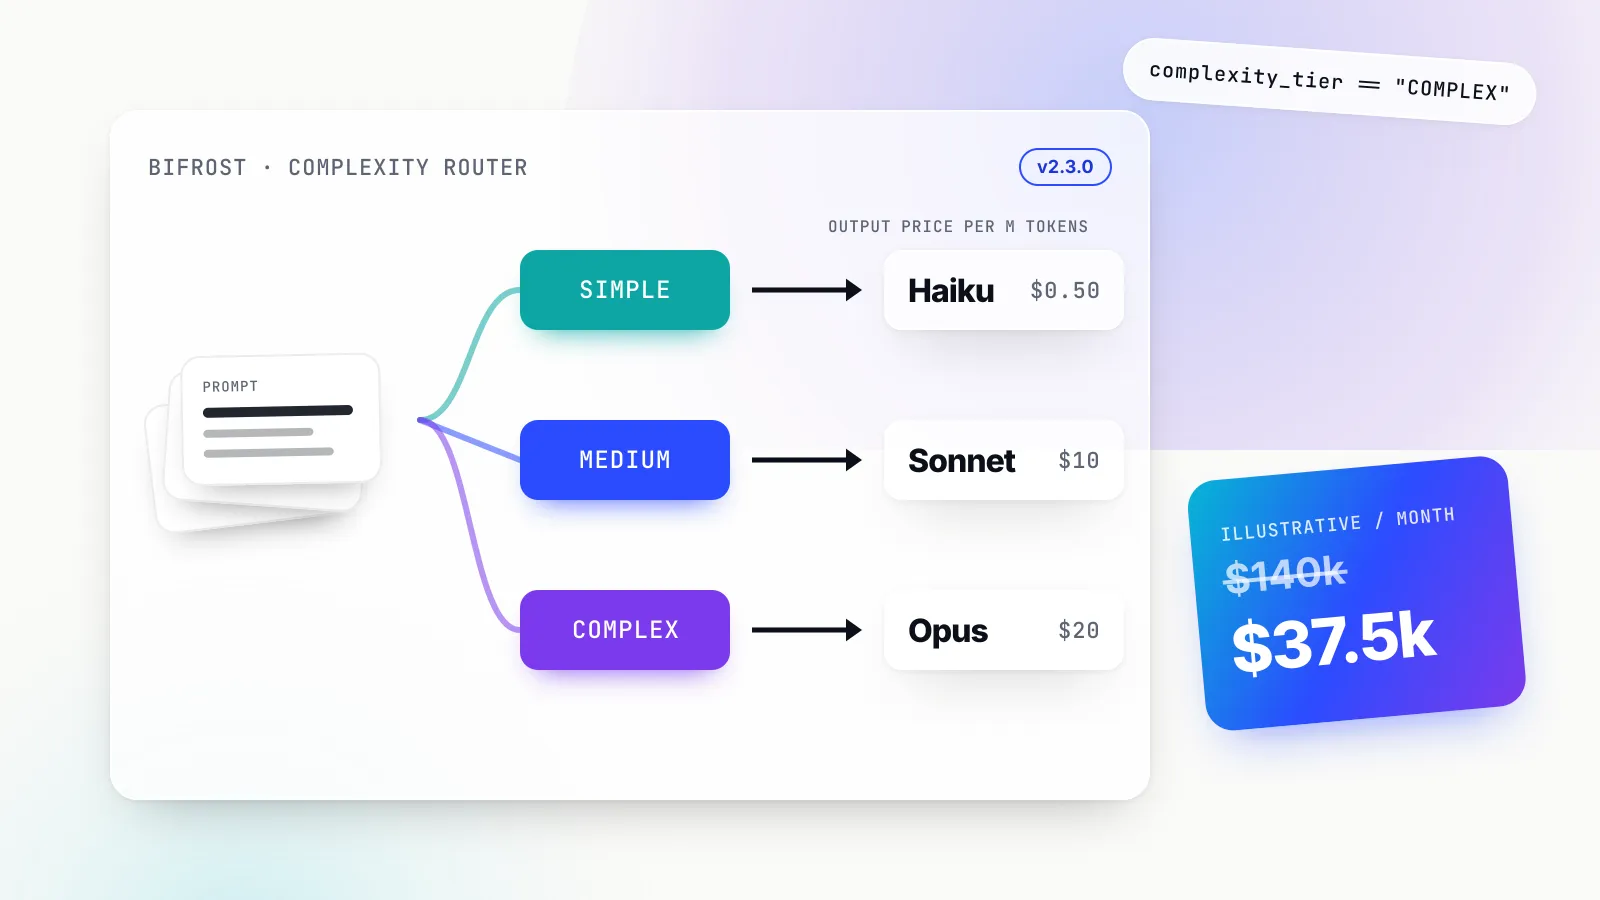
Bifrost now grades each prompt's difficulty before it picks a model
Bifrost's complexity router classifies every request as simple, medium or complex, then lets routing rules send easy work to cheap models and hard work to frontier ones, with no application changes.
ToolsExplainer
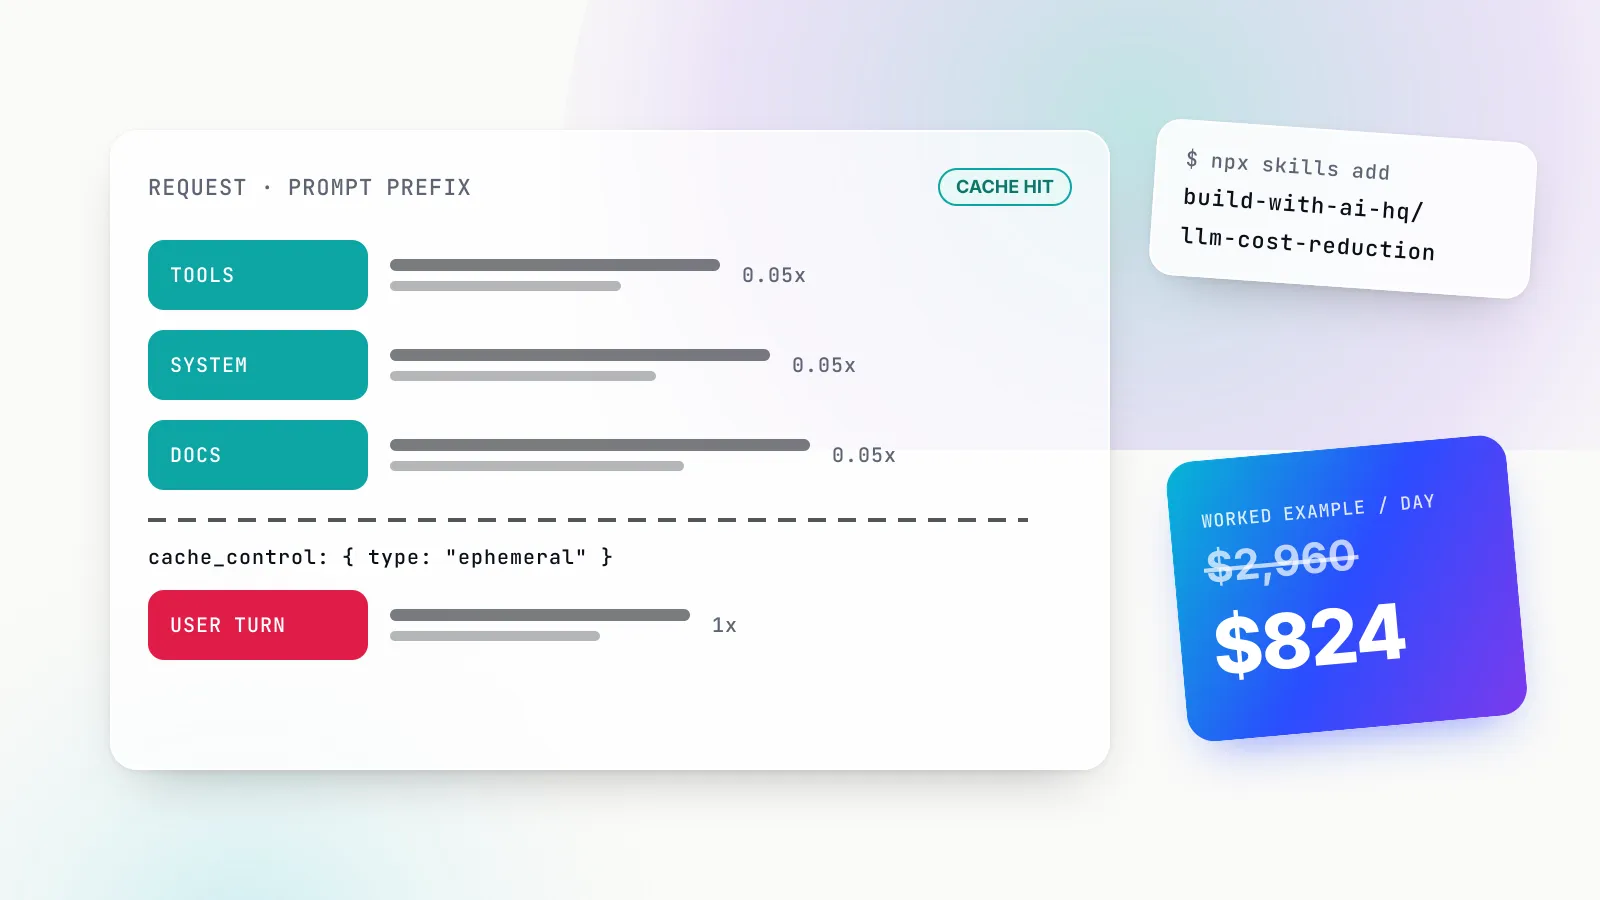
Prompt caching: how it cuts LLM costs at Anthropic, OpenAI and Gemini
Prompt caching bills a repeated prompt prefix at 5 to 10 percent of the input rate. Current provider numbers, why caches miss, a worked cost example and the rest of the LLM cost playbook.
ToolsExplainer
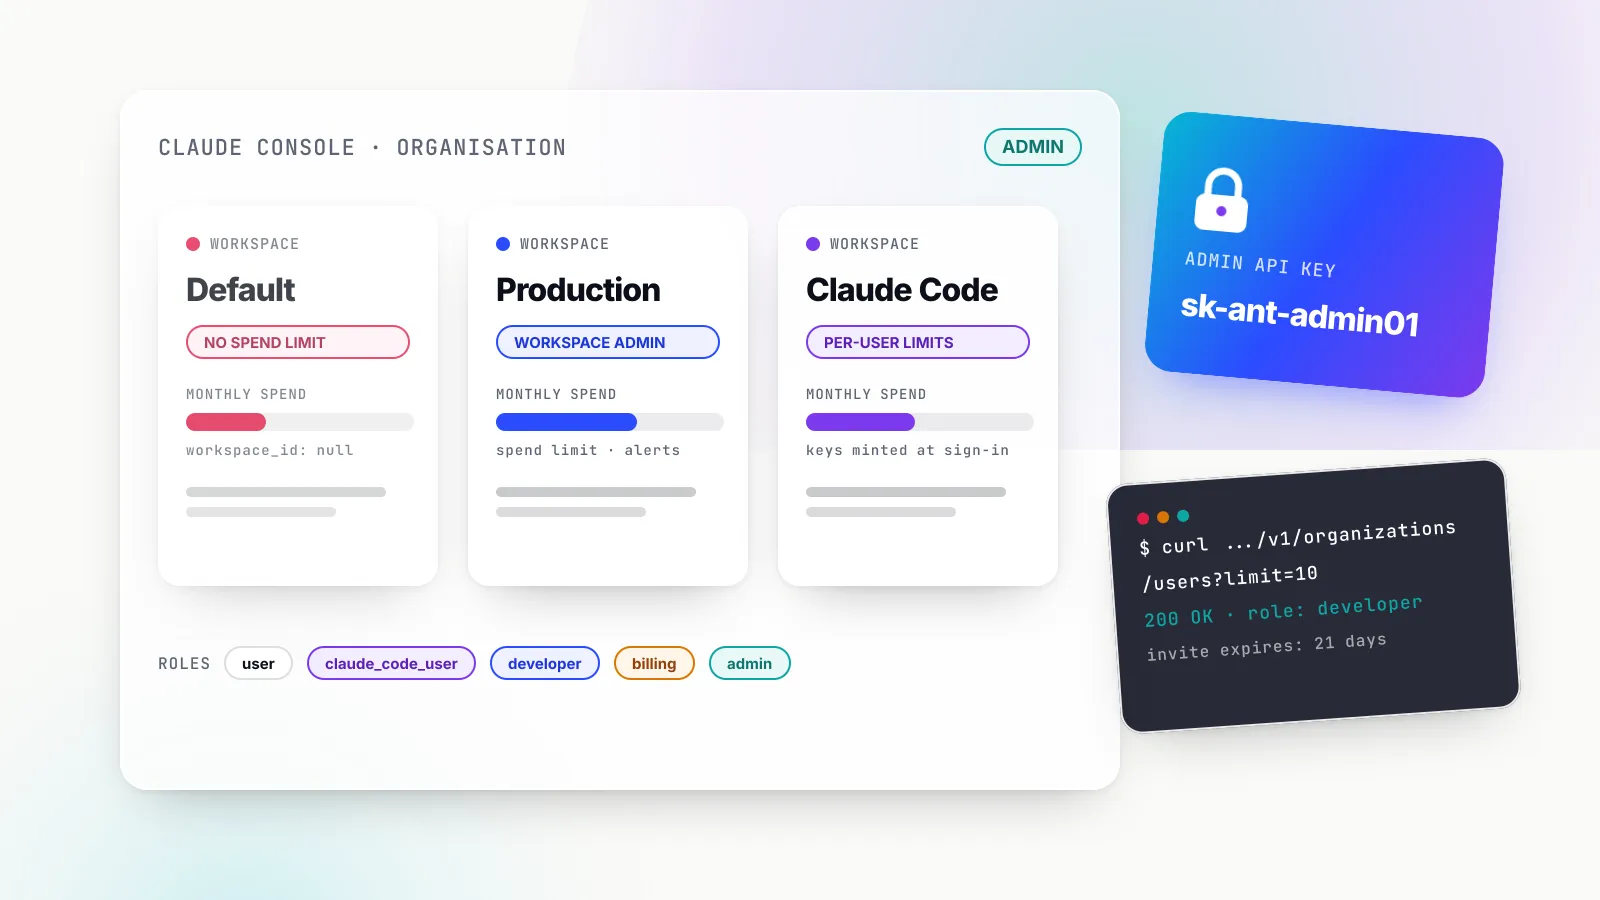
Claude API platform admin: roles, workspaces and the Admin API explained
How to administer the Claude Developer Platform: Console roles, workspaces and their limits, Admin API keys and curl calls, usage and Claude Code reports, SSO and data retention.
ModelsExplainer
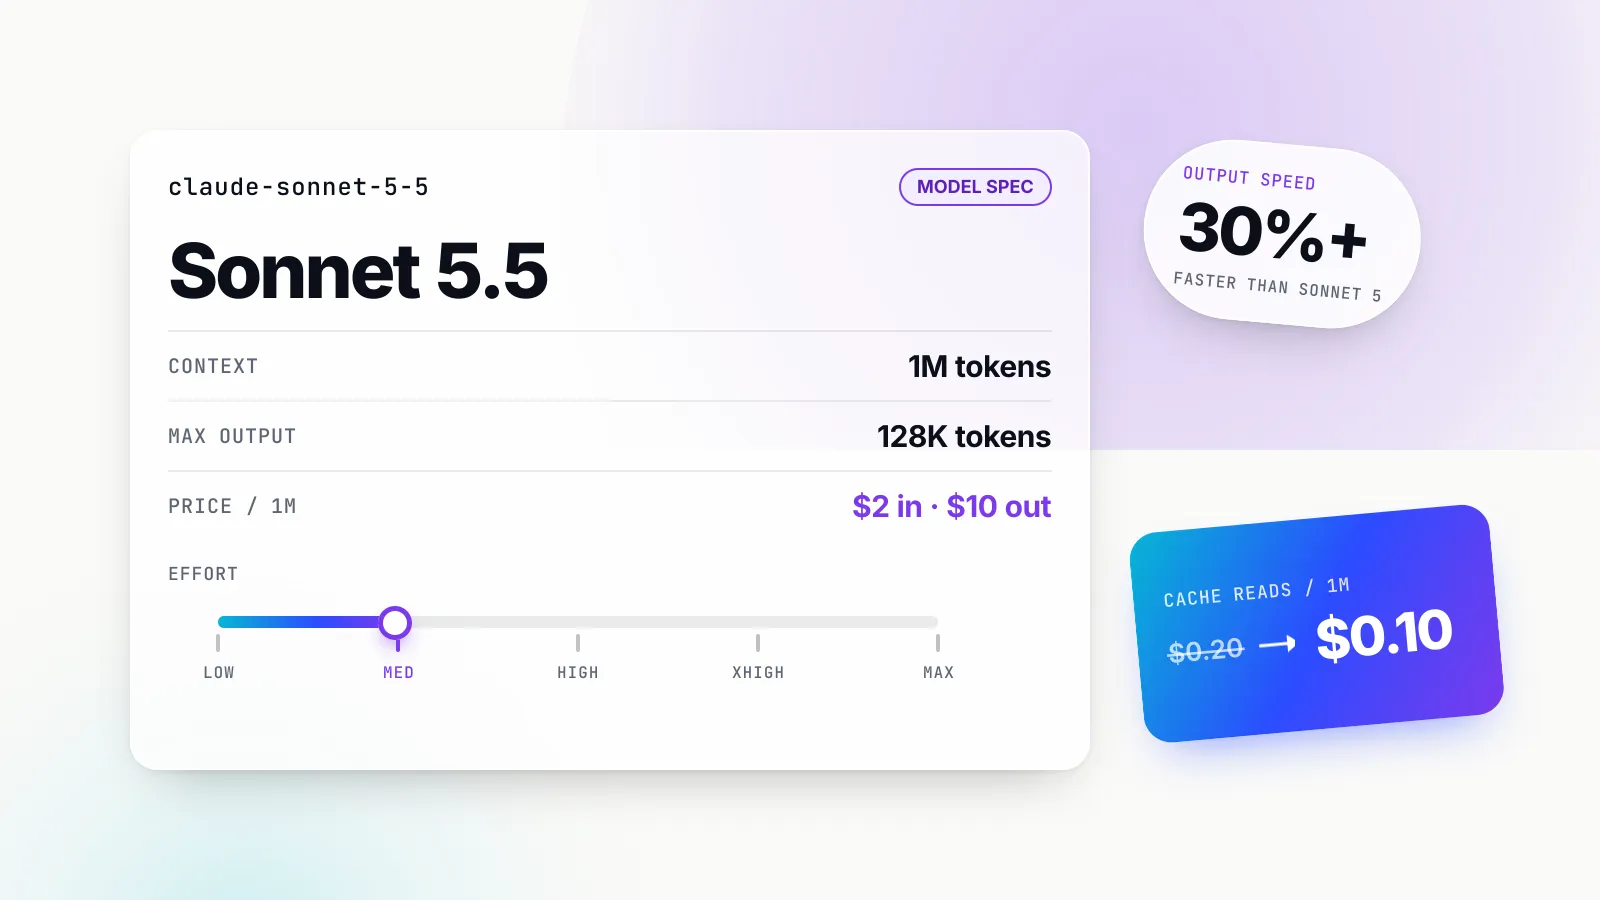
Claude Sonnet 5.5: a practical guide to price, effort, benchmarks and migration
Anthropic's mid-tier model costs $2 in and $10 out per million tokens with a 1M context. What changed from Sonnet 5, when to pick it over Opus 5.5 or Haiku 5.5, and how to migrate.
ToolsExplainer
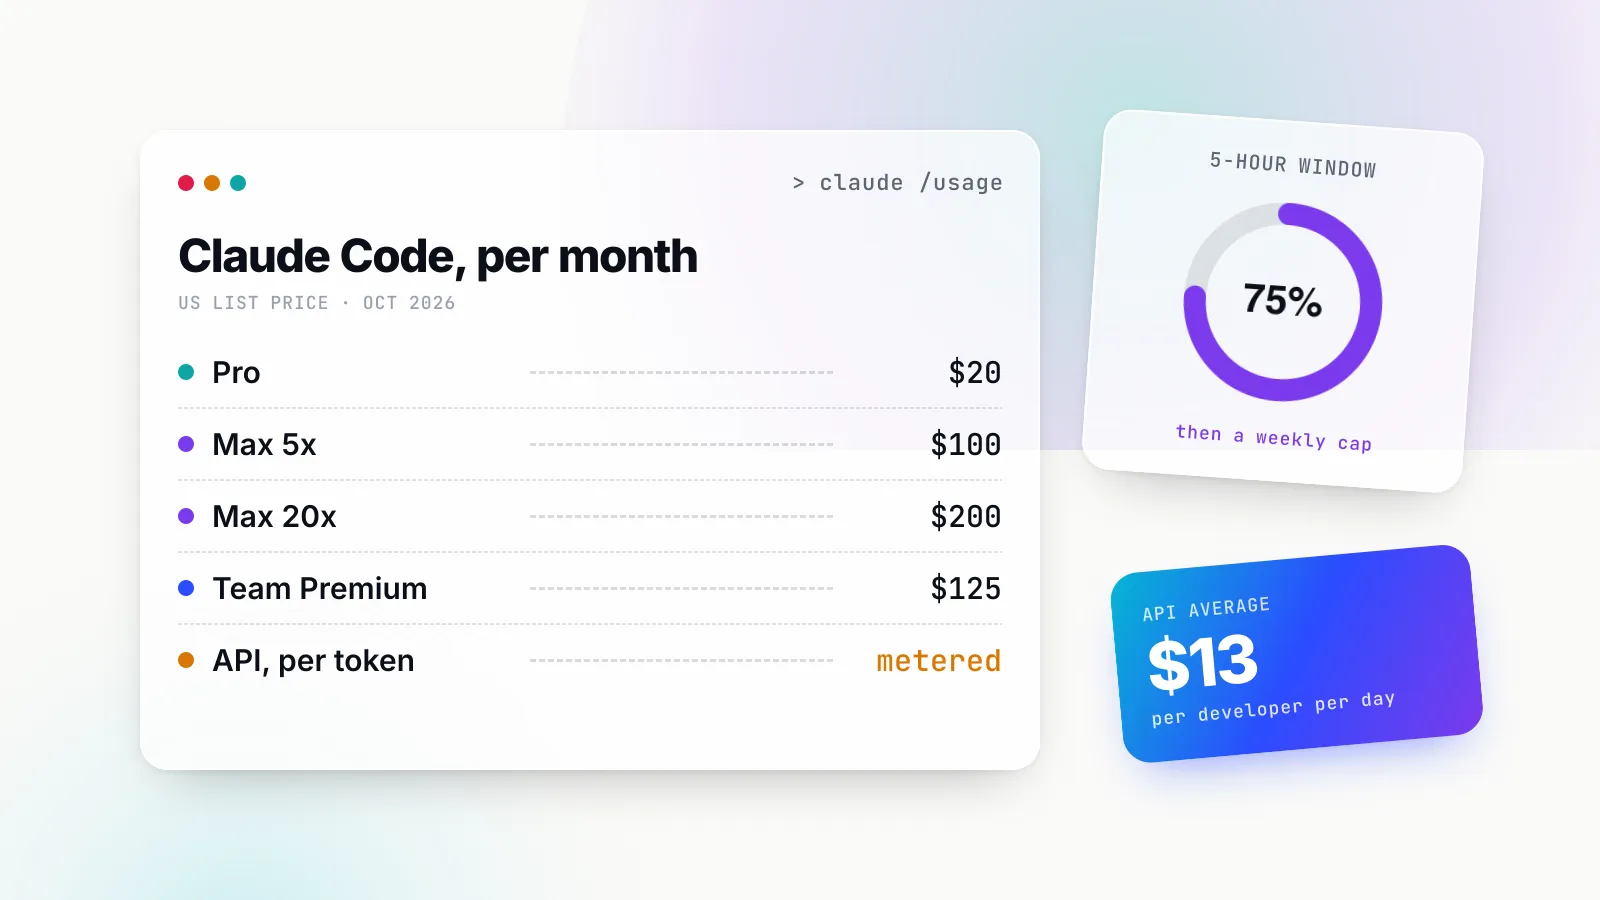
Claude Code pricing: every plan, its usage limits and a developer's real monthly cost
Claude Code pricing as of October 2026: Pro, Max, Team and Enterprise seats, API and cloud rates, how usage limits work, and worked costs per developer.
ToolsComparison
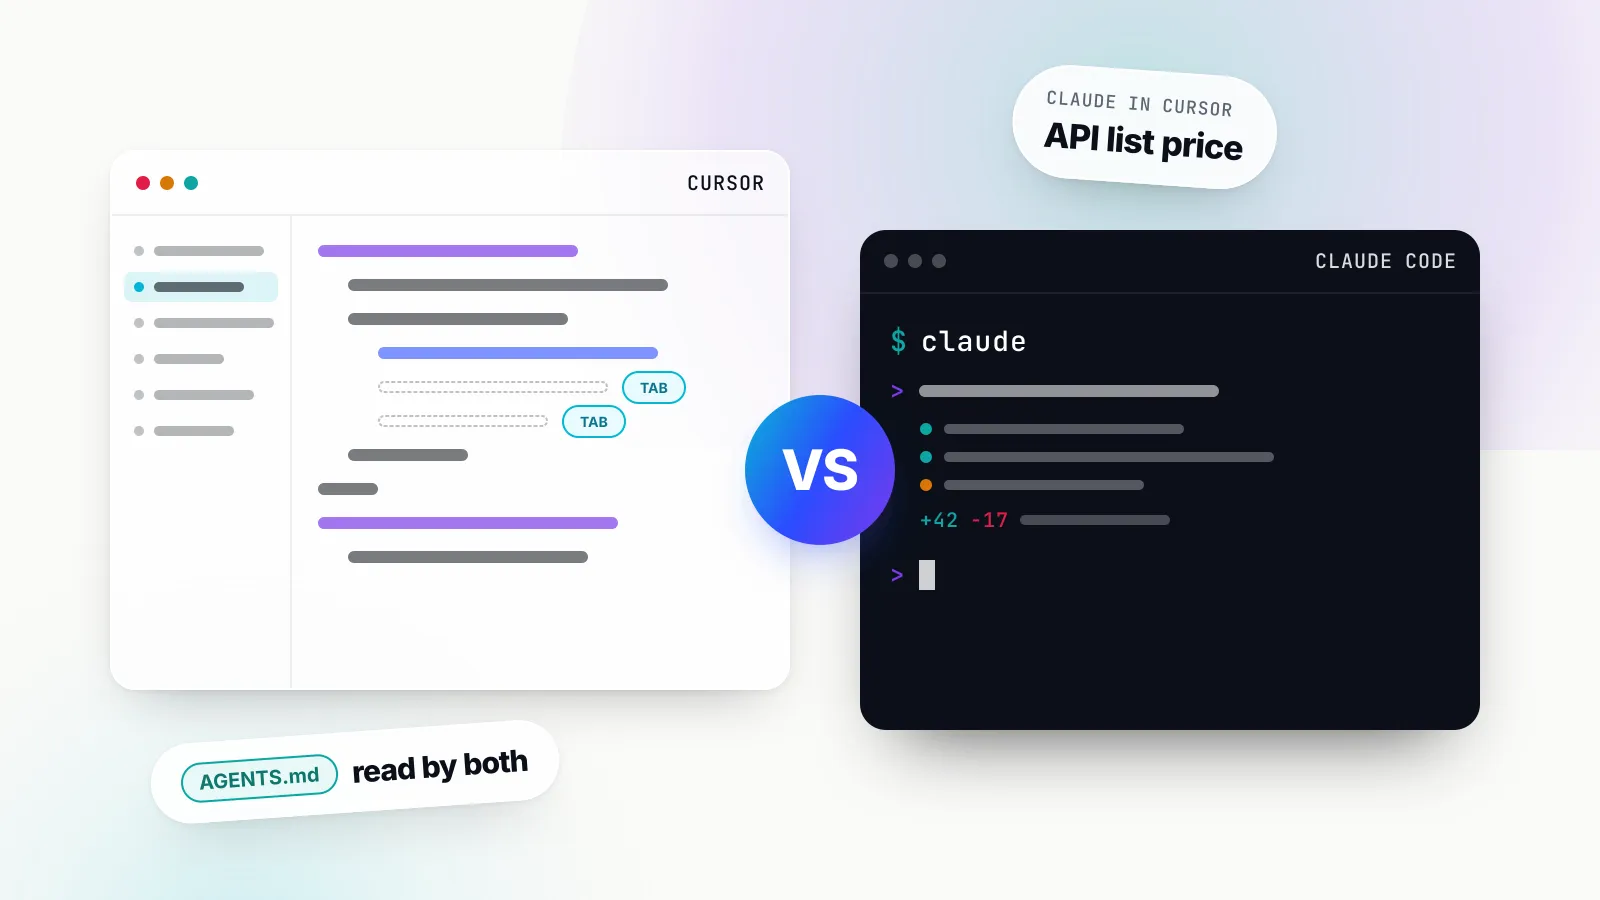
Cursor vs Claude Code in October 2026: IDE agent or terminal agent?
Cursor vs Claude Code compared on workflow, models, cloud agents, context, MCP, skills, team controls and pricing after Cursor's move to The X Subscription.
ModelsComparison
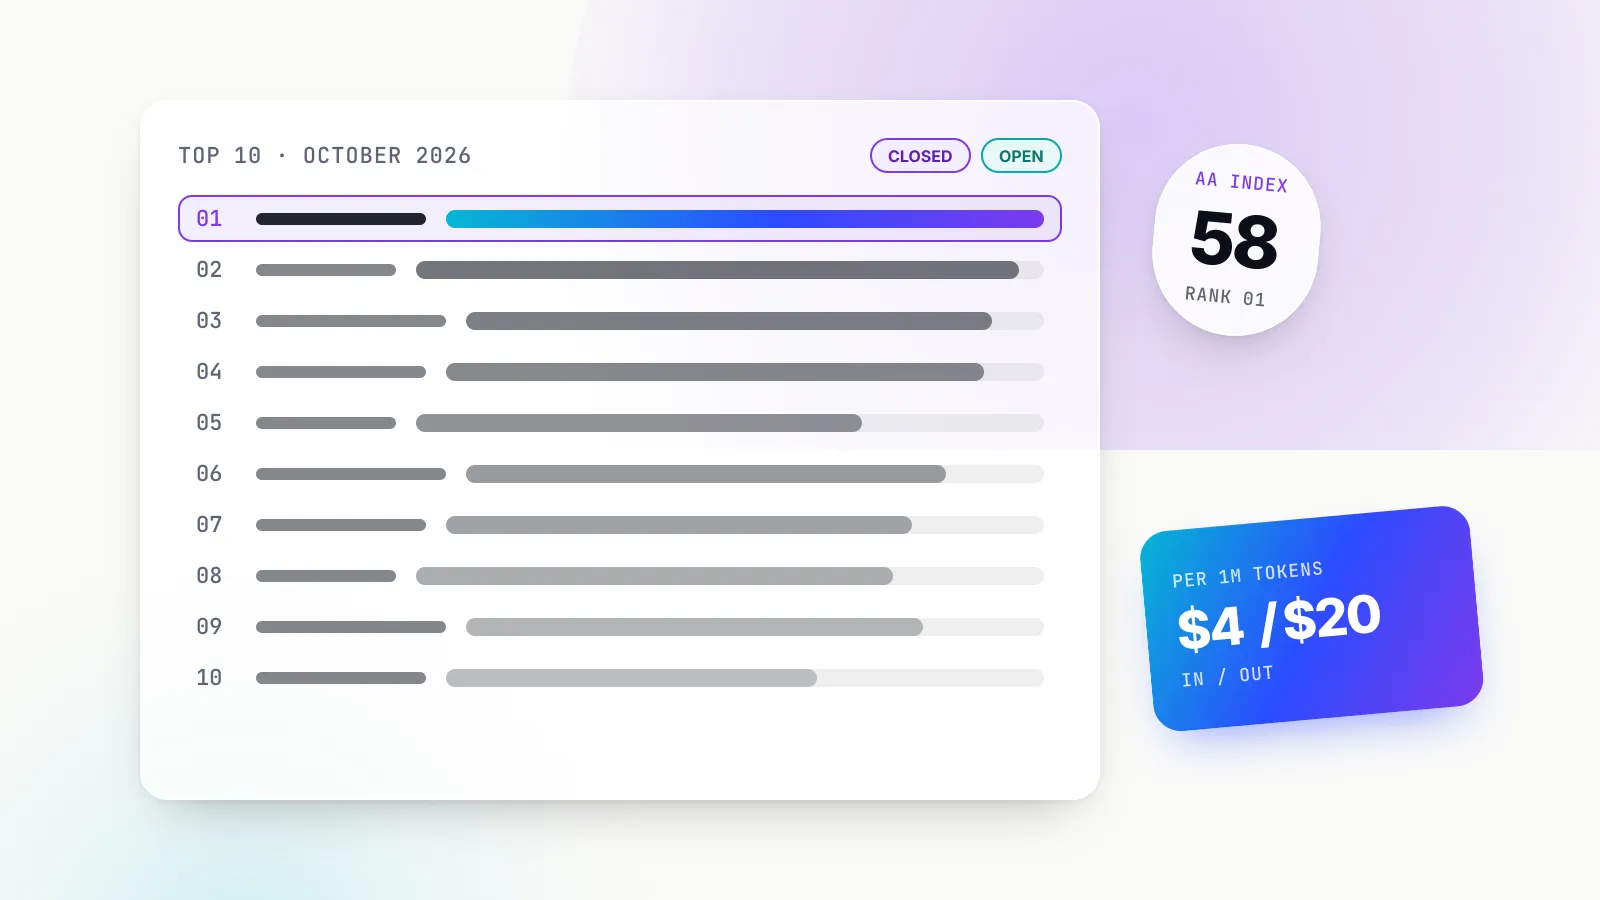
Top 10 AI models in October 2026, ranked by what they are good at
Claude Opus 5.5, GPT-6.1 Sol, Gemini 3.8 Flash, Kimi K3 and six more, ranked on independent evals, coding, context, price and speed, with every figure sourced and dated.
ToolsExplainer
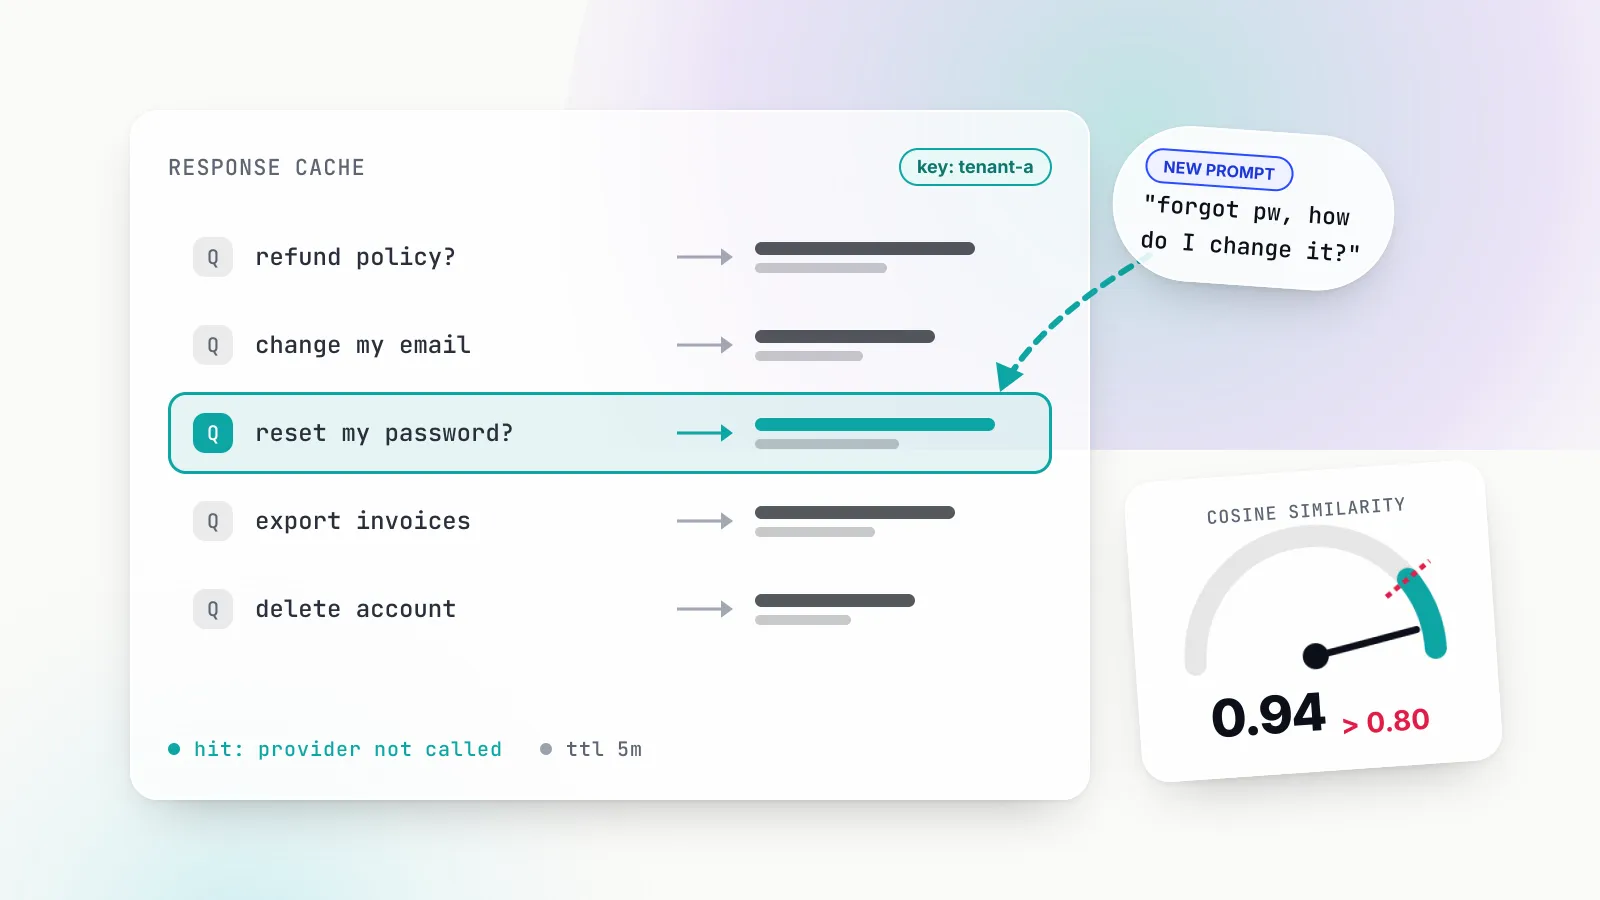
Semantic caching for LLMs: how it works and where it goes wrong
Semantic caching replays a stored LLM answer when a new prompt means the same thing. How thresholds, vector stores and cache keys work, how it differs from prompt caching, and how to measure savings.
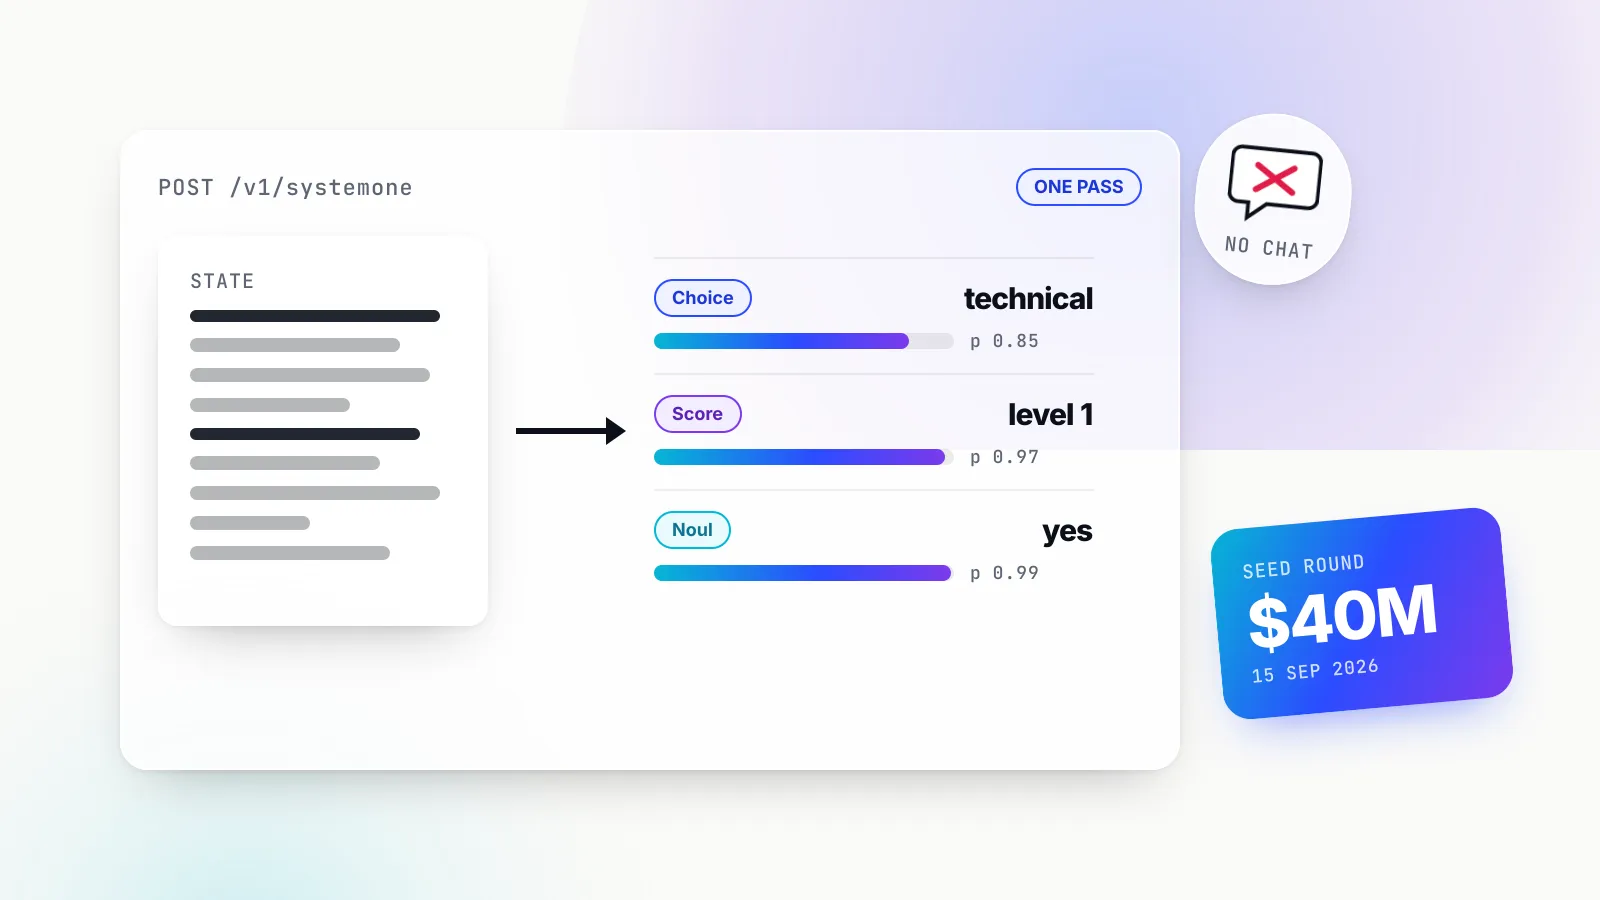
TypeSafe AI launches Jev, a $40M bet on AI that decides instead of chats
Jev takes text state and typed questions and returns calibrated probabilities in one pass, at $0.042 per million input tokens. What launched, who built it, and what the evidence shows so far.
NewsAnalysis
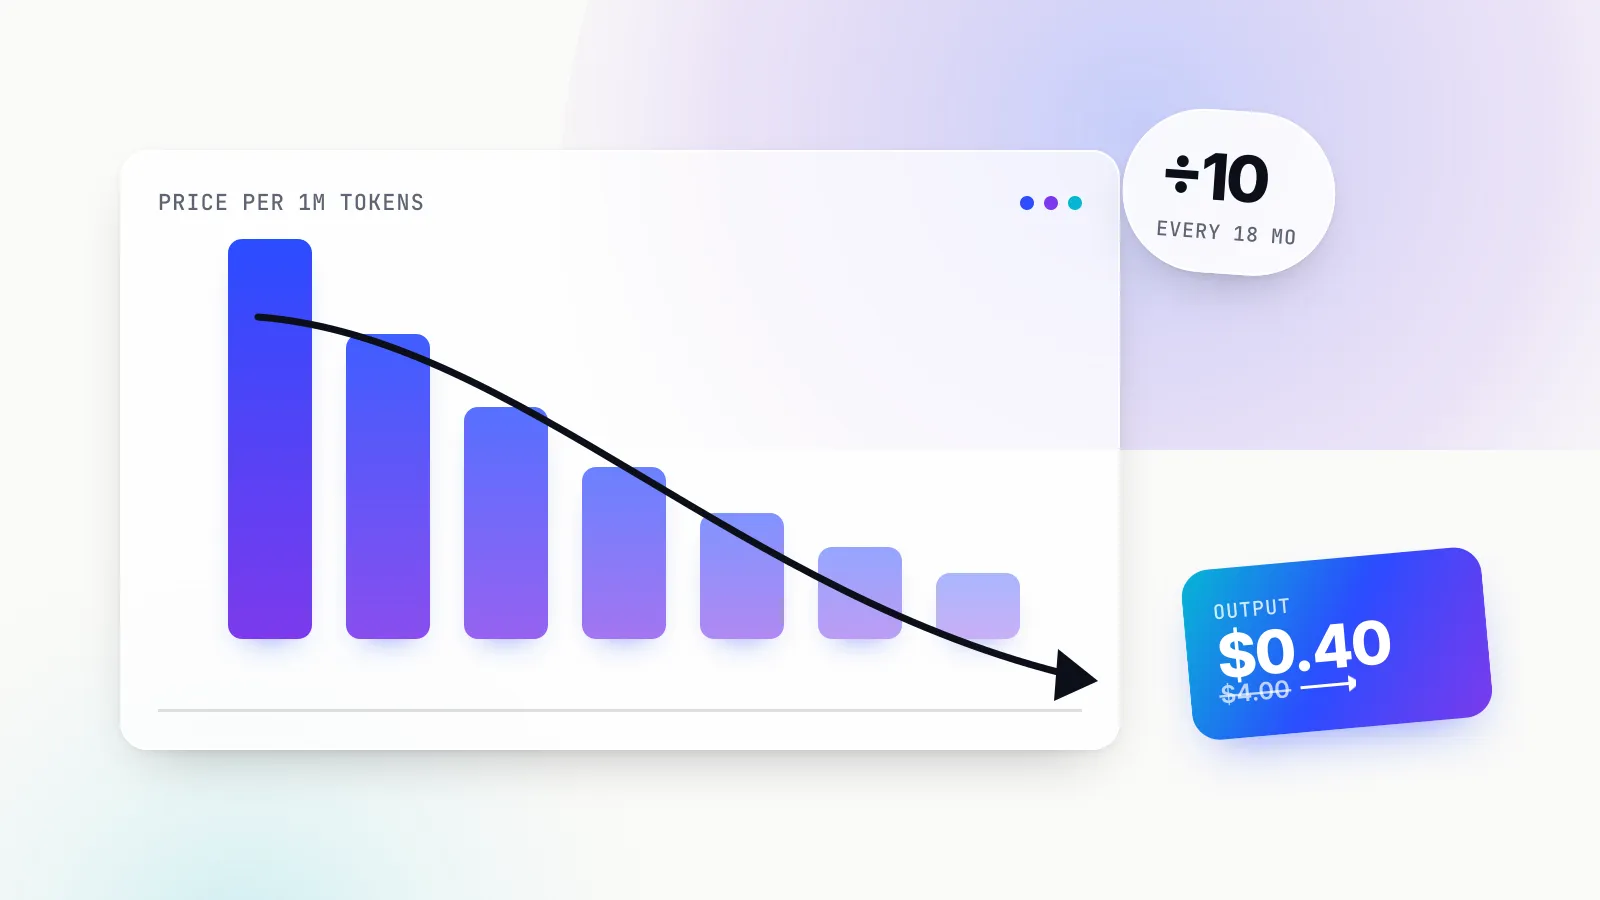
Inference prices keep falling. Here is who actually keeps the saving
Same-capability inference gets 9 to 900 times cheaper a year, per Epoch AI. Whether your bill shrinks depends on tokens per task, caching and lock-in. Twelve models priced as of September 2026.
IndustryExplainer
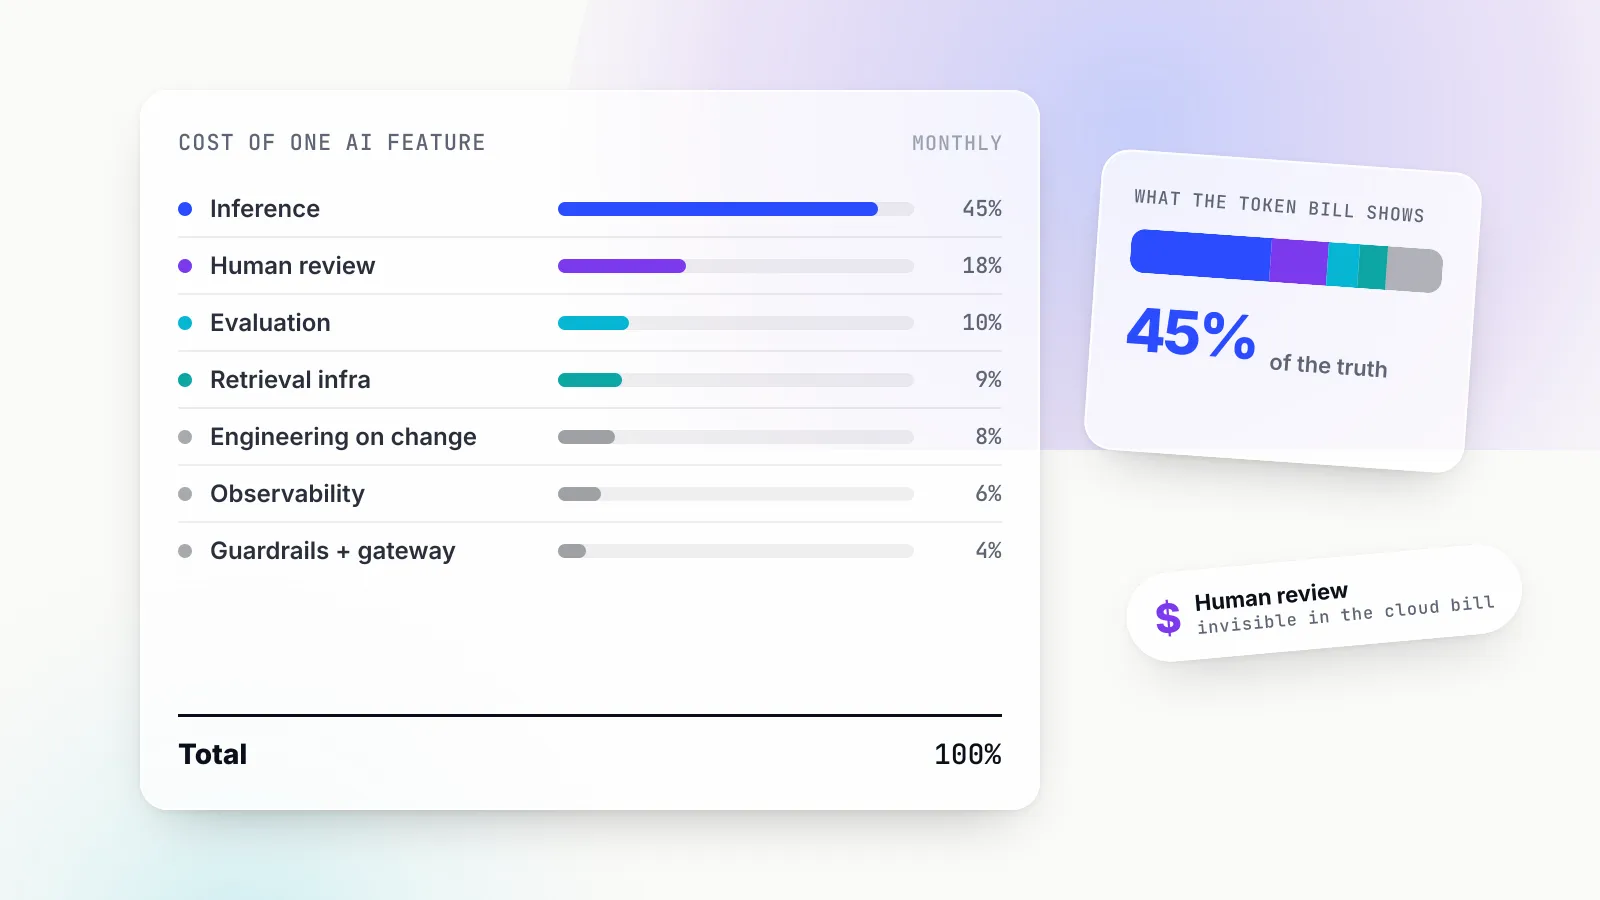
The real cost of an AI product, line by line: tokens are rarely the biggest line
A sourced ledger of what a production AI feature costs in September 2026: inference, retrieval, agents, evaluation, gateways, review and people, with a worked monthly model at three volumes.